Lab claims next to leaderboards
When a lab reports a score for its own model, the benchmark's own leaderboard often lists the same model. We set the two numbers side by side. Most gaps come from how the runs differ: the harness, the effort level, tools, the number of attempts or the task subset. A gap alone doesn't show that a lab overstated anything.
456 of 720 gaps favor the lab, by 1.3 points at the median
Each dot is one model on one benchmark scored in percent, with the lab's number across and the leaderboard's up. Dots on the dashed line agree. Dots below it are where the lab's number is higher. The 512 pairs on the line usually mean one side copied the other, often a leaderboard that lists the lab's own number.
The gray band is within 5 points either way. Colors follow each model's lab, and gray is any lab outside the eight we color.
Sources: Labs’ model cards and official leaderboards
By benchmark
Benchmarks with four or more pairs. A benchmark whose labs run their own harness, such as SWE-bench Verified, shows large gaps for that reason alone.
| Benchmark | Pairs | Same | Lab higher | Lab lower | Median gap |
|---|---|---|---|---|---|
| GPQA Diamond | 128 | 7 | 93 | 28 | +1.6 |
| MMLU-Pro | 62 | 48 | 9 | 5 | +2.9 |
| SWE-bench Verified | 49 | 5 | 38 | 6 | +5.0 |
| MMMU | 39 | 35 | 3 | 1 | +2.4 |
| AIME 2025 | 30 | 1 | 20 | 9 | +1.0 |
| MATH-Vision (MathVision) | 25 | 22 | 0 | 3 | −5.8 |
| Humanity's Last Exam | 21 | 2 | 17 | 2 | +8.3 |
| HumanEval | 20 | 0 | 8 | 12 | −1.2 |
| MCP Atlas | 20 | 7 | 3 | 10 | −3.4 |
| AutomationBench | 19 | 8 | 5 | 6 | −0.9 |
| IFEval | 19 | 0 | 15 | 4 | +4.8 |
| Terminal-Bench 2.0 | 19 | 0 | 9 | 10 | −1.1 |
| ARC-AGI-2 | 18 | 15 | 0 | 3 | −0.7 |
| Toolathlon | 18 | 15 | 1 | 2 | −0.4 |
| DeepSWE | 17 | 7 | 4 | 6 | −0.3 |
| MMMU-Pro | 17 | 14 | 2 | 1 | +1.2 |
| CyberGym | 15 | 10 | 1 | 4 | −12.7 |
| HMMT 2025 | 15 | 2 | 7 | 6 | +0.4 |
| Terminal-Bench 4.0 | 15 | 1 | 10 | 4 | +1.1 |
| Aider Polyglot | 14 | 2 | 9 | 3 | +0.9 |
| MathVista | 14 | 13 | 0 | 1 | −2.9 |
| MBPP | 13 | 0 | 5 | 8 | −4.2 |
| ARC-AGI | 12 | 11 | 0 | 1 | −1.5 |
| Berkeley Function Calling Leaderboard (BFCL) | 11 | 0 | 10 | 1 | +2.5 |
| Harvey LAB (Legal Agent Benchmark) | 11 | 4 | 7 | 0 | +7.1 |
| Agents' Last Exam | 10 | 4 | 6 | 0 | +23.6 |
| FrontierMath | 10 | 3 | 2 | 5 | −0.4 |
| OSWorld-Verified | 10 | 5 | 0 | 5 | −5.6 |
| SimpleQA Verified | 10 | 2 | 7 | 1 | +2.9 |
| BabyVision | 9 | 7 | 1 | 1 | −9.9 |
| Vals Finance Agent v2 | 9 | 8 | 1 | 0 | +1.3 |
| FrontierSWE | 8 | 6 | 1 | 1 | +0.1 |
| MMLongBench-Doc | 8 | 7 | 0 | 1 | −3.8 |
| OpenAI MRCR v2 | 8 | 0 | 7 | 1 | +15.8 |
| RULER | 8 | 7 | 0 | 1 | −4.9 |
| Chartography | 7 | 1 | 5 | 1 | +37.9 |
| FACTS Grounding | 7 | 1 | 2 | 4 | −1.0 |
| GDP.pdf | 7 | 0 | 1 | 6 | −12.0 |
| MultiChallenge | 7 | 1 | 3 | 3 | +1.4 |
| PolyMath | 7 | 7 | 0 | 0 | |
| SimpleQA | 7 | 2 | 1 | 4 | −0.4 |
| SWE-Bench Pro | 7 | 1 | 4 | 2 | +6.9 |
| Terminal-Bench 2.1 | 7 | 0 | 6 | 1 | +4.2 |
| Toolathlon-Verified | 7 | 5 | 0 | 2 | −0.4 |
| Vals Finance Agent | 7 | 3 | 2 | 2 | −0.2 |
| ARC-AGI-3 | 6 | 5 | 0 | 1 | −18.5 |
| CharXiv | 6 | 6 | 0 | 0 | |
| MATH-500 | 6 | 0 | 6 | 0 | +4.4 |
| scBench (LatchBio SingleCellBench) | 6 | 0 | 4 | 2 | +0.8 |
| SWE-bench Multilingual | 6 | 0 | 6 | 0 | +5.8 |
| tau2-bench | 6 | 5 | 1 | 0 | +1.8 |
| ZeroBench | 6 | 4 | 0 | 2 | −9.3 |
| AIME 2026 | 5 | 0 | 2 | 3 | −0.5 |
| BioMysteryBench | 5 | 1 | 4 | 0 | +7.9 |
| Claw-Eval Pass^3 | 5 | 4 | 0 | 1 | −1.2 |
| Cybench | 5 | 4 | 1 | 0 | +24.1 |
| ECLeKTic | 5 | 0 | 5 | 0 | +5.9 |
| ExploitGym | 5 | 4 | 0 | 1 | −8.4 |
| FrontierMath Tier 4 | 5 | 2 | 2 | 1 | +0.5 |
| Global PIQA | 5 | 0 | 5 | 0 | +9.7 |
| HMMT 2026 | 5 | 1 | 2 | 2 | −0.6 |
| HMMT Nov 2025 | 5 | 0 | 4 | 1 | +1.1 |
| OCRBench v2 | 5 | 0 | 5 | 0 | +1.2 |
| OfficeQA Pro | 5 | 0 | 3 | 2 | +6.0 |
| Audio MC | 4 | 4 | 0 | 0 | |
| CursorBench 4.0 | 4 | 4 | 0 | 0 | |
| Daily-Omni | 4 | 3 | 1 | 0 | +2.2 |
| Global MMLU Lite | 4 | 0 | 0 | 4 | −3.8 |
| Human Pathogen Capabilities Test | 4 | 0 | 1 | 3 | −4.3 |
| MMBench | 4 | 0 | 4 | 0 | +4.6 |
| ProgramBench tests passed | 4 | 0 | 4 | 0 | +6.6 |
| PutnamBench | 4 | 1 | 3 | 0 | +1.4 |
| ScreenSpot-Pro | 4 | 2 | 1 | 1 | −3.9 |
| Video-MMMU | 4 | 4 | 0 | 0 | |
| World-Class Bio | 4 | 0 | 1 | 3 | −5.2 |
By lab
Labs with five or more pairs. Labs that report at their highest effort setting, or with their own agent harness, show larger gaps. The median gap counts only the pairs that differ.
| Lab | Pairs | Same | Lab higher | Lab lower | Median gap |
|---|---|---|---|---|---|
| OpenAI | 212 | 65 | 79 | 68 | +0.5 |
| Anthropic | 177 | 54 | 83 | 40 | +2.5 |
 Qwen | 156 | 76 | 63 | 17 | +1.9 |
 Google DeepMind | 147 | 75 | 43 | 29 | +1.1 |
| Moonshot AI | 76 | 29 | 32 | 15 | +0.9 |
 DeepSeek | 70 | 16 | 32 | 22 | +0.3 |
 Meta | 63 | 29 | 26 | 8 | +3.7 |
| Z.ai | 63 | 29 | 20 | 14 | +2.3 |
| xAI | 42 | 17 | 15 | 10 | +1.2 |
 Thinking Machines | 37 | 25 | 6 | 6 | −0.0 |
 ByteDance Seed | 30 | 24 | 4 | 2 | +1.4 |
 MiniMax | 25 | 16 | 8 | 1 | +5.8 |
 Mistral AI | 20 | 3 | 10 | 7 | +0.4 |
 Microsoft | 17 | 8 | 5 | 4 | +0.3 |
 NVIDIA | 16 | 7 | 6 | 3 | +0.7 |
 Tencent | 15 | 8 | 6 | 1 | +2.0 |
| Xiaomi Corp | 12 | 7 | 3 | 2 | +2.7 |
 StepFun | 7 | 4 | 0 | 3 | −1.0 |
 Amazon | 6 | 2 | 2 | 2 | +4.8 |
 Meituan | 6 | 4 | 2 | 0 | +2.6 |
| Reflection | 6 | 0 | 3 | 3 | −0.2 |
 Cohere | 5 | 1 | 2 | 2 | +0.9 |
 Shanghai AI Lab | 5 | 5 | 0 | 0 |
Every pair
The lab's best number for the model, against the leaderboard's best row for it, so both sides are at their best setting. Where a benchmark has no leaderboard, the right side is Epoch AI's own run. Numbers within 0.15 points count as the same, and dollars and ratings within half a unit, since labs often print them whole. A positive gap means the lab's number is better, for lower-is-better tests too. How we pair them.
- All labs
- Ai2 1
- Amazon 6
- Anthropic 183
- Baidu 2
- ByteDance Seed 31
- Cognition 1
- Cohere 5
- DeepSeek 71
- Google DeepMind 175
- IBM 3
- LG AI Research 3
- Liquid AI 1
- Meituan 6
- Meta 63
- Microsoft 20
- MiniMax 26
- Mistral AI 24
- Moonshot AI 79
- Nous Research 1
- NVIDIA 17
- OpenAI 212
- Perplexity 1
- Qwen 169
- Reflection 6
- Shanghai AI Lab 5
- StepFun 7
- Technology Innovation Institute 2
- Tencent 15
- Thinking Machines 43
- Upstage 3
- xAI 46
- Xiaomi Corp 12
- Z.ai 68
Nothing matches.
- Any gap
- Lab number higher 494
- Lab number lower 278
- Same number 535
| Model | Benchmark | Lab says | Board says | Gap | What differs |
|---|---|---|---|---|---|
| Gemini Embedding 2 | MSEB | 73.9 Gemini Embedding 2, speech to text MSEB mRR@10 | 23.5 Leaderboard | +50.4 | |
| DeepSeek V4.1 Flash | Chartography | 78.9% Chartography w/ tools (Pass@1) | 11.6% Leaderboard, max | +67 pts | |
| GLM-5.3-Flash | Chartography | 78% Chartography (w/ Tools) | 16.3% Leaderboard, max | +62 pts | |
| DeepSeek-V4-Flash-Vision-Exp | Chartography | 64.3% Chartography | 11.2% Leaderboard, max | +53 pts | |
| MiniMax-M3 | YC-Bench | $2,100,000 YC-Bench | $999,506 Leaderboard | +$1,100,494 | |
| DeepSeek-V4-Pro | OpenAI MRCR v2 | 83.5% MRCR 1M (MMR), OpenAI MRCR, DS-V4-Pro Max (Table 6). Figure 9 prints 8-needle MMR by context length | 33.2% Leaderboard, 8-needle, 128K to 256K bin, enabled reasoning | +50 pts | |
| Claude Opus 4.8 | Vending-Bench 2 | $2,992 Vending-Bench 2 final balance at max effort ($5,787.43 at high effort), run by Andon Labs (8.13.5) | $5,787 Leaderboard, high | −$2,795 | The lab reports max reasoning effort, while the board selects high reasoning effort. |
| Inkling 2 Small | APEX-Accounting | 14.5% Apex-Accounting v1.1 pass@1 (mean score 62.0) | 62% Leaderboard, loop_agent | −48 pts | |
| Seed2.1 Pro | $OneMillion-Bench | 68.8% OneMillion Bench (Table 1) | 23.7% Leaderboard | +45 pts | |
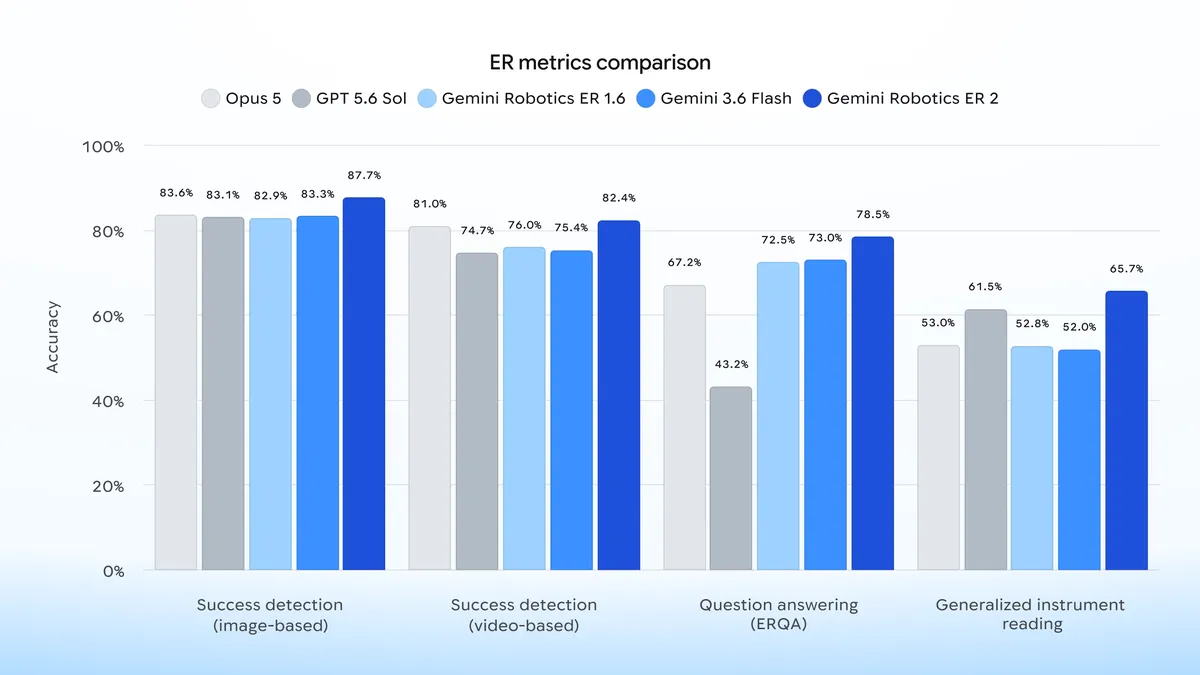
| Gemini Robotics-ER 1.6 | Instrument reading (Google DeepMind) | 93% Instrument Reading w/ agentic vision | 52.8% Leaderboard | +40 pts | |
| Phi-4 Mini | Berkeley Function Calling Leaderboard (BFCL) | 70.3% BFCL (0-shot), version not stated (Table 7) | 31.3% Leaderboard, prompted | +39 pts | |
| gpt-oss-120b | SWE-bench Verified | 62.4% SWE-Bench Verified, high reasoning (Table 3; n=477 Preparedness chart prints 62%) | 26% Leaderboard, mini-SWE-agent | +36 pts | OpenAI evaluates a fixed 477-task subset, while the board uses mini-SWE-agent on the 500-task Verified benchmark. |
| Claude Fable 5.1 | GDP.pdf | 85.4% GDP.pdf mean criteria pass rate, no tools, Claude Opus 4.7 judge; 85.1% with tools (8.14.4) | 49.4% Leaderboard, adaptive/max | +36 pts | |
| Claude Opus 4.7 | OfficeQA Pro | 80.6% OfficeQA Pro, exact-match grading (Table 8.1.A, 8.10.1) | 46.6% Leaderboard, Claude Agent SDK | +34 pts | |
| Nova 2 Lite | BFCL V4 | 60.3% BFCL v4 Overall FC | 27.1% Leaderboard, native function calling | +33 pts | |
| Gemini 2.5 Flash Jun 2025 | SWE-bench Verified | 60.4% SWE-Bench Verified | 28.7% Leaderboard, mini-SWE-agent | +32 pts | Google uses its internal coding agent, while the board uses mini-SWE-agent. |
| Gemini 4 Carbon | Agents' Last Exam v1.1 | 77.4% Agents' Last Exam v1.1 (Score) | 45.9% Leaderboard, high, ALE-Claw | +32 pts | |
| Leanstral | FLTEval | 31.9 FLTEval score, Leanstral pass@16 (pass@1 21.9) | 21.9 Leaderboard, Mistral Vibe | +10.0 | The lab reports success across sixteen attempts, while the board reports single-attempt success. |
| Llama 3.1-70B | Berkeley Function Calling Leaderboard (BFCL) | 84.8% BFCL, 0-shot, acc, instruction tuned (Instruction tuned models table) | 53.6% Leaderboard, prompted | +31 pts | |
| GPT-6 Astra | SRE-Bench | 88% SRE-Bench, pass@4 (pass@1 88.0%, printed chart label) (10.1.2.3, Figure 50) | 56.9% Leaderboard | +31 pts | |
| Tencent Hy4 preview | $OneMillion-Bench | 65.4% OneMillionBench (with tools) | 35.3% Leaderboard | +30 pts | |
| Muse Spark 1.3 | AutomationBench | 49.6% AutomationBench (E2E business workflows) | 20.7% Leaderboard, max | +29 pts | |
| Kimi K2.6 | BabyVision | 39.8% BabyVision | 68.5% Leaderboard, tools | −29 pts | The lab score excludes Python tools, while the board reports the Python-enabled run. |
| o1-preview | GPQA Diamond | 78.3% GPQA Diamond cons@64 | 50.3% Epoch AI run | +28 pts | The lab reports consensus across 64 responses, while Epoch averages scores from individual responses. |
| Qwen2.5-VL-72B | AndroidWorld | 35% AndroidWorld_SR | 62.9% Leaderboard, MobileUse | −28 pts | The lab evaluates Qwen's visual agent, while the board pairs Qwen2.5-VL-72B with the MobileUse agent. |
| Claude Haiku 5.5 | Humanity's Last Exam | 57.4% Multidisciplinary reasoning Humanity's Last Exam (with tools) | 30.1% Leaderboard | +27 pts | |
| Inkling 2 Small | Tax Agent Bench | 65.8% Tax Agent Bench, 65.8% | 38.9% Leaderboard | +27 pts | |
| Qwen 3.6 35B-A3B | Terminal-Bench 2.0 | 51.5% Terminal-Bench 2.0 (Terminus-2, avg of 5) | 24.6% Leaderboard, little-coder | +27 pts | Qwen uses Terminus-2 with a three-hour timeout, while the compared leaderboard entry uses little-coder. |
| Qwen1.5-72B | HumanEval | 41.5% HumanEval | 68.3% Leaderboard | −27 pts | |
| Qwen3-Max | VITA-Bench | 40.9% Vita Bench | 14.3% Leaderboard, non-thinking | +27 pts | The lab reports Qwen3-Max-Thinking, while the board evaluates Qwen3-Max without thinking. |
| Gemini 3.8 Flash | BioMysteryBench | 88.8% Best of BioMysteryBench, Human Solvable / BioMysteryBench, Human Difficult | 62.2% Leaderboard, Vals AI harness, v11 full set | +27 pts | |
| GPT-5.4 | OpenAI MRCR v2 | 79.3% OpenAI MRCR v2 8-needle 128K-256K (36.6% at 512K-1M) | 52.7% Leaderboard, 8-needle, 128K to 256K bin, medium reasoning | +27 pts | |
| Llama 3.1-8B | Berkeley Function Calling Leaderboard (BFCL) | 76.1% BFCL, 0-shot, acc, instruction tuned (Instruction tuned models table) | 49.6% Leaderboard, prompted | +27 pts | |
| Muse Ember | GDP.pdf | 22.8% GDP.pdf-AA, Muse Ember max reasoning | 49.2% Leaderboard, max | −26 pts | |
| DeepSeek-V3 | HumanEval | 65.2% HumanEval (Pass@1) | 91.5% Leaderboard | −26 pts | |
| GPT-6 Luna | Agents' Last Exam | 50.9% Agents' Last Exam (GPT-6 Luna max) | 25% Leaderboard, max, codex | +26 pts | |
| Kimi K2.5 | Humanity's Last Exam | 50.2% Best of HLE-Full / HLE-Full (w/ tools) | 24.4% Leaderboard | +26 pts | |
| GPT-5.2 | SWE-Bench Pro | 55.6% SWE-Bench Pro (public) Software engineering | 29.9% Leaderboard, SWE-agent | +26 pts | |
| GPT-6 Astra | Agents' Last Exam | 59.3% Agents' Last Exam | 34.2% Leaderboard, max, codex | +25 pts | |
| Qwen3-235B-A22B | Creative Writing v3 | 84.6 Creative Writing v3 | 63.8 Leaderboard | +20.8 | |
| Claude Opus 4.6 | CyberGym | 66.6% CyberGym targeted vulnerability reproduction, pass@1 over 1,507 tasks, no thinking with think tool (2.17) | 91% Leaderboard, dynamic, mneme | −24 pts | The lab used its think-tool evaluation, while the board reports the later mneme agent running in a cleaned vulnerable Docker environment. |
| Mistral Large | HumanEval | 45.1% HumanE (pass@1) | 69.5% Leaderboard | −24 pts | |
| GPT-6 Sol | Agents' Last Exam | 56.4% Agents' Last Exam V1 (GPT-6 Sol max) | 32.2% Leaderboard, xhigh, codex | +24 pts | |
| Claude 3.7 Sonnet | Cybench | 44.1% Cybench, succeeded at least once on 15/34 challenges tested (pass@k over up to 30 trials). Best-of-k curve on a 30-challenge subset has no printed values (7.3.2, Figure 25) | 20% Leaderboard | +24 pts | Anthropic counts challenges solved at least once across up to 30 trials, while the board counts eight solved challenges in its run. |
| Qwen3.5-4B | MultiChallenge | 49% MultiChallenge | 25.1% Leaderboard, thinking | +24 pts | |
| o1-preview | SWE-bench Verified | 41.4% SWE-bench Verified, pass@1, Agentless 5-try scaffold, final o1-preview model per text (near-final post-mitigation 28.4% on n=477 subset) (4.5.2) | 64.6% Leaderboard, W&B Programmer O1 crosscheck5 | −23 pts | The lab used an Agentless five-try scaffold, while the board reports W&B Programmer O1 crosscheck5. |
| GPT-5.6 Sol | Agents' Last Exam | 53.6% Agents' Last Exam (Sol, xhigh, code mode) | 30.6% Leaderboard, xhigh, codex | +23 pts | |
| Claude Opus 5.5 | Chartography | 89% Visual chart recognition Chartography (with tools) | 66.3% Leaderboard, adaptive/max | +23 pts | |
| Magistral Small 1.2 | GPQA Diamond | 70.1% GPQA Diamond | 47.6% Epoch AI run | +22 pts | |
| GPT-5.6 Terra | Agents' Last Exam | 50.4% Agents' Last Exam | 28% Leaderboard, max, codex | +22 pts | |
| GPT-5.6 Terra | OpenAI MRCR v2 | 89.6% OpenAI MRCR v2 8-needle 256K-512K 89.6 (512K-1M 72.5) | 67.9% Leaderboard, 8-needle, 128K to 256K bin, max reasoning | +22 pts | |
| GPT-4 Mar 2023 | HumanEval | 67% HumanEval (0-shot) | 88.4% Leaderboard | −21 pts | |
| Qwen 3.6 Plus | SWE-bench Verified | 78.8% SWE-bench Verified | 57.9% Epoch AI run, 2026-04-02 | +21 pts | Qwen uses its internal coding scaffold, while Epoch uses its own tool loop and a validated 484-task subset. |
| GPT-5.6 Luna | Agents' Last Exam | 50.3% Agents' Last Exam | 30.3% Leaderboard, xhigh, codex | +20 pts | |
| Claude Opus 4 | AIME 2025 | 90% High school math competition AIME 2025 (parallel test-time compute) | 70% Leaderboard, thinking | +20 pts | The lab used parallel test-time compute, while MathArena averages separate individual runs. |
| GPT-5 nano | SWE-bench Verified | 54.7% SWE-bench Verified (477 of 500 tasks) | 34.8% Leaderboard, medium, mini-SWE-agent | +20 pts | The lab evaluates 477 tasks, while the board reports a mini-SWE-agent run at medium reasoning effort. |
| GPT-6.1 Sol | GDP.pdf | 32% GDP.pdf (GPT-6.1 Sol High) | 51.6% Leaderboard, max | −20 pts | |
| GPT-5.4 Mini | OpenAI MRCR v2 | 47.7% OpenAI MRCR v2 8-needle, 64K-128K | 28.3% Leaderboard, 8-needle, 128K to 256K bin, high reasoning | +19 pts | |
| GPT-4o May 2024 | SWE-bench Verified | 19% SWE-Bench Verified (n=477), pass@1, best available post-training and public scaffolds (3.8) | 38.4% Leaderboard, AutoCodeRover | −19 pts | The lab reports pass@1 on 477 tasks, while the AutoCodeRover board entry uses multiple attempts on the full Verified set. |
 Falcon H1R 7B | HMMT 2025 | 64.9% HMMT-25 | 84.2% Leaderboard | −19 pts | |
| Qwen1.5-72B | MBPP | 53.4% MBPP | 72.5% Leaderboard, EvalPlus subset, original tests | −19 pts | |
| Claude Opus 4.6 | Humanity's Last Exam | 53% Multidisciplinary reasoning Humanity's Last Exam (with tools) | 34.4% Leaderboard, max | +19 pts | |
| Claude Opus 4.7 | Humanity's Last Exam | 54.7% Multidisciplinary reasoning Humanity's Last Exam (with tools) | 36.2% Leaderboard | +19 pts | |
| Claude Fable 5.1 | Humanity's Last Exam | 65% Multidisciplinary reasoning Humanity's Last Exam (with tools) | 46.5% Leaderboard, xhigh | +19 pts | |
| Claude Fable 5.2 | ARC-AGI-3 | 79.3% ARC-AGI-3, verified headline Standard harness score, High effort. Provider Adapter 97.72% at High. At Max: Standard 65.66%, Provider Adapter 94.90% (Section 8.15) | 97.7% Leaderboard, high, Provider Adapter | −18 pts | |
| Devstral 2 | SWE-bench Verified | 72.2% SWE-bench Verified | 53.8% Leaderboard, mini-SWE-agent | +18 pts | |
| Claude Sonnet 5.5 | Humanity's Last Exam | 64.5% Multidisciplinary reasoning Humanity's Last Exam (with tools) | 46.1% Leaderboard, xhigh | +18 pts | |
| Claude Opus 5 | ProgramBench tests passed | 93% ProgramBench hidden test pass rate on 166 of 200 tasks after five 1M-token episodes, single agent (83% after the first episode) (8.9.1) | 74.7% Leaderboard, xhigh, mini-SWE-agent | +18 pts | The lab used five million-token episodes on 166 filtered tasks, while the board evaluates mini-SWE-agent on the full benchmark. |
| Kimi K3 | ZeroBench | 23% ZeroBench (pass@5) (without python) | 41% Leaderboard, w/ tools; externally reported: Kimi K3 report; Python tools; 5 samplings. | −18 pts | |
| MiMo-V2-Omni | Claw-Eval | 54.8% Claw Eval | 72.4% Leaderboard | −18 pts | |
| Claude Opus 4.8 | OfficeQA Pro | 66.2% OfficeQA Pro, 133 questions, internal agentic harness, exact match (8.13.1) | 48.9% Leaderboard, Claude Agent SDK | +17 pts | Anthropic uses an internal agentic harness, while Databricks evaluates Opus 4.8 through Claude Agent SDK. |
| Claude Opus 4.6 | MCP Atlas | 59.5% Scaled tool use MCP Atlas | 76.8% Leaderboard, max | −17 pts | |
| Gemini 2.0 Flash Thinking Jan 2025 | GPQA Diamond | 74.2% GPQA Diamond (Science) | 57.1% Epoch AI run | +17 pts | |
| Claude Opus 5 | Harvey LAB (Legal Agent Benchmark) | 23.6% Legal Agent Benchmark (Harvey LAB), all-pass rate on 1,235 public problems, max effort, internal harness, production safeguards, mean criterion pass rate 93.74%. Harvey's held-out set: 11.7% all-pass, 94.1% mean criterion (8.13.3) | 6.67% Leaderboard | +17 pts | Anthropic evaluates 1,235 public problems, while Vals evaluates Harvey's private holdout with its benchmark harness. |
| Qwen3.5-4B | Global PIQA | 78.9% Global PIQA | 62.1% Leaderboard, exact_match,strict_match; instruct | +17 pts | |
| Gemini 3 Flash | Terminal-Bench 2.0 | 47.6% Terminal-bench 2.0 (Terminus-2 harness) | 64.3% Leaderboard, Junie CLI | −17 pts | Google uses the Terminus-2 harness, while the board pairs Gemini 3 Flash with Junie CLI. |
| Janus-Pro-7B | MMBench | 79.2% MMB | 62.6% Leaderboard | +17 pts | |
| Hermes 4 405B | Creative Writing v3 | 79.8 CreativeWriting3 (reasoning) | 66.7 Leaderboard | +13.1 | |
| GPT-5.4 | Humanity's Last Exam | 52.1% Humanity's Last Exam with tools 52.1% (without tools 39.8%) | 36.2% Leaderboard, xhigh thinking | +16 pts | |
| Claude Sonnet 4.5 | AIME 2025 | 100% High school math competition AIME 2025 (python) | 84.2% Leaderboard, thinking | +16 pts | |
| Devstral Small 1.1 | SWE-bench Verified | 53.6% SWE-Bench Verified | 38% Leaderboard, SWE-agent | +16 pts | Mistral evaluates Devstral Small 1.1 with OpenHands, while the board uses SWE-agent. |
| GPT-5.2 Codex | SWE-Bench Pro | 56.4% SWE-Bench Pro | 41% Leaderboard, SWE-agent | +15 pts | |
| Grok 4.5 | τ³-bench Banking | 32.6% τ³-banking (AA), accuracy, high (4.2) | 47.9% Leaderboard, high | −15 pts | xAI quotes Artificial Analysis's run of the same tasks, with its own user simulator and judge. The board shows Sierra's own runs. |
| GLM-5.1 | CyberGym | 68.7% CyberGym | 84% Leaderboard, dynamic, Xuanwu Atuin AI | −15 pts | The lab uses Claude Code, while the board pairs GLM-5.1 with Tencent's Xuanwu Atuin AI agent. |
| Gemini 3 Pro | Terminal-Bench 2.0 | 54.2% Terminal-Bench 2.0 (Terminus-2 agent) | 69.4% Leaderboard, Ante | −15 pts | The lab used Terminus-2, while the board reports the Ante agent. |
| GPT-4.1 | SWE-bench Verified | 54.6% SWE-bench Verified (477/500) | 39.6% Leaderboard, mini-SWE-agent | +15 pts | The lab evaluates 477 tasks, while the board reports a separate mini-SWE-agent run. |
| Qwen3-Max | GPQA Diamond | 87.4% GPQA | 72.6% Epoch AI run | +15 pts | |
| Inkling 2 Small | GDP.pdf | 25.2% GDP.pdf | 40% Leaderboard, xhigh | −15 pts | |
| GLM-4.5V | ChartMuseum | 55.3% ChartMuseum | 40.6% Leaderboard | +15 pts | |
| glm-4.7-flash | GPQA Diamond | 75.2% GPQA | 60.5% Epoch AI run | +15 pts | |
| DeepSeek-R1-Distill-Qwen-14B | GPQA Diamond | 59.1% GPQA Diamond pass@1, DeepSeek-R1-Distill-Qwen-14B (Table 15) | 44.7% Epoch AI run | +14 pts | |
| GPT-5.4 Pro | Humanity's Last Exam | 58.7% Best of Humanity's Last Exam no tools 42.7 / with tools 58.7 | 44.3% Leaderboard | +14 pts | |
| Fara-7B | WebTailBench | 38.4% WebTailBench | 24.1% Leaderboard, v1.5 | +14 pts | |
| GLM-5V-Turbo | PinchBench | 80.7% PinchBench Best / Avg 87.0 / 80.7 | 67% Leaderboard, OpenClaw | +14 pts | |
| Gemini 2.5 Pro Jun 2025 | SWE-bench Verified | 67.2% SWE-bench verified, multiple attempts (single attempt = 59.6%) | 53.6% Leaderboard, mini-SWE-agent | +14 pts | |
| Claude 3.5 Sonnet | GPQA Diamond | 67.2% GPQA (Diamond) (Maj@32 5-shot CoT) | 54% Epoch AI run, Jun 2024 | +13 pts | |
| GPT-5.6 Luna | GeneBench Pro | 10.8% GeneBench Pro | 23.6% Leaderboard, pro | −13 pts | |
| GLM-5.3 | CyberGym | 84.5% CyberGym | 97.2% Leaderboard, dynamic, Sangfor AI | −13 pts | |
| Claude Fable 5.1 | Terminal-Bench-Science | 52.6% Agentic scientific research Terminal-Bench-Science 0.1 | 40% Leaderboard, max, Claude Code | +13 pts | |
| Gemma 2B | MBPP | 29.2% MBPP, PT, 3-shot (Table 6) | 41.8% Leaderboard, EvalPlus subset, original tests | −13 pts | |
| Qwen3.5-0.8B | MMLU-Pro | 42.3% MMLU-Pro (Thinking) | 29.7% Leaderboard | +13 pts | |
| DeepSeek-V3 | LiveCodeBench | 49.2% LiveCodeBench | 61.7% Leaderboard, 2023-05-01 to 2024-10-01 (exclusive) | −13 pts | |
| Claude Fable 5.1 | Harvey LAB (Legal Agent Benchmark) | 19.1% Legal Agent Benchmark (Harvey LAB), all-pass rate on 1,235 public problems, max effort, internal harness, mean criterion pass rate 90.81%; held-out set run by Artificial Analysis 16.7% all-pass at xhigh (8.15.2) | 6.67% Leaderboard | +12 pts | |
| Claude 3 Opus | GPQA Diamond | 59.5% GPQA (Diamond) (Maj@32 5-shot CoT) | 47.2% Epoch AI run | +12 pts | |
| GPT-5.5 | OpenAI MRCR v2 | 87.5% OpenAI MRCR v2 8-needle 128K-256K 87.5% (512K-1M 74.0%) | 75.3% Leaderboard, 8-needle, 128K to 256K bin, high reasoning | +12 pts | |
| GPT-5 mini | SWE-bench Verified | 72% SWE-bench Verified (n=477), pass@1, gpt-5-thinking-mini no browsing launch candidate (Figure 19) | 59.8% Leaderboard, medium, mini-SWE-agent | +12 pts | |
| DeepSeek-V3 | MBPP | 75.4% MBPP (Pass@1) | 87.6% Leaderboard, EvalPlus subset, original tests | −12 pts | |
| Magistral Small 1.0 | GPQA Diamond | 68.2% GPQA, SFT + RL (Magistral Small) column (Table 3) | 56.1% Epoch AI run | +12 pts | |
| Kimi K3.1 Pro | GDP.pdf | 34.6% GDP.pdf | 46.6% Leaderboard, max | −12 pts | |
| MiniMax-M2.7 | Terminal-Bench 2.0 | 57% Terminal Bench 2 (text) | 45.1% Leaderboard, IndusAGI Coding Agent | +12 pts | |
| Qwen 3.8 Max | AndroidBench | 75.1% AndroidBench | 87% Leaderboard | −12 pts | |
| DeepSeek-V3 | GPQA Diamond | 68.4% GPQA | 56.5% Epoch AI run | +12 pts | |
| Gemini 3.1 Pro | Terminal-Bench 2.0 | 68.5% Terminal-Bench 2.0 (Terminus-2 harness) | 80.2% Leaderboard, TongAgents | −12 pts | |
| GPT-5 | HMMT 2025 | 100% HMMT Harvard-MIT mathematics tournament, GPT-5 pro (python) | 88.3% Leaderboard, high | +12 pts | |
| Devstral Small 2 | SWE-bench Verified | 68% SWE-bench Verified | 56.4% Leaderboard, mini-SWE-agent | +12 pts | |
| Qwen2.5-7B | MMLU-Pro | 56.3% MMLU-Pro, Qwen2.5-7B-Instruct (Table 8) | 45% Leaderboard | +11 pts | |
| DeepSeek V4.1 Flash | CyberGym | 88.1% CyberGym (Pass@1) | 99.4% Leaderboard, dynamic, TuLongFeng | −11 pts | |
| MiniMax-M2.1 | Terminal-Bench 2.0 | 47.9% Terminal-bench 2.0 | 36.6% Leaderboard, Crux | +11 pts | |
| Amazon Nova Premier | IFEval | 91.5% IFEval | 80.3% Leaderboard, strict, share of instructions followed | +11 pts | |
| GPT-5.4 Nano | OpenAI MRCR v2 | 44.2% OpenAI MRCR v2 8-needle 64K-128K | 33% Leaderboard, 8-needle, 128K to 256K bin, xhigh reasoning | +11 pts | |
| Qwen3.5-2B | MMLU-Pro | 66.5% MMLU-Pro (Thinking) | 55.3% Leaderboard | +11 pts | |
| DeepSeek-V3.2 | SWE-bench Multilingual | 70.2% SWE Multilingual (Resolved) | 59% Leaderboard, mini-SWE-agent | +11 pts | |
| Claude Opus 4.6 | Terminal-Bench 2.0 | 65.4% Agentic terminal coding Terminal-Bench 2.0 | 76.4% Leaderboard, Meta-Harness | −11 pts | |
| DeepSeek-V4-Pro | SimpleQA Verified | 57.9% SimpleQA-Verified (Pass@1) | 47% Epoch AI run, max | +11 pts | |
| Beam 1.0 | World-Class Bio | 37.9% World-Class Biology accuracy | 48.8% Leaderboard, max | −11 pts | |
| Claude Opus 5 | BioMysteryBench | 90.1% Best of Biology BioMysteryBench (hard) / Biology BioMysteryBench (human solved) | 79.3% Leaderboard, Vals AI harness, v11 full set | +11 pts | |
| Claude Opus 4.7 | Terminal-Bench 2.0 | 69.4% Agentic terminal coding Terminal-Bench 2.0 | 80.2% Leaderboard, WOZCODE | −11 pts | |
| gpt-oss-20b | GPQA Diamond | 71.5% GPQA Diamond (without tools) | 60.8% Epoch AI run, medium | +11 pts | |
| o3 | SWE-bench Verified | 69.1% SWE-Bench Verified (n=477) | 58.4% Leaderboard, mini-SWE-agent | +11 pts | |
| GPT-5.6 Sol | AutomationBench | 18.1% AutomationBench (Sol, max) | 28.8% Leaderboard, max | −11 pts | |
| Gemma 3 4B | Global MMLU Lite | 54.5% Global MMLU-Lite, IT, zero-shot (Table 6). PT 5-shot GMMLU (Table 13): 57.0 | 65.1% Leaderboard | −11 pts | |
| Qwen3.5-2B | Global PIQA | 69.3% Global PIQA | 58.9% Leaderboard, exact_match,strict_match; instruct | +10 pts | |
| GPT-5.1 | SWE-bench Verified | 76.3% SWE-bench Verified (all 500 problems) | 66% Leaderboard, medium, mini-SWE-agent | +10 pts | |
| ChatGPT agent | SpreadsheetBench | 45.5% SpreadsheetBench, OSX LibreOffice, with .xlsx access 45.5 (without 35.3) | 35.3% Leaderboard | +10 pts | |
| DeepSeek-V4-Pro | MathArena (Apex, IMO, USAMO) | 38.3% Apex (Pass@1) | 28.1% Leaderboard, max | +10 pts | |
| Claude Opus 4.5 | OSWorld-Verified | 66.3% Computer use OSWorld | 76.3% Leaderboard, 100 steps, VLAA-GUI | −10.0 pts | |
| Gemini 2.5 Pro Jun 2025 | ECLeKTic | 46.8% ECLeKTic (Table 3) | 36.9% Leaderboard | +9.9 pts | |
| GPT-4.1 nano | IFEval | 74.5% IFEval | 84.3% Leaderboard, strict, share of instructions followed | −9.8 pts | |
| Muse Spark | Humanity's Last Exam | 50.4% Best of Humanity's Last Exam (No Tools) / Humanity's Last Exam (With Tools) | 40.6% Leaderboard | +9.8 pts | |
| Claude 3.7 Sonnet | IFEval | 93.2% Instruction-following IFEval (64K extended thinking) | 83.4% Leaderboard, strict, share of instructions followed | +9.8 pts | |
| Qwen3.5-9B | Global PIQA | 83.2% Global PIQA | 73.5% Leaderboard, exact_match,strict_match; instruct | +9.7 pts | |
| Qwen2.5-VL-72B | ScreenSpot-Pro | 43.6% ScreenSpot Pro | 53.3% Leaderboard | −9.7 pts | |
| Claude 3.5 Sonnet (October 2024) | GPQA Diamond | 65% GPQA (Diamond) (0-shot CoT) | 55.3% Epoch AI run | +9.7 pts | |
| gpt-oss-20b | AIME 2025 | 98.7% AIME 2025 (tools) | 89.2% Leaderboard, high | +9.5 pts | |
| DeepSeek-R1-Distill-Llama-70B | GPQA Diamond | 65.2% GPQA Diamond pass@1, DeepSeek-R1-Distill-Llama-70B (Table 15) | 55.7% Epoch AI run | +9.5 pts | |
| Qwen1.5-72B | AlpacaEval 2.0 | 27.2% AlpacaEval 2.0 (Win Rate) | 36.6% Leaderboard, verified | −9.4 pts | |
| GLM-5.2 | AIME 2026 | 99.2% AIME 2026 | 90% Leaderboard, max | +9.2 pts | |
| Gemini 3.8 Flash | GDP.pdf | 35% GDP.PDF (All pass rate) | 44.2% Leaderboard, high | −9.2 pts | |
| Grok-3 mini | AIME 2025 | 90.8% AIME'25 (cons@64; pass@1 = 82.0) [Grok 3 mini Think] | 81.7% Leaderboard, high | +9.1 pts | |
| Gemma 4 26B A4B | GPQA Diamond | 82.3% GPQA Diamond | 73.2% Epoch AI run, minimal | +9.1 pts | |
| Claude Fable 5.1 | AutomationBench | 31.4% Business workflows AutomationBench | 22.4% Leaderboard, max | +9.0 pts | |
| Qwen3.5 397B-A17B | BabyVision | 52.3% BabyVision (52.3/43.3) | 43.3% Leaderboard | +9.0 pts | |
| Gemini 3.1 Pro | MCP Atlas | 69.2% MCP Atlas | 78.2% Leaderboard, high | −9.0 pts | |
| MiniMax-M2.5 | Terminal-Bench 2.0 | 51.7% Terminal Bench 2 | 42.7% Leaderboard, cchuter | +9.0 pts | |
| Qwen3.5-27B | Global PIQA | 87.5% Global PIQA | 78.5% Leaderboard, exact_match,strict_match; instruct | +9.0 pts | |
| GPT-5.6 Terra | Terminal-Bench 2.1 | 87.4% Terminal-Bench 2.1 | 78.4% Leaderboard, max, Codex | +9.0 pts | |
| GPT-5.6 Luna | Terminal-Bench 2.1 | 84.7% Terminal-Bench 2.1 | 75.7% Leaderboard, max, Codex | +9.0 pts | |
| Seed1.5-VL | MotionBench | 68.4% MotionBench | 59.4% Leaderboard, frames: 2fps | +9.0 pts | |
| Claude Sonnet 4.6 | OSWorld-Verified | 72.5% Agentic computer use OSWorld-Verified | 81.5% Leaderboard, 100 steps, Pointer Agent | −9.0 pts | |
| Qwen2.5-VL-72B | MMBench-Video | 2.02 MMBench-Video | 1.84 Leaderboard, 64 frames | +0.18 | The lab allowed up to 768 video frames, while the board evaluated the model with 64 frames. |
| Grok 3 | GPQA Diamond | 84.6% GPQA (Graduate-Level Google-Proof Q&A (Diamond)) (cons@64; pass@1 = 80.2) | 75.8% Epoch AI run | +8.8 pts | |
| Claude Sonnet 5.5 | Harvey LAB (Legal Agent Benchmark) | 11.7% Legal Agent Benchmark held-out set, all-pass rate at high effort, mean criterion pass 92.1% (max effort 10% and 93.1%) (8.14.2) | 2.92% Leaderboard | +8.8 pts | |
| Claude Sonnet 5.5 | Terminal-Bench 4.0 | 70.6% Agentic coding Terminal-Bench 4.0 | 61.8% Leaderboard, max, Claude Code | +8.8 pts | |
| Claude Opus 5.5 | ArXivMath | 91.2% ArXivMath August 2026 release (57 problems), max effort without tools (96.9% with tools), four attempts per problem (8.9, Figures 8.9.A and B) | 82.6% Leaderboard, high | +8.6 pts | |
| Gemma 4 31B IT | GPQA Diamond | 84.3% GPQA Diamond | 75.8% Epoch AI run, minimal | +8.5 pts | |
| DeepSeek V4.1 Flash | ExploitGym | 15.3% ExploitGym (Pass@1) | 23.7% Leaderboard, VARAS-OneMind \(智安·宇盾\) | −8.4 pts | |
| MiniMax-M2 | SWE-bench Verified | 69.4% SWE-bench Verified | 61% Leaderboard, mini-SWE-agent | +8.4 pts | |
| GPT-5.6 Terra | AutomationBench | 15.2% AutomationBench | 23.6% Leaderboard, max | −8.4 pts | |
| Gemini 3 Pro | Humanity's Last Exam | 45.8% Humanity's Last Exam, With search and code execution; No tools = 37.5% | 37.5% Leaderboard | +8.3 pts | |
| Gemma 3 27B | ECLeKTic | 16.7% ECLeKTic score, IT, 0-shot (Table 18). PT 2-shot (Table 13): 24.4 | 8.45% Leaderboard | +8.2 pts | |
| Grok 4.5 | DeepSWE | 62% Best of DeepSWE 1.0 (pass@1; eval by Datacurve, run with provider harnesses by AA) / DeepSWE 1.1 (mini-swe-agent harness run by Datacurve) | 53.8% Leaderboard, high, mini-swe-agent | +8.2 pts | |
| Gemma 7B | MBPP | 44.4% MBPP (3-shot) | 52.6% Leaderboard, EvalPlus subset, original tests | −8.2 pts | |
| Claude Sonnet 4.6 | MCP Atlas | 61.3% Scaled tool use MCP-Atlas | 69.5% Leaderboard | −8.2 pts | |
| Llama 3-8B | GPQA Diamond | 34.2% GPQA (0-shot), subset not stated, instruction tuned (Instruction tuned models table) | 26.1% Epoch AI run | +8.1 pts | |
| Kimi K3 | AutomationBench | 30.8% AutomationBench | 22.7% Leaderboard | +8.1 pts | |
| Gemini 3.1 Pro | SWE-Bench Pro | 54.2% SWE-Bench Pro (Public) (Single attempt) | 46.1% Leaderboard, thinking, mini-SWE-agent | +8.1 pts | |
| Claude Fable 5.2 | BenchCAD 2.1 | 75.4% BenchCAD 2.1 Core, 100 problems, no tools, adaptive thinking max effort, official scorer, five runs, up to 60 rounds and 500k output tokens. With tools 83.5%, without round or token limits. Not comparable with BenchCAD 1.0 (Section 8.13.2) | 83.5% Leaderboard, max, Claude Code | −8.1 pts | |
| Claude Opus 4.8 | ProgramBench tests passed | 79% ProgramBench hidden test pass rate on 166 of 200 tasks, one episode of up to 1M tokens, near-final snapshot. Text gives 79 to 88% across 1 to 5 episodes (8.5, Figure 8.5.A) | 70.9% Leaderboard, xhigh, mini-SWE-agent | +8.1 pts | |
| GPT-5.6 Sol | OpenAI MRCR v2 | 91.5% OpenAI MRCR v2 8-needle 256K-512K 91.5% (512K-1M 73.8%) | 83.5% Leaderboard, 8-needle, 128K to 256K bin, max reasoning | +8.0 pts | |
| Qwen3-Next-80B-A3B | IFEval | 88.9% IFEval | 81% Leaderboard, strict, share of instructions followed | +7.9 pts | |
| MiMo-V2.6 Pro | Terminal-Bench 4.0 | 34.9% Terminal Bench 4.0 | 27% Leaderboard, none, mini-swe-agent | +7.9 pts | |
| gpt-oss-120b | AIME 2025 | 97.9% AIME 2025 (tools) | 90% Leaderboard, high | +7.9 pts | |
| Kimi K2 Thinking | SWE-bench Verified | 71.3% SWE-bench Verified, w/ tools | 63.4% Leaderboard, mini-SWE-agent | +7.9 pts | |
| GPT-5.6 Sol | Human Pathogen Capabilities Test | 68.4% SecureBio Human Pathogen Capabilities Test, strongest reported configuration (9.1.1.8) | 76.3% Leaderboard, max | −7.9 pts | |
| Grok-3 mini | GPQA Diamond | 84% GPQA (cons@64; pass@1 = 80.3) [Grok 3 mini Think] | 76.3% Epoch AI run, low | +7.7 pts | |
 OLMo 2 32B Instruct | IFEval | 85.6% IFEval | 78% Leaderboard, strict, share of instructions followed | +7.6 pts | |
| GLM-4.7 | Terminal-Bench 2.0 | 41% Terminal Bench 2.0 | 33.4% Leaderboard, Terminus 2 | +7.6 pts | |
| Kimi K2.5 | Terminal-Bench 2.0 | 50.8% Terminal Bench 2.0 | 43.2% Leaderboard, Terminus 2 | +7.6 pts | |
| Gemma 3 4B | GPQA Diamond | 30.8% GPQA Diamond, IT, zero-shot (Table 6) | 23.2% Epoch AI run | +7.6 pts | |
| Claude Opus 4.5 | MCP Atlas | 62.3% Scaled tool use MCP Atlas | 69.8% Leaderboard, high | −7.5 pts | |
| Llama 3.1-405B | IFEval | 88.6% IFEval | 81.1% Leaderboard, strict, share of instructions followed | +7.5 pts | |
| Gemini 3.1 Flash-Lite | Humanity's Last Exam | 16% Humanity's Last Exam (full set, text + MM), No tools | 8.64% Leaderboard | +7.4 pts | |
| GPT-5 mini | GPQA Diamond | 82.3% GPQA diamond (no tools) | 75% Epoch AI run, high | +7.3 pts | |
| Claude Sonnet 4.5 | SWE-bench Verified | 82% Agentic coding SWE-bench Verified (with parallel test-time compute) | 74.8% Leaderboard, Sonar Foundation Agent | +7.2 pts | |
| GPT-5.2 | SWE-bench Verified | 80% SWE-bench Verified Software engineering | 72.8% Leaderboard, high, mini-SWE-agent | +7.2 pts | |
| Grok 4.7 | Harvey LAB (Legal Agent Benchmark) | 19.6% Harvey Legal Agent Benchmark (Legal work) | 12.5% Leaderboard | +7.1 pts | |
| Claude Opus 4 | GPQA Diamond | 83.3% Graduate-level reasoning GPQA Diamond (parallel test-time compute) | 76.3% Epoch AI run, 16K | +7.0 pts | |
| GPT-5 | World-Class Bio | 47.6% SecureBio World Class Biology, mean of n=10 (Table 15) | 54.6% Leaderboard, high | −7.0 pts | |
| GLM-5.2 | FrontierSWE v1 | 74.4% FrontierSWE (Dominance) | 67.5% Leaderboard, mean, Claude Code | +6.9 pts | |
| Qwen3-235B-A22B | WritingBench | 80.3 WritingBench | 74.7 Leaderboard, thinking | +5.57 | Qwen reports an earlier WritingBench evaluation, while the current board uses Claude Sonnet 4.5 to judge responses. |
| Qwen3.5-0.8B | Global PIQA | 59.4% Global PIQA | 52.5% Leaderboard, exact_match,strict_match; instruct | +6.9 pts | |
| Seed1.6-Thinking | MATH-Vision (MathVision) | 70.3% MathVision | 77.2% Leaderboard | −6.9 pts | |
| Kimi K3.1 Pro | FrontierFinance | 58.6% Frontier Finance | 51.7% Leaderboard, max, Finance Agent v2 | +6.9 pts | |
| o3-mini | SWE-bench Verified | 49.3% Software Engineering (SWE-bench Verified (n=477)) | 42.4% Leaderboard, Agentless Lite | +6.9 pts | |
| DeepSeek-V3.2 | Terminal-Bench 2.0 | 46.4% Terminal Bench 2.0 (Acc) | 39.5% Leaderboard, Terminus 2 | +6.9 pts | |
| Claude Opus 4.7 | SimpleQA Verified | 44.9% Simple-QA-Verified net score (correct minus incorrect), closed book, printed on chart. Correct 44.9, unsure 38.7, incorrect 16.3 (6.3.3.1, Figures 6.3.3.1.A and B) | 51.7% Epoch AI run, xhigh | −6.8 pts | |
| GLM-5.1 | HMMT 2026 | 82.6% HMMT Feb. 2026 | 89.4% Leaderboard | −6.8 pts | |
| Qwen3-235B-A22B-Thinking Jul 2025 | WritingBench | 88.3 WritingBench | 82.3 Leaderboard | +5.96 | The lab published its score before WritingBench switched judges, while the current board uses Claude Sonnet 4.5. |
| Claude 3.5 Haiku | IFEval | 85.9% IFEval (Table 8) | 79.2% Leaderboard, strict, share of instructions followed | +6.7 pts | |
| Claude Haiku 4.5 | SWE-bench Verified | 73.3% Agentic coding SWE-bench Verified | 66.6% Leaderboard, high, mini-SWE-agent | +6.7 pts | |
| Claude Opus 4.5 | Prompt injection robustness against adaptive attackers, browser use (Anthropic) | 8.00% Claude for Chrome internal adaptive evaluation, attack success rate, model only without safeguards, 100 attempts per environment, lower is better (Figure 5.2.2.3.A; 7.6% with old safeguards, 1.4% with improved safeguards) | 1.40% Leaderboard, improved safeguards, Claude for Chrome | −6.6 pts | |
| GPT-5 | MultiChallenge | 69.6% Scale MultiChallenge** Multi-turn instruction following | 63.2% Leaderboard, thinking | +6.4 pts | |
| DeepSeek-V3.2-Exp | HMMT 2025 | 83.6% HMMT 2025 | 90% Leaderboard, thinking | −6.4 pts | |
| Mixtral 8x7B | LMArena (Elo) | 1,121 LMSys Arena Elo, Mixtral 8x7B Instruct v0.1, screenshot Dec 22, 2023 (Figure 6 caption) | 1,197 Leaderboard | −76 | Mistral quotes Arena's December 2023 rating, while the board reports a later rating from its updated vote pool and scoring method. |
| Gemma 2 9B | LMArena (Elo) | 1,187 LMSYS Chatbot Arena Elo, IT (Table 14) | 1,267 Leaderboard | −80 | Google quotes Arena's 2024 rating, while the board reflects later votes and rating adjustments. |
| Grok 4 | AIME 2025 | 98.8% AIME'25, with Python (no tools 91.7) | 92.5% Leaderboard | +6.3 pts | |
| GPT-4.1 mini | IFEval | 84.1% IFEval | 90.4% Leaderboard, strict, share of instructions followed | −6.3 pts | |
| Claude Opus 4 | SWE-bench Verified | 79.4% Agentic coding SWE-bench Verified (parallel test-time compute) | 73.2% Leaderboard, Tools | +6.2 pts | |
| MiniMax-M3.1-Flash | GDP.pdf | 20.8% GDP.pdf AA | 27% Leaderboard, max | −6.2 pts | |
| Cohere Command A | Bird-SQL | 59.5% Bird Dev execution accuracy (Table 14, Table 1) | 65.7% Leaderboard | −6.2 pts | |
| Llama 3.1-8B | IFEval | 80.4% IFEval, instruction tuned (Instruction tuned models table) | 74.3% Leaderboard, strict, share of instructions followed | +6.1 pts | |
| o3-mini | MATH-500 | 97.9% Math (pass@1) | 91.8% Leaderboard, Vals AI harness | +6.1 pts | |
| phi-3-mini 3.8B | HumanEval | 58.5% HumanEval (0-Shot) (Section 3 table) | 64.6% Leaderboard | −6.1 pts | |
| GLM-4.5 | Humanity's Last Exam | 14.4% HLE | 8.32% Leaderboard | +6.1 pts | |
| Grok Voice 2.0 | τ-Voice | 56.5% Agentic Performance τ-voice Bench (per Artificial Analysis) | 62.5% Leaderboard, high | −6.0 pts | |
| Claude Opus 5 | OfficeQA Pro | 66.9% OfficeQA Pro, 133 questions, extracted text with code tools, public API with production safeguards (8.13.1) | 60.9% Leaderboard, Claude Agent SDK | +6.0 pts | |
| o1 | MATH-500 | 96.4% MATH (pass @1) | 90.4% Leaderboard, Vals AI harness | +6.0 pts | |
| Kimi K2.5 | SWE-bench Verified | 76.8% SWE-Bench Verified | 70.8% Leaderboard, high, mini-SWE-agent | +6.0 pts | |
| Gemini 2.5 Flash Jun 2025 | ECLeKTic | 36.8% ECLeKTic (Table 3) | 30.9% Leaderboard | +5.9 pts | |
| Grok 4.5 | FrontierSWE v1 | 78% FrontierSWE, Dominance (win rate versus a random baseline), high, Grok CLI, public leaderboard (2.7) | 72.1% Leaderboard, mean, Grok CLI | +5.9 pts | |
| granite-4.0-1b | GPQA Diamond | 29.9% GPQA (0-shot, CoT; subset not stated) | 24% Epoch AI run | +5.9 pts | |
| DeepSeek-V4-Flash | MathArena (Apex, IMO, USAMO) | 33% Apex (Pass@1), V4-Flash Max | 27.1% Leaderboard, max | +5.9 pts | |
| Phi-3.5-vision-instruct | MMBench | 81.9% MMBench (dev-en) (Table 5) | 76% Leaderboard | +5.9 pts | |
| Llama 3.1-8B | GPQA Diamond | 32.8% GPQA (0-shot, CoT), subset not stated, post-trained (Table 2) | 27% Epoch AI run | +5.8 pts | |
| Claude Opus 4.6 | SWE-bench Multilingual | 77.8% SWE-bench Multilingual, adaptive thinking, max effort, average of 25 trials (2.4) | 72% Leaderboard, mini-SWE-agent | +5.8 pts | |
| Kimi K2.6 | MATH-Vision (MathVision) | 87.4% MathVision | 93.2% Leaderboard, with python | −5.8 pts | |
| MiniMax-M2.5 | SWE-bench Multilingual | 74.1% SWE-Bench Multilingual | 68.3% Leaderboard, mini-SWE-agent | +5.8 pts | |
| Claude Sonnet 5 | Terminal-Bench 2.1 | 80.4% Agentic coding Terminal-Bench 2.1 | 74.6% Leaderboard, high, Claude Code | +5.8 pts | |
| Claude Opus 4.5 | SWE-Bench Pro | 51.6% SWE-bench Pro, 64k thinking, avg of 5 trials (Table 2.4.A; 52.0% with no thinking) | 45.9% Leaderboard, SWE-agent | +5.7 pts | |
| Kimi K2 Jul 2025 | AceBench | 76.5% AceBench, Acc | 82.2% Leaderboard | −5.7 pts | |
| Qwen2.5-VL-72B | MMMU | 70.2% MMMUval | 64.5% Leaderboard | +5.7 pts | |
| Kimi K2.5 | SWE-bench Multilingual | 73% SWE-Bench Multilingual | 67.3% Leaderboard, mini-SWE-agent | +5.7 pts | |
| Claude Sonnet 4.6 | Terminal-Bench 2.0 | 59.1% Agentic terminal coding Terminal-Bench 2.0 | 53.4% Leaderboard, Simplai Agent | +5.7 pts | |
| Gemma 3 27B | FACTS Grounding | 74.9% FACTS Grounding (IT) | 80.6% Leaderboard | −5.7 pts | |
| Claude Fable 5 | Harvey LAB (Legal Agent Benchmark) | 16.9% Best of Legal Legal Agent Benchmark (Harvey's Held-Out Set) / Legal Agent Full Public Benchmark Set | 11.3% Leaderboard | +5.6 pts | |
| Claude Opus 4.7 | OSWorld-Verified | 78% Agentic computer use OSWorld-Verified | 83.6% Leaderboard, 100 steps, Pointer Agent | −5.6 pts | |
| Claude Opus 4.5 | Humanity's Last Exam | 30.8% Humanity's Last Exam, reasoning only without tools (Figure 2.16.A; 43.2% with search, tools-only configuration) | 25.2% Leaderboard, thinking | +5.6 pts | |
| Gemma 2 27B | LMArena (Elo) | 1,218 LMSYS Chatbot Arena Elo, IT (Table 14) | 1,290 Leaderboard | −72 | The lab quotes a July 2024 Arena rating, while the board uses a November 2026 rating with style controls. |
| GPT-5 | Human Pathogen Capabilities Test | 53.7% SecureBio Human Pathogen Capabilities Test, mean of n=10 (Table 15) | 59.2% Leaderboard, high | −5.5 pts | |
| Claude Opus 4.5 | SWE-bench Multilingual | 76.2% SWE-bench Multilingual, no thinking and 64k thinking both 76.20% (Table 2.4.A) | 70.7% Leaderboard, mini-SWE-agent | +5.5 pts | |
| Llama 3.1-70B | IFEval | 87.5% IFEval, instruction tuned (Instruction tuned models table) | 82.1% Leaderboard, strict, share of instructions followed | +5.4 pts | |
| Llama 4 Scout | GPQA Diamond | 57.2% GPQA Diamond | 51.8% Epoch AI run | +5.4 pts | |
| Gemma 3 27B | GPQA Diamond | 42.4% GPQA Diamond 0-shot (IT); PT GPQA 5-shot = 24.3 | 47.7% Epoch AI run | −5.3 pts | |
| Tencent Hy4 | Terminal-Bench 4.0 | 44.4% Terminal Bench 4.0 | 39.1% Leaderboard, max, Claude Code | +5.3 pts | |
| Gemma 3 4B | FACTS Grounding | 70.1% FACTS Grounding, IT, zero-shot (Table 6) | 64.8% Leaderboard | +5.3 pts | |
| Qwen3-8B | GPQA Diamond | 62% GPQA-Diamond, thinking mode (Table 17). Non-thinking 39.3 (Table 18) | 56.8% Epoch AI run | +5.2 pts | |
| GPT-5.6 Terra | GeneBench Pro | 23.3% GeneBench Pro | 28.5% Leaderboard, pro | −5.2 pts | |
| Claude Opus 4.6 | SWE-bench Verified | 80.8% Agentic coding SWE-bench Verified | 75.6% Leaderboard, mini-SWE-agent | +5.2 pts | |
| Mistral Small 3.1 | GPQA Main | 44.4% GPQA Main (5-shot CoT) | 39.2% Leaderboard | +5.2 pts | |
| GPT-5 mini | FrontierMath | 22.1% FrontierMath (with python tool only) | 27.2% Leaderboard, high; task version 1.1.0, Epoch | −5.1 pts | |
| GLM-4.5-Air | IFEval | 86.3% IFEval (Prompt Strict) (Table 6) | 81.2% Leaderboard, strict, share of instructions followed | +5.1 pts | |
| MiniMax-M2.5 | MMLU-Pro | 85.2% MMLU-Pro, AA Index v4.0 protocol (Table 4) | 80.1% Leaderboard | +5.1 pts | |
| Claude Opus 4.5 | SimpleQA Verified | 44.1% Simple-QA-Verified correct rate, extended thinking (Figure 4.1.B; incorrect 35.4%, uncertain 20.5%) | 39% Leaderboard | +5.1 pts | |
| Claude Fable 5.1 | ProgramBench tests passed | 87.6% ProgramBench hidden test pass rate on 166 tasks, single agent, mini-swe-agent harness, no time limit (8.11.1) | 82.5% Leaderboard, xhigh, mini-SWE-agent | +5.1 pts | |
| Gemini 3.1 Flash-Lite | GPQA Diamond | 86.9% GPQA Diamond (No tools) | 81.8% Epoch AI run, high | +5.1 pts | |
| Claude 3.7 Sonnet | GPQA Diamond | 84.8% Graduate-level reasoning GPQA Diamond (64K extended thinking, parallel test-time compute) | 79.7% Epoch AI run, 64k thinking | +5.1 pts | |
| Kimi K3.1 Pro | BioMysteryBench | 80.6% BioMysteryBench (v11) | 75.6% Leaderboard, Vals AI harness, v11 full set | +5.0 pts | |
| Muse Wonder | Terminal-Bench 4.0 | 52% Terminal-Bench 4.0-AA | 47% Leaderboard, xhigh, Muse Code | +5.0 pts | |
| GPT-5 | AIME 2025 | 100% AIME 2025 Competition math, GPT-5 pro (python) | 95% Leaderboard, high | +5.0 pts | |
| Gemini 3 Pro | AIME 2025 | 100% AIME 2025, With code execution; No tools = 95.0% | 95% Leaderboard | +5.0 pts | |
| GLM-5 | SWE-bench Verified | 77.8% SWE-bench Verified | 72.8% Leaderboard, high, mini-SWE-agent | +5.0 pts | |
| Gemini 3.1 Pro | SWE-bench Verified | 80.6% SWE-Bench Verified (Single attempt) | 75.6% Epoch AI run | +5.0 pts | |
| Gemini 3.1 Pro | Humanity's Last Exam | 51.4% Humanity's Last Exam (full set, text + MM), Search (blocklist) + Code; No tools = 44.4% | 46.4% Leaderboard, thinking high | +5.0 pts | |
| Mixtral 8x7B | HumanEval | 40.2% HumanE [detailed table] | 45.1% Leaderboard | −4.9 pts | |
| Phi-2 | MBPP | 59.1% MBPP, Table 2 | 64% Leaderboard, EvalPlus subset, original tests | −4.9 pts | |
| Janus-Pro-7B | MM-Vet | 50% MM-Vet | 45.1% Leaderboard | +4.9 pts | |
| Qwen2.5-VL-72B | MMMU-Pro | 51.1% MMMU_Pro | 46.2% Leaderboard | +4.9 pts | |
| LFM2.5-VL-3B | OCRBench v2 | 47.5% OCRBench v2 (En) | 42.6% Leaderboard | +4.9 pts | |
 EXAONE 4.0 32B | RULER | 88.2% RULER (non-reasoning) | 93.1% Leaderboard | −4.9 pts | |
| Claude Opus 5 | DeepSWE | 68.8% Agentic coding DeepSWE v1.1 | 73.7% Leaderboard, max, mini-swe-agent | −4.9 pts | |
| GPT-6 Astra | BioTIER Refuse | 82.9% SecureBio BioTIER, safeguarded configuration refused requests designated for refusal (benign allowed 95.3%) (10.2.4.2) | 78.1% Leaderboard, max | +4.8 pts | |
| Claude 3.5 Sonnet | HumanEval | 92% HumanEval (0-shot) | 87.2% Leaderboard | +4.8 pts | |
| Kimi K3.1 Pro | Terminal-Bench 4.0 | 65.7% Terminal-Bench 4.0 (Claude Code) | 60.9% Leaderboard, max, Claude Code | +4.8 pts | |
| Gemini 2.5 Flash Sep 2025 | AIME 2025 | 75.6% AIME 2025 single attempt, model card | 70.8% Leaderboard, thinking | +4.8 pts | |
| Kimi K2 Jul 2025 | IFEval | 89.8% IFEval, Prompt Strict | 85% Leaderboard, strict, share of instructions followed | +4.8 pts | |
| GPT-4o May 2024 | GPQA Diamond | 53.6% GPQA (0-shot) | 48.9% Epoch AI run | +4.7 pts | |
| DeepSeek-R1 May 2025 | GPQA Diamond | 81% GPQA-Diamond (Pass@1) | 76.3% Epoch AI run | +4.7 pts | |
| Gemma 3 12B | FACTS Grounding | 75.8% FACTS Grounding, IT, zero-shot (Table 6) | 80.5% Leaderboard | −4.7 pts | |
| Claude 3.5 Sonnet (October 2024) | IFEval | 90.2% IFEval | 85.5% Leaderboard, strict, share of instructions followed | +4.7 pts | |
| Claude Opus 5.5 | Terminal-Bench-Science | 58.7% Agentic scientific research Terminal-Bench-Science 0.1 | 63.3% Leaderboard, max, Claude Code | −4.6 pts | |
| Claude Sonnet 4 | GPQA Diamond | 83.8% Graduate-level reasoning GPQA Diamond (parallel test-time compute) | 79.2% Epoch AI run, 59K | +4.6 pts | |
| Claude 3.7 Sonnet | MATH-500 | 96.2% Math problem-solving MATH 500 (64K extended thinking) | 91.6% Leaderboard, Vals AI harness | +4.6 pts | |
| Gemini 3 Flash | MCP Atlas | 57.4% MCP Atlas | 62% Leaderboard | −4.6 pts | |
| Beam 1.0 | ABC Bench Fragment Design | 82.1% ABC-Bench Fragment Design, 23 of 28 completed attempts passed, Pass@1 | 77.5% Leaderboard, max | +4.6 pts | |
| o3 | Humanity's Last Exam | 24.9% Humanity's Last Exam, o3 (python + browsing tools) | 20.3% Leaderboard, high | +4.6 pts | |
| Claude Opus 5.5 | Harvey LAB (Legal Agent Benchmark) | 8.30% Legal Agent Benchmark (Harvey LAB) held-out set of 120 problems, all-pass rate at max effort, run by Artificial Analysis (mean criterion pass rate 91.2%) (8.14.2) | 3.75% Leaderboard | +4.6 pts | |
| Llama 3.1-8B | MBPP | 72.8% MBPP ++ base version, 0-shot, pass@1, instruction tuned (Instruction tuned models table) | 68.3% Leaderboard, EvalPlus subset, original tests | +4.5 pts | |
| gemini-robotics-er-1.5-preview | Point-Bench | 71.6% Point-Bench (Table 19, thinking on). Thinking off 73.3 | 67.1% Leaderboard | +4.5 pts | |
| Muse Spark 1.2 | DeepSWE | 59.3% DeepSWE 1.1 (Muse Code harness) | 54.9% Leaderboard, xhigh, mini-swe-agent | +4.4 pts | |
| o4-mini | SWE-bench Verified | 69% SWE-bench Verified (n=477), pass@1, o4-mini no browsing launch candidate, printed chart label (Figure 19) | 64.6% Leaderboard, PatchPilot-v1.1 | +4.4 pts | |
| MiniMax-M2.5 | SWE-bench Verified | 80.2% SWE-Bench Verified | 75.8% Leaderboard, high, mini-SWE-agent | +4.4 pts | |
| Mistral 7B v0.1 | MBPP | 47.5% MBPP (hand-verified subset) | 51.9% Leaderboard, EvalPlus subset, original tests | −4.4 pts | |
| o1 | SimpleQA | 47% SimpleQA, accuracy (Table 3) | 42.6% Leaderboard | +4.4 pts | |
| Claude Sonnet 4.6 | SWE-bench Verified | 79.6% Agentic coding SWE-bench Verified | 75.2% Epoch AI run, no thinking | +4.4 pts | |
| gpt-oss-120b | GPQA Diamond | 80.1% GPQA Diamond (without tools) | 75.8% Epoch AI run, high | +4.3 pts | |
| GPT-5.1 | FrontierMath | 26.7% FrontierMath (with Python tool) | 31% Leaderboard, high; task version 1.1.0, Epoch | −4.3 pts | |
| GPT-5.4 Nano | GPQA Diamond | 82.8% GPQA Diamond | 78.5% Epoch AI run, high | +4.3 pts | |
| Llama 3-70B | HumanEval | 81.7% HumanEval (0-shot) [instruct] | 77.4% Leaderboard | +4.3 pts | |
| Llama 3.1-8B | HumanEval+ | 67.1% HumanEval+, pass@1, post-trained (Table 18) | 62.8% Leaderboard | +4.3 pts | |
| Cosmos3-Nano | PAI-Bench | 79.4% Cosmos3-Nano text-to-video PAIBench-G Overall, Table 12. Also Cosmos3-Nano image-to-video PAIBench-G Overall, Table 12 82.7 | 83.7% Leaderboard | −4.3 pts | |
| Claude Opus 4.8 | Terminal-Bench 2.1 | 74.6% Agentic terminal coding Terminal-Bench 2.1 | 78.9% Leaderboard, high, Claude Code | −4.3 pts | |
| GPT-5.5 | FrontierMath Tier 4 | 39.6% FrontierMath Tier 4 (GPT-5.5 Pro) | 35.4% Epoch AI run, xhigh | +4.2 pts | |
| Kimi K2 Jul 2025 | LongBench v2 | 49.1% LongBench v2 (Acc.), 128K window (Table 3) | 44.9% Leaderboard | +4.2 pts | |
| GLM-4.5 | MATH-500 | 98.2% MATH 500 | 94% Leaderboard, Vals AI harness | +4.2 pts | |
| GPT-5.2 | FrontierMath Tier 4 | 14.6% FrontierMath (Tier 4) Advanced mathematics | 18.8% Epoch AI run, xhigh | −4.2 pts | |
| Claude 3 Sonnet | MBPP | 79.4% MBPP, Pass@1 (Table 1) | 83.6% Leaderboard, EvalPlus subset, original tests | −4.2 pts | |
| Claude Fable 5 | Terminal-Bench 2.1 | 88% Agentic coding Terminal-Bench 2.1 | 83.8% Leaderboard, xhigh, Claude Code | +4.2 pts | |
| GLM-5.3 | Terminal-Bench 3.0 | 28.3% Terminal Bench 3.0 | 32.4% Leaderboard, max, Claude Code | −4.1 pts | |
| Claude Opus 4.7 | SWE-bench Verified | 87.6% Agentic coding SWE-bench Verified | 83.5% Epoch AI run, max | +4.1 pts | |
| Qwen3-30B-A3B | GPQA Diamond | 65.8% GPQA-Diamond, thinking mode (Table 15). Non-thinking 54.8 (Table 16) | 61.7% Epoch AI run | +4.1 pts | |
| phi-3-mini 3.8B | MBPP | 70% MBPP (3-Shot) (Section 3 table) | 65.9% Leaderboard, EvalPlus subset, original tests | +4.1 pts | |
| Grok-3 mini | MMLU-Pro | 78.9% MMLU-pro [Grok 3 mini, non-reasoning table] | 83% Leaderboard | −4.1 pts | |
| Gemma 3 12B | ECLeKTic | 10.3% ECLeKTic score, IT, 0-shot (Table 18). PT 2-shot (Table 13): 17.2 | 6.20% Leaderboard | +4.1 pts | |
| Claude Opus 4.7 | GPQA Diamond | 94.2% Graduate-level reasoning GPQA Diamond | 90.2% Epoch AI run, xhigh | +4.0 pts | |
| Llama 3.1-8B | MMLU-Pro | 48.3% MMLU-Pro (CoT), 5-shot, macro_avg/acc, instruction tuned (Instruction tuned models table) | 44.3% Leaderboard | +4.0 pts | |
| Inkling 2 Small | DesignArena 3D Design | 1,401 DesignArena 3D Design | 1,460 Leaderboard | −59 | |
| Gemini 2.0 Flash Feb 2025 | GPQA Diamond | 60.1% GPQA (diamond) | 64.1% Epoch AI run | −4.0 pts | |
| Gemini 2.5 Pro Jun 2025 | Global MMLU Lite | 89.2% Global MMLU (Lite) | 93.2% Leaderboard | −4.0 pts | |
| Gemini 2.5 Flash Apr 2025 | Aider Polyglot | 51.1% Aider Polyglot whole 51.1 / diff-fenced 44.2 | 47.1% Leaderboard, aider, diff edits | +4.0 pts | |
| Kimi-VL-A3B-Thinking-2506 | MMBench-EN v1.1 | 84.4% MMBench-EN-v1.1 (Acc) | 80.4% Leaderboard | +4.0 pts | |
| GLM-5 | AIME 2026 | 92.7% AIME 2026 I | 96.7% Leaderboard | −4.0 pts | |
| Grok 4.5 | Terminal-Bench 2.1 | 83.3% Terminal Bench 2.1 | 79.3% Leaderboard, high, Cursor CLI | +4.0 pts | |
| Kimi K2 Thinking | HMMT 2025 | 89.4% HMMT25, no tools | 93.3% Leaderboard | −3.9 pts | |
| Claude Sonnet 5 | Harvey LAB (Legal Agent Benchmark) | 8.90% Best of Legal Agent Benchmark Full Public Set / Legal Agent Benchmark Harvey's Held-Out Set | 5.00% Leaderboard | +3.9 pts | |
| Tencent Hy3 | WildClawBench | 53.6% WildClawBench (35, text-only) | 49.7% Leaderboard, OpenClaw | +3.9 pts | |
| Claude 3.7 Sonnet | SWE-bench Verified | 70.3% Agentic coding SWE-bench Verified (custom scaffold, reduced subset) | 66.4% Leaderboard, Aime-coder v1 | +3.9 pts | |
| GPT-5.6 Sol | World-Class Bio | 68.3% SecureBio World-Class Bio, strongest reported configuration (9.1.1.8) | 64.4% Leaderboard, max | +3.9 pts | |
| Claude Opus 4.5 | Terminal-Bench 2.0 | 59.3% Agentic terminal coding Terminal-bench 2.0 (128k thinking budget) | 63.1% Leaderboard, Droid | −3.9 pts | |
| GPT-5.6 Luna | OpenAI MRCR v2 | 41.3% OpenAI MRCR v2 8-needle 256K-512K 41.3 (512K-1M 41.3) | 45.1% Leaderboard, 8-needle, 128K to 256K bin, max reasoning | −3.8 pts | |
| Muse Spark 1.1 | Terminal-Bench 2.1 | 80% Terminal-Bench 2.1 (Agentic terminal coding) | 76.2% Leaderboard, xhigh, mini-SWE-agent | +3.8 pts | |
| GLM-5.1 | MCP Atlas | 71.8% MCP-Atlas (Public Set) | 75.6% Leaderboard | −3.8 pts | |
| GLM-5 | Terminal-Bench 2.0 | 56.2% Terminal-Bench 2.0 (Terminus 2) | 52.4% Leaderboard, Terminus 2 | +3.8 pts | |
| Nemotron 3.5 Super VL | MMLongBench-Doc | 62.8% MMLongBench-Doc | 66.6% Leaderboard, VL; 12B activated (120B total) | −3.8 pts | |
| GPT-4o May 2024 | MedQA | 89.4% MedQA USMLE 4 Options (0-shot), 89.4% in text (Table 7 shows 0.89, 5-shot 0.89) | 85.7% Leaderboard | +3.7 pts | |
| Kimi K3 | τ³-bench Banking | 33.4% τ3-Banking, cited from Artificial Analysis (Table 2) | 37.1% Leaderboard, max | −3.7 pts | |
| GLM-5.1 | GPQA Diamond | 86.2% GPQA-Diamond | 89.9% Epoch AI run | −3.7 pts | |
| Llama-3.1-Nemotron-Nano-VL-8B-V1 | OCRBench v2 | 60.1% OCRBenchV2 English 60.1 / Chinese 37.9 | 56.4% Leaderboard | +3.7 pts | |
| DeepSeek-V4-Flash | MathArena Apex Shortlist | 85.7% Apex Shortlist (Pass@1), V4-Flash Max | 89.4% Leaderboard, max | −3.7 pts | |
| Claude Opus 4.1 | GPQA Diamond | 80.9% Graduate-level reasoning GPQA Diamond | 77.3% Epoch AI run, 16K | +3.6 pts | |
| LongCat-Flash-Omni | UNO-Bench | 49.9% UNO-Bench | 46.3% Leaderboard | +3.6 pts | |
| Claude Opus 4.5 | Vals Finance Agent | 55.2% FinanceAgent (Vals AI), external Vals AI analysis, 64k thinking, 200k context, avg of 8 trials (2.13; internal testing 61.07% same settings, 61.03% with 1M context) | 58.8% Leaderboard, thinking | −3.6 pts | |
| DeepSeek-R1 | Aider Polyglot | 53.3% Aider-Polyglot (Acc.) | 56.9% Leaderboard, aider, diff edits | −3.6 pts | |
| Claude Fable 5.1 | Chartography | 42.6% Chartography, no tools, adaptive thinking max effort, 5 runs; 86.2% with tools (8.14.1) | 46.2% Leaderboard, adaptive/max | −3.6 pts | |
| Inkling | SimpleQA Verified | 43.9% SimpleQA Verified | 40.3% Epoch AI run, xhigh | +3.6 pts | |
| GPT-5 mini | AIME 2025 | 91.1% AIME '25 (no tools) | 87.5% Leaderboard, high | +3.6 pts | |
| GLM-5 | SWE-bench Multilingual | 73.3% SWE-bench Multilingual | 69.7% Leaderboard, mini-SWE-agent | +3.6 pts | |
| Gemini 3.8 Flash TTS | Voice Arena Japanese | 1,232 Voice Arena japanese, Elo, Gemini speech generation model page | 1,188 Leaderboard | +44 | |
| Falcon H1R 7B | AIME 2025 | 83.1% AIME-25 | 86.7% Leaderboard | −3.6 pts | |
| GPT-4.1 | IFEval | 87.4% IFEval | 83.8% Leaderboard, strict, share of instructions followed | +3.6 pts | |
| Llama 3.1-70B | MMLU-Pro | 66.4% MMLU-Pro (CoT), 5-shot, macro_avg/acc, instruction tuned (Instruction tuned models table) | 62.8% Leaderboard | +3.6 pts | |
| Qwen3-4B | GPQA Diamond | 55.9% GPQA-Diamond, thinking mode (Table 17). Non-thinking 41.7 (Table 18) | 52.3% Epoch AI run | +3.6 pts | |
| Gemini 2.5 Flash Sep 2025 | Global MMLU Lite | 87.9% Global MMLU (Lite), model card | 91.5% Leaderboard | −3.5 pts | |
| Kimi K2.6 | SWE-bench Verified | 80.2% SWE-Bench Verified | 76.7% Epoch AI run | +3.5 pts | |
| GPT-5.6 Luna | FrontierMath Tiers 1-3 v2 | 78.6% FrontierMath Tier 1-3 (v2) | 82.1% Leaderboard, max; task version 2.0.0, Epoch | −3.5 pts | |
| Claude Opus 5.5 | ProgramBench tests passed | 91.2% ProgramBench hidden test pass rate on 166 of 200 tasks, single agent, mini-swe-agent harness, no time limit (8.10.1) | 87.7% Leaderboard, xhigh, mini-SWE-agent | +3.5 pts | |
| GPT-6 Astra | Terminal-Bench-Science | 64.6% Terminal-Bench Science 0.1 | 68.1% Leaderboard, max, Codex | −3.5 pts | |
| Qwen2.5-72B | IFEval | 84.1% IFeval strict-prompt | 80.6% Leaderboard, strict, share of instructions followed | +3.5 pts | |
| Claude 3.5 Haiku | GPQA Diamond | 41.6% GPQA (Diamond), 0-shot CoT (Table 8) | 38.1% Epoch AI run, Oct 2024 | +3.5 pts | |
| Qwen2.5-32B | GPQA Diamond | 49.5% GPQA, variant not stated, Qwen2.5-32B-Instruct (Table 7) | 46.1% Epoch AI run | +3.4 pts | |
| Qwen3-235B-A22B | MATH-500 | 98% MATH-500 | 94.6% Leaderboard, Vals AI harness | +3.4 pts | |
| Claude Sonnet 4 | SWE-bench Verified | 80.2% Agentic coding SWE-bench Verified (parallel test-time compute) | 76.8% Leaderboard, EPAM AI/Run Developer Agent | +3.4 pts | |
| GPT-6 Astra | World-Class Bio | 59.2% SecureBio World Class Bio (WCB), refusal-corrected accuracy, web search disabled, corrected 2026-10-30 (10.1.1.4, change log) | 62.6% Leaderboard, max | −3.4 pts | |
| GPT-5.4 | MCP Atlas | 67.2% MCP Atlas | 70.6% Leaderboard, xhigh | −3.4 pts | |
| Qwen3-30B-A3B | Berkeley Function Calling Leaderboard (BFCL) | 69.1% BFCL v3, thinking mode (Table 15). Non-thinking 58.6 (Table 16) | 65.7% Leaderboard, native function calling | +3.4 pts | |
| GPT-5 mini | MultiChallenge | 62.3% Scale MultiChallenge (o3-mini grader) | 59% Leaderboard, thinking | +3.3 pts | |
| Beam 1.0 | BioTIER Refuse | 64.6% BioTIER refuse split accuracy | 61.3% Leaderboard, max | +3.3 pts | |
| EXAONE 4.0 32B | LiveCodeBench v6 | 66.7% LiveCodeBench v6 (reasoning) | 70% Leaderboard | −3.3 pts | |
| Phi-4-multimodal | MMBench | 86.7% MMBench (dev-en) | 83.4% Leaderboard | +3.3 pts | |
| Qwen3-Omni-30B-A3B | VoiceBench | 85.5% VoiceBench Overall | 88.8% Leaderboard, thinking | −3.3 pts | |
| EmbeddingGemma 2 | MIEB Lite | 65.7 MIEB lite, Mean(TaskType), full precision, 768d | 63.5 Leaderboard | +2.15 | |
| Inkling | DesignArena Website | 1,257 DesignArena, agentic web development, 1257 Elo | 1,216 Leaderboard | +41 | |
| GPT-5 | GPQA Diamond | 89.4% GPQA Diamond, GPT-5 pro (python) | 86.2% Epoch AI run, high | +3.2 pts | |
| o3-mini | FrontierMath | 9.20% FrontierMath Pass@1 | 12.4% Leaderboard, high; task version 1.1.0, Epoch | −3.2 pts | |
| Qwen2.5-72B | Arena-Hard-Auto | 81.2% Arena-Hard | 78% Leaderboard | +3.2 pts | |
| Kimi K2 Jul 2025 | MATH-500 | 97.4% MATH-500, Acc | 94.2% Leaderboard, Vals AI harness | +3.2 pts | |
| Gemini 4 Argon | SimpleQA Verified | 78.8% SimpleQA Verified F1 score 78.8; incorrect rate 6.3% (Figures 5.11, 5.12) | 75.6% Leaderboard | +3.2 pts | |
| Qwen3.7-Max | SWE-bench Verified | 80.4% SWE-Verified | 77.3% Epoch AI run | +3.1 pts | |
| Inkling 2 Small | ComplexConstraints | 44.5% ComplexConstraints v1.0 | 47.6% Leaderboard, xhigh | −3.1 pts | |
| Gemma 7B | HumanEval | 32.3% HumanEval (pass@1) | 35.4% Leaderboard | −3.1 pts | |
| o4-mini | Aider Polyglot | 68.9% Aider Polyglot whole 68.9 (diff 58.2), o4-mini-high | 72% Leaderboard, high, aider, diff edits | −3.1 pts | |
| GPT-6 Astra | Human Pathogen Capabilities Test | 65.9% SecureBio Human Pathogen Capabilities Test (HPCT), refusal-corrected accuracy (10.1.1.4) | 69% Leaderboard, max | −3.1 pts | |
| Llama 3.1-8B | HumanEval | 72.6% HumanEval, 0-shot, pass@1, instruction tuned (Instruction tuned models table) | 69.5% Leaderboard | +3.1 pts | |
| DeepSeek-V3.2 | SWE-bench Verified | 73.1% SWE Verified (Resolved) | 70% Leaderboard, high, mini-SWE-agent | +3.1 pts | |
| GPT-5.5 Instant | GPQA Diamond | 85.6% GPQA (PhD-Level Science) | 82.5% Epoch AI run | +3.1 pts | |
| MiMo-V2-Omni | PinchBench | 81.2% PinchBench (avg.) | 78.2% Leaderboard, OpenClaw | +3.0 pts | |
| GPT-6 Cyber | Atomic Challenges | 97% Atomic Challenges, vulnerability research and exploitation 97%, network attack simulation 98%, evasion 63% | 100% Leaderboard | −3.0 pts | |
| Claude 3 Haiku | GPQA Diamond | 33.3% GPQA (Diamond), 0-shot CoT, mean of 10 rollouts. 5-shot CoT 36.4, Maj@32 5-shot CoT 40.1 (Table 1, Table 8) | 36.3% Epoch AI run | −3.0 pts | |
| Gemma 2B | HumanEval | 22% HumanEval, PT, pass@1 (Table 6) | 25% Leaderboard | −3.0 pts | |
| Claude 3 Opus | MBPP | 86.4% MBPP (Pass@1) | 89.4% Leaderboard, EvalPlus subset, original tests | −3.0 pts | |
| Gemini 1.0 Ultra | MMMU | 62.4% MMMU (val), Maj1@32 (pass@1 = 59.4%) | 59.4% Leaderboard | +3.0 pts | |
| GPT-5.5 | OfficeQA Pro | 54.1% OfficeQA Pro | 57.1% Leaderboard, Codex SDK | −3.0 pts | |
| Claude Fable 5 | OfficeQA Pro | 57.9% OfficeQA Pro, Databricks' own evaluation with documents read as images (Table 8.1.A, 8.17.1) | 60.9% Leaderboard, Claude Agent SDK | −3.0 pts | |
| Llama 3.3 70B Instruct | MMLU-Pro | 68.9% MMLU Pro (CoT), 5-shot, macro_avg/acc | 65.9% Leaderboard | +3.0 pts | |
| DeepSeek-V4-Pro | SWE-bench Verified | 80.6% SWE Verified (Resolved) | 77.6% Epoch AI run, max | +3.0 pts | |
| Mistral Small 3.2 | GPQA Diamond | 46.1% GPQA Diamond (5-shot CoT) | 49% Epoch AI run | −2.9 pts | |
| o1 | MathVista | 71% MathVista (pass @1) | 73.9% Leaderboard | −2.9 pts | |
| Kimi K3.1 Pro | Kimi Hallu Bench | 8.30% Kimi Hallu Bench Hard w/ tools (Internal, lower is better) | 5.40% Leaderboard, without tools | −2.9 pts | |
| Grok 4.6 | EEBench | 60% EEBench V1 core corpus, reward, xhigh, Grok Build harness, run by Atopile (4.1). High = 53.0% | 57.1% Leaderboard, Grok CLI | +2.9 pts | |
| Qwen2.5-7B | IFEval | 71.2% IFEval, Qwen2.5-7B-Instruct (Table 8) | 74.1% Leaderboard, strict, share of instructions followed | −2.9 pts | |
| Claude 3.5 Haiku | MMLU-Pro | 65% MMLU Pro, 0-shot CoT (Table 8) | 62.1% Leaderboard | +2.9 pts | |
| Qwen3.5 397B-A17B | AIME 2026 | 91.3% AIME26 | 94.2% Leaderboard | −2.9 pts | |
| Qwen3-235B-A22B | Berkeley Function Calling Leaderboard (BFCL) | 70.8% BFCL v3 | 67.9% Leaderboard, native function calling | +2.9 pts | |
| Grok 4.7 | LatchBio Capabilities v1.0 | 44.5% LatchBio Capabilities v1.0, overall score (mean of 11 capability benchmarks), xhigh (5.2) | 47.4% Leaderboard, Pi | −2.9 pts | |
| Claude Sonnet 5 | AutomationBench | 13.5% AutomationBench | 10.7% Leaderboard, max | +2.8 pts | |
| Inkling 2 Small | FrontierCode 2.0 | 25.4% FrontierCode v2.0 | 22.6% Leaderboard, max, Devin CLI | +2.8 pts | |
| Llama 4 Maverick | GPQA Diamond | 69.8% GPQA Diamond | 67% Epoch AI run, FP8 | +2.8 pts | |
| GPT-5 | Molecular Biology Capabilities Test | 48% SecureBio Molecular Biology Capabilities Test, mean of n=10 (Table 15) | 50.8% Leaderboard, high | −2.8 pts | |
| MiniMax-M2.1 | Toolathlon | 43.5% Toolathlon | 40.7% Leaderboard | +2.8 pts | |
| GPT-5.6 Sol | GeneBench Pro | 28.7% GeneBench Pro (Sol, max) | 31.5% Leaderboard, pro | −2.8 pts | |
| GPT-5 mini | Humanity's Last Exam | 16.7% HLE (no tools) | 19.4% Leaderboard | −2.7 pts | |
| DeepSeek-R1 May 2025 | HMMT 2025 | 79.4% HMMT 2025 (Pass@1) | 76.7% Leaderboard | +2.7 pts | |
| GLM-5 | HMMT Nov 2025 | 96.9% HMMT Nov. 2025 | 94.2% Leaderboard | +2.7 pts | |
| Qwen3.5-9B | GPQA Diamond | 81.7% GPQA Diamond | 79% Epoch AI run | +2.7 pts | |
| MiMo-V2-Pro | PinchBench | 81% PinchBench (avg.) | 78.3% Leaderboard, OpenClaw | +2.7 pts | |
| GPT-4.5 | GPQA Diamond | 71.4% GPQA (science) | 68.7% Epoch AI run | +2.7 pts | |
| GPT-4 Turbo Apr 2024 | GPQA Diamond | 49.3% GPQA% | 46.6% Epoch AI run | +2.7 pts | |
| Cohere Command A | Aider Polyglot | 14.7% Aider Polyglot (Table 13) | 12% Leaderboard, aider, whole edits | +2.7 pts | |
| o3-mini | GPQA Diamond | 79.7% PhD-level Science Questions (GPQA Diamond) | 77% Epoch AI run, high | +2.7 pts | |
| Qwen3-32B | GPQA Diamond | 68.4% GPQA-Diamond, thinking mode (Table 13). Non-thinking 54.6 (Table 14) | 65.7% Epoch AI run | +2.7 pts | |
| Qwen3.7-Max | CoWorkBench | 67.2% CoWorkBench | 64.6% Leaderboard | +2.6 pts | |
| gpt-oss-120b | Aider Polyglot | 44.4% Aider Polyglot, high reasoning (Table 3) | 41.8% Leaderboard, high, aider, diff edits | +2.6 pts | |
| Kimi K2.5 | SimpleQA Verified | 36.9% SimpleQA Verified (Table 4) | 34.3% Epoch AI run | +2.6 pts | |
| Muse Spark | SWE-Bench Pro | 52.4% SWE-Bench Pro (Diverse Agentic Coding) | 55% Leaderboard, mini-SWE-agent | −2.6 pts | |
| Claude Opus 4.8 | GPQA Diamond | 93.6% GPQA Diamond | 91% Epoch AI run, max | +2.6 pts | |
 ERNIE 5.1 | LMArena Search Arena | 1,223 Arena Search leaderboard, 1,223, 4th globally on May 9 | 1,192 Leaderboard | +31 | Baidu quotes the May 9 Arena Search rating, while the comparison uses a later leaderboard snapshot. |
| Claude Sonnet 4.6 | GPQA Diamond | 89.9% Graduate-level reasoning GPQA Diamond | 87.4% Epoch AI run, 32k thinking | +2.5 pts | |
| GPT-5.2 Codex | Terminal-Bench 2.0 | 64% Terminal-Bench 2.0 | 66.5% Leaderboard, Deep Agents | −2.5 pts | |
| Qwen3-4B | Berkeley Function Calling Leaderboard (BFCL) | 65.9% BFCL v3, thinking mode (Table 17). Non-thinking 57.6 (Table 18) | 63.4% Leaderboard, native function calling | +2.5 pts | |
| Llama 3.1-70B | GPQA Diamond | 46.7% GPQA, 0-shot, em, subset not stated, instruction tuned (Instruction tuned models table) | 44.2% Epoch AI run | +2.5 pts | |
| GPT-4o mini | GPQA Diamond | 40.2% GPQA | 37.7% Epoch AI run | +2.5 pts | |
| GLM-4.5-Air | Humanity's Last Exam | 10.6% HLE, text-only, GPT-4o judge (Table 4) | 8.12% Leaderboard | +2.5 pts | |
| GPT-5.6 Luna | FrontierMath Tier 4 v2 | 58.5% FrontierMath Tier 4 (v2) | 61% Leaderboard, max; task version 2.0.0, Epoch | −2.5 pts | |
| Claude Opus 5.5 | AutomationBench | 40% Business workflows AutomationBench | 42.5% Leaderboard, max, default fallbacks | −2.5 pts | |
| Aya Vision 32B | Kaleidoscope | 41.7% Kaleidoscope, Aya Vision languages (Table 4) | 39.3% Leaderboard | +2.5 pts | |
| GPT-5.6 Terra | FrontierMath Tier 4 v2 | 68.3% FrontierMath Tier 4 (v2) | 70.7% Leaderboard, max; task version 2.0.0, Epoch | −2.4 pts | |
| DeepSeek-V4-Pro | MathArena Apex Shortlist | 90.2% Apex Shortlist (Pass@1) | 87.8% Leaderboard, max | +2.4 pts | |
| Mistral Medium 3 | GPQA Diamond | 57.1% GPQA Diamond 5-shot CoT | 59.5% Epoch AI run | −2.4 pts | |
| DeepSeek-V3.1 | AIME 2025 | 88.4% AIME 2025 (Pass@1) | 90.8% Leaderboard, thinking | −2.4 pts | |
| GLM-5.2 | DeepSWE | 46.2% DeepSWE | 43.8% Leaderboard, max, mini-swe-agent | +2.4 pts | |
| Qwen3.7-Plus | GPQA Diamond | 90.3% GPQA Diamond | 87.9% Epoch AI run | +2.4 pts | |
| Grok 4.5 | APEX-SWE | 51.2% APEX-SWE, Pass@1, high, run by Mercor (2.3) | 53.6% Leaderboard, high, terminus-2 | −2.4 pts | |
| Qwen3-14B | Berkeley Function Calling Leaderboard (BFCL) | 70.4% BFCL v3, thinking mode (Table 15). Non-thinking 61.5 (Table 16) | 68% Leaderboard, native function calling | +2.4 pts | |
| DeepSeek-V3.2-Exp | AIME 2025 | 89.3% AIME 2025 | 91.7% Leaderboard, thinking | −2.4 pts | |
| GLM-4.7 | GPQA Diamond | 85.7% GPQA-Diamond | 83.3% Epoch AI run | +2.4 pts | |
| Gemma 3 4B | ECLeKTic | 4.60% ECLeKTic score, IT, 0-shot (Table 18). PT 2-shot (Table 13): 11.0 | 2.25% Leaderboard | +2.4 pts | |
| GPT-5.1-Codex-Max | Terminal-Bench 2.0 | 58.1% Terminal-Bench 2.0, xhigh | 60.5% Leaderboard, Codex CLI | −2.4 pts | |
| Gemini 3.6 Flash | DeepSWE | 49% DeepSWE v1.1 | 46.7% Leaderboard, high, mini-swe-agent | +2.3 pts | |
| Claude Opus 5 | scBench (LatchBio SingleCellBench) | 60.6% LatchBio Bioinformatics, SingleCellBench, 195 problems (8.17.2) | 58.3% Leaderboard, published v1, Pi | +2.3 pts | |
| GPT-4.1 mini | Aider Polyglot | 34.7% Aider's polyglot: whole 34.7 (diff 31.6) | 32.4% Leaderboard, aider, diff edits | +2.3 pts | |
| Claude Opus 5 | Chartography | 29.6% Chartography, no tools, adaptive thinking at max effort, five runs (83.0% with tools) (8.12.1) | 27.3% Leaderboard, adaptive/max | +2.3 pts | |
| Claude 3 Sonnet | HumanEval | 73% HumanEval, 0-shot (Table 1) | 70.7% Leaderboard | +2.3 pts | |
| DeepSeek V4.1 Flash 1017 | Terminal-Bench 4.0 | 42.3% Terminal-Bench 4.0 | 40% Leaderboard, max, Claude Code | +2.3 pts | |
| GLM-4.6 | AIME 2025 | 93.9% AIME 25 | 91.7% Leaderboard | +2.2 pts | |
| Gemini 3 Flash | AIME 2025 | 99.7% AIME 2025, With code execution; No tools = 95.2% | 97.5% Leaderboard, high | +2.2 pts | |
| Qwen3-Omni-30B-A3B | Daily-Omni | 75.8% DailyOmni (Thinking variant) | 73.6% Leaderboard, Omni-Modal Language Models (With Visual and Audio) | +2.2 pts | |
| Gemini 3 Flash | SWE-bench Verified | 78% SWE-bench Verified (Single attempt) | 75.8% Leaderboard, high, mini-SWE-agent | +2.2 pts | |
| Nova 2 Omni Preview | tau2-bench Verified | 73.5% Mean of τ2-bench Retail-Verified 78.3 / Airline-Verified 68.8 | 75.7% Leaderboard, tau2-bench-verified; gpt-5.1 user simulator | −2.2 pts | |
| GPT-5.6 Luna | AutomationBench | 14.9% AutomationBench | 17.1% Leaderboard, max | −2.2 pts | |
| Claude Sonnet 4.6 | ARC-AGI-2 | 58.3% Novel problem-solving ARC-AGI-2 | 60.4% Leaderboard, high | −2.1 pts | |
| DeepSeek-OCR 2 | OmniDocBench v1.5 | 91.1 OmniDocBench v1.5 Overall 91.09, V-token max 1120, Text Edit 0.048, Formula CDM 90.31, Table TEDS 87.75, Table TEDS-S 92.06, R-order Edit 0.057 (Table 1) | 89.2 Leaderboard | +1.92 | |
| Muse Spark Open | HLE-Diamond | 26.1% HLE-Diamond (no tools) | 28.2% Leaderboard, max | −2.1 pts | |
| Qwen3-1.7B | GPQA Diamond | 40.1% GPQA-Diamond, thinking mode (Table 19). Non-thinking 28.6 (Table 20) | 38% Epoch AI run | +2.1 pts | |
| Claude Fable 5.1 | Terminal-Bench 4.0 | 55.8% Terminal-Bench 4.0, Claude Code --bare mode, max effort, 15 trials per task; Table 8.1.A rounds to 56% (Mythos 5.1 61%) (8.6) | 57.9% Leaderboard, max, Claude Code | −2.1 pts | |
| Kimi K2.5 | HMMT 2025 | 95.4% HMMT 2025 (Feb) | 93.3% Leaderboard, high | +2.1 pts | |
| GLM-5.3 | DeepSWE | 66.9% DeepSWE (v1.1) | 69% Leaderboard, max, mini-swe-agent | −2.1 pts | |
| Claude Opus 4.8 | SpatialBench (LatchBio) | 53.3% LatchBio Bioinformatics, SpatialBench, no extended thinking (8.16.3) | 55.4% Leaderboard, claude-code | −2.1 pts | |
| Gemini 2.5 Pro Jun 2025 | 1H-VideoQA | 81% 1H-VideoQA, test, 0-shot (Table 6) | 79% Leaderboard | +2.0 pts | |
| Hunyuan-A13B-Instruct | ArtifactsBench | 43% ArtifactsBench | 41% Leaderboard | +2.0 pts | |
| Qwen3.5 397B-A17B | GPQA Diamond | 88.4% GPQA | 86.4% Epoch AI run, none | +2.0 pts | |
| DeepSeek-R1-Distill-Qwen-32B | GPQA Diamond | 62.1% GPQA Diamond pass@1, DeepSeek-R1-Distill-Qwen-32B (Table 15) | 64.1% Epoch AI run | −2.0 pts | |
| Tencent Hy4 preview | BioMysteryBench | 71.3% BioMysteryBench | 69.3% Leaderboard, Vals AI harness, v11 full set | +2.0 pts | |
| Qwen 3.6 Plus | GPQA Diamond | 90.4% GPQA | 88.4% Epoch AI run, 2026-04-02 | +2.0 pts | |
| GPT-5.5 | Terminal-Bench 2.0 | 82.7% Terminal-Bench 2.0 | 84.7% Leaderboard, NexAU-AHE | −2.0 pts | |
| Gemma 3 27B | LMArena (Elo) | 1,338 Chatbot Arena Elo, IT, preliminary results received March 8, 2025 (Table 5) | 1,365 Leaderboard | −27 | Google reports a preliminary March 2025 Arena rating, while the board reports a later rating from updated votes. |
| Kimi K2 Thinking | AIME 2025 | 94.5% AIME25, no tools | 92.5% Leaderboard | +2.0 pts | |
| Grok 4.7 | EEBench | 66% EEBench V1 core corpus, reward, xhigh, Grok Build harness, run by Atopile (4.1) | 64% Leaderboard, Grok CLI | +2.0 pts | |
| Kimi K2.6 | HMMT 2026 | 92.7% HMMT 2026 (Feb) | 94.7% Leaderboard, high | −2.0 pts | |
| Claude 3 Opus | HumanEval | 84.9% HumanEval (0-shot) | 82.9% Leaderboard | +2.0 pts | |
| GPT-4 Turbo Apr 2024 | HumanEval | 88.2% HumanEval% | 90.2% Leaderboard | −2.0 pts | |
| Kimi K2 Sep 2025 | SWE-bench Verified | 69.2% SWE-Bench verified, ACC | 71.2% Leaderboard, Lingxi v1.5 | −2.0 pts | |
| Mistral Small 3 | GPQA Diamond | 45.3% gpqa_main_cot_5shot_instruct | 47.3% Epoch AI run | −2.0 pts | |
| Gemini 3.8 Flash TTS | Voice Arena Hindi | 1,106 Voice Arena hindi, Elo, Gemini speech generation model page | 1,084 Leaderboard | +22 | |
| Kimi K3 | Legal Research Bench | 44.2% Legal Research Bench | 46.1% Leaderboard | −1.9 pts | |
| Qwen3.6 27B | GPQA Diamond | 87.8% GPQA Diamond | 85.9% Epoch AI run | +1.9 pts | |
| Kimi K2.5 | HMMT Nov 2025 | 91.1% HMMT Nov 2025, average 24k output tokens (Table 5) | 89.2% Leaderboard, high | +1.9 pts | |
| Granite 3.3 8B Instruct | IFEval | 74.8% IFEval | 72.9% Leaderboard, strict, share of instructions followed | +1.9 pts | |
| o4-mini | MultiChallenge | 43% Scale MultiChallenge | 44.9% Leaderboard, high | −1.9 pts | |
| Kimi K3 | MCP Atlas | 84.2% MCP-Atlas | 82.3% Leaderboard, max | +1.9 pts | |
| Gemini 3 Flash | SimpleQA Verified | 68.7% SimpleQA Verified | 66.8% Epoch AI run, high | +1.9 pts | |
| Qwen3-1.7B | Berkeley Function Calling Leaderboard (BFCL) | 56.6% BFCL v3, thinking mode (Table 19). Non-thinking 52.2 (Table 20) | 54.7% Leaderboard, native function calling | +1.9 pts | |
| Qwen3-VL-235B-A22B | MMMU | 80.6% MMMU_VAL | 78.7% Leaderboard | +1.9 pts | |
| Gemini 3 Flash | FACTS Benchmark Suite | 61.9% FACTS Benchmark Suite | 63.8% Leaderboard | −1.9 pts | |
| Muse Spark Open | FORTRESS | 5.80% FORTRESS adversarial (static), ARS 5.8 / ORS 17.4, lower is better | 7.64% Leaderboard | +1.8 pts | |
| Qwen3-235B-A22B | IFEval | 83.4% IFEval strict prompt | 81.6% Leaderboard, strict, share of instructions followed | +1.8 pts | |
| Kimi-VL-A3B-Thinking-2506 | ScreenSpot-Pro | 52.8% ScreenSpot-Pro (Acc) | 51% Leaderboard | +1.8 pts | |
| GLM-5 | GPQA Diamond | 86% GPQA-Diamond | 87.8% Epoch AI run | −1.8 pts | |
| Mistral 7B v0.1 | HumanEval | 30.5% HumanEval | 28.7% Leaderboard | +1.8 pts | |
| Claude Opus 4.7 | MCP Atlas | 77.3% Scaled tool use MCP-Atlas | 79.1% Leaderboard, max | −1.8 pts | |
| phi-3-small 7.4B | MedQA | 65.4% MedQA (2-Shot) (Section 3 table) | 67.2% Leaderboard | −1.8 pts | |
| Kimi K2 Jul 2025 | tau2-bench | 66.1% τ2-Bench micro Pass@1 across domains (Appendix C text). Avg@4: retail 70.6, airline 56.5, telecom 65.8 (Table 3) | 64.3% Leaderboard | +1.8 pts | |
| o4-mini | GPQA Diamond | 81.4% GPQA Diamond (no tools) | 79.6% Epoch AI run, high | +1.8 pts | |
| Claude Haiku 4.5 | GPQA Diamond | 73% Graduate-level reasoning GPQA Diamond | 71.2% Epoch AI run, 32K | +1.8 pts | |
| Gemini 3.8 Flash-Lite TTS | Voice Arena Hindi | 1,076 Voice Arena hindi, Elo, Gemini speech generation model page | 1,057 Leaderboard | +19 | |
| GPT-5 nano | GPQA Diamond | 71.2% GPQA diamond (no tools) | 69.4% Epoch AI run, high | +1.8 pts | |
| Qwen3-8B | Berkeley Function Calling Leaderboard (BFCL) | 68.1% BFCL v3, thinking mode (Table 17). Non-thinking 60.2 (Table 18) | 66.3% Leaderboard, native function calling | +1.8 pts | |
| Nova 2 Lite | tau2-bench Verified | 70.7% Mean of τ2-bench Retail-Verified 76.5 / Airline-Verified 64.8 (avg@3) | 72.4% Leaderboard, tau2-bench-verified; gpt-5.1 user simulator | −1.7 pts | |
| Tencent Hy3 | E-Bench (Tencent) | 50.2% e-bench (internal) | 48.5% Leaderboard, highest available reasoning | +1.7 pts | |
| DeepSeek-V3.2-Speciale | HMMT 2025 | 99.2% HMMT Feb 2025 (Pass@1), DeepSeek-V3.2-Speciale (Table 3) | 97.5% Leaderboard | +1.7 pts | |
| Claude 2 | HumanEval | 71.2% Codex P@1 (0-shot) | 69.5% Leaderboard | +1.7 pts | |
| Claude Opus 4.5 | SWE-bench Verified | 80.9% Agentic coding SWE-bench Verified | 79.2% Leaderboard, Sonar Foundation Agent | +1.7 pts | |
| DeepSeek-R1 May 2025 | AIME 2025 | 87.5% AIME 2025 (Pass@1) | 89.2% Leaderboard | −1.7 pts | |
| Qwen3-Coder-480B-A35B | Multi-SWE-bench flash | 27% Multi-SWE-bench flash | 25.3% Leaderboard, unverified, MopenHands | +1.7 pts | |
| Nemotron 3 Ultra | GPQA Diamond | 87% GPQA (no tools) | 85.3% Epoch AI run | +1.7 pts | |
| Qwen3-Coder-480B-A35B | SWE-bench-Live | 26.3% SWE-bench Live | 24.7% Leaderboard, OpenHands | +1.6 pts | |
| Gemini 2.5 Pro Mar 2025 | AIME 2025 | 86.7% AIME 2025, single attempt (pass@1) | 88.3% Leaderboard | −1.6 pts | |
| DeepSeek-V3.1 | HMMT 2025 | 84.2% HMMT 2025 (Pass@1) | 85.8% Leaderboard, thinking | −1.6 pts | |
| Grok 4 Fast | HMMT 2025 | 93.3% HMMT 2025 (no tools) pass@1 | 91.7% Leaderboard | +1.6 pts | |
| Qwen2-72B | GPQA Diamond | 42.4% GPQA | 40.8% Epoch AI run | +1.6 pts | |
| Gemini 4 Argon | Riemann-bench | 76% RiemannBench | 74.4% Leaderboard, high | +1.6 pts | |
| Claude Opus 5.5 | Terminal-Bench 4.0 | 66.4% Agentic coding Terminal-Bench 4.0 (xhigh effort) | 64.8% Leaderboard, max, Claude Code | +1.6 pts | |
| GPT-6.1 Terra | Terminal-Bench 4.0 | 50.3% Terminal-Bench 4.0, maximum reasoning effort | 51.8% Leaderboard, max, Codex | −1.5 pts | |
| Mistral Small 3.1 | GPQA Diamond | 46% GPQA Diamond (5-shot CoT) | 47.5% Epoch AI run | −1.5 pts | |
| Claude Opus 4.7 | ARC-AGI | 92% ARC-AGI-1 | 93.5% Leaderboard, high | −1.5 pts | |
| MiMo-V2.6 Pro | MiMo Cyber Bench | 80.2% MiMo Cyber Bench | 81.7% Leaderboard | −1.5 pts | |
| Inkling-Small | SimpleQA Verified | 20.6% SimpleQA Verified | 19.1% Epoch AI run, xhigh | +1.5 pts | |
| LongCat-Flash-Chat | VITA-Bench | 24.3% VitaBench(avg@4) | 22.8% Leaderboard, non-thinking | +1.5 pts | |
| Qwen3.7-Max | GPQA Diamond | 92.4% GPQA Diamond | 90.9% Epoch AI run | +1.5 pts | |
| o3 | GPQA Diamond | 83.3% GPQA Diamond PhD-Level Science Questions, o3 (no tools) | 81.8% Epoch AI run, high | +1.5 pts | |
| Claude Sonnet 4.5 | OSWorld-Verified | 61.4% Computer use OSWorld (official OSWorld-Verified framework, 100 max steps) | 62.9% Leaderboard, 100 steps | −1.5 pts | |
| Seed-Prover 1.5 | PutnamBench | 87.9% PutnamBench 580/660 (87.9%) | 86.5% Leaderboard, 10 H20 days per problem | +1.4 pts | |
| Gemma 3 12B | GPQA Diamond | 40.9% GPQA Diamond, IT, zero-shot (Table 6) | 39.5% Epoch AI run | +1.4 pts | |
| Seed-Prover | PutnamBench | 50.4% PutnamBench 331/657 (Medium) | 49% Leaderboard, MEDIUM | +1.4 pts | |
| GPT-5 nano | HMMT 2025 | 75.6% HMMT 2025 (no tools) | 74.2% Leaderboard, high | +1.4 pts | |
| Granite 4.0 H Small | IFEval | 87.5% IFEval Average | 89% Leaderboard, strict, share of instructions followed | −1.4 pts | |
| Grok 4.5 | CyberGym | 80.4% CyberGym, mean reproduced, high, unrestricted (7.1) | 79% Leaderboard, Grok Build | +1.4 pts | |
| GPT-5.4 | SWE-Bench Pro | 57.7% SWE-Bench Pro (Public) | 59.1% Leaderboard, xhigh, mini-SWE-agent | −1.4 pts | |
| Claude Opus 4.8 | AutomationBench | 15.5% Automation Bench | 16.9% Leaderboard, xhigh | −1.4 pts | |
| Claude Fable 5.1 | scBench (LatchBio SingleCellBench) | 61.9% LatchBio SingleCellBench, Mythos 5.1 | 60.5% Leaderboard, published v1; LSVP, Pi | +1.4 pts | |
| Gemini 3.8 Flash-Lite TTS | Voice Arena Japanese | 1,152 Voice Arena japanese, Elo, Gemini speech generation model page | 1,136 Leaderboard | +16 | |
| GPT-5 mini | HMMT 2025 | 87.8% HMMT 2025 (no tools) | 89.2% Leaderboard, high | −1.4 pts | |
| GPT-4.1 nano | GPQA Diamond | 50.3% GPQA Diamond (model-extracted answers) | 48.9% Epoch AI run | +1.4 pts | |
| GPT-5 nano | FrontierMath | 9.60% FrontierMath (with python tool only) | 8.28% Leaderboard, high; task version 1.0.1, Epoch | +1.3 pts | |
| Grok 4.6 | APEX-SWE | 56.4% APEX-SWE | 57.7% Leaderboard, xhigh, terminus-2 | −1.3 pts | |
| Inkling | τ³-bench Banking | 23.7% Tau 3 Banking (Artificial Analysis) | 25% Leaderboard, max | −1.3 pts | |
| Beam 1.0 | BioTIER Permit | 97.2% BioTIER permit split accuracy | 98.5% Leaderboard, max | −1.3 pts | |
| Gemini 2.5 Flash Apr 2025 | LiveCodeBench v5 | 63.5% LiveCodeBench v5 single attempt (10/1/2024-2/1/2025) | 62.2% Leaderboard | +1.3 pts | |
| Gemini 3.8 Flash-Lite TTS | Voice Arena Vietnamese | 1,156 Voice Arena vietnamese, Elo, Gemini speech generation model page | 1,141 Leaderboard | +15 | |
| Kimi K3 | Vals Finance Agent v2 | 54.4% Finance Agent v2 | 53.1% Leaderboard | +1.3 pts | |
| DeepSeek-V4-Pro | HMMT 2026 | 95.2% HMMT 2026 Feb (Pass@1) | 93.9% Leaderboard, max | +1.3 pts | |
| Nemotron 3 Nano Omni 30B-A3B | OCRBench v2 | 67% OCRBenchV2 (EN) | 65.8% Leaderboard | +1.2 pts | |
| Claude Sonnet 5.5 | scBench (LatchBio SingleCellBench) | 59.1% LatchBio SingleCellBench (8.17.2, Figure 8.17.A) | 60.3% Leaderboard, published v1, Pi | −1.2 pts | |
| Gemini 3.8 Flash TTS | Voice Arena Mexican Spanish | 1,152 Voice Arena mexican spanish, Elo, Gemini speech generation model page | 1,138 Leaderboard | +14 | |
| Qwen2-72B | Arena-Hard-Auto | 48.1% Arena-Hard | 46.9% Leaderboard | +1.2 pts | |
| Step 3.7 Flash | Claw-Eval Pass^3 | 67.1% Claweval-v1.1 (pass^3) | 68.3% Leaderboard | −1.2 pts | |
| GPT-4o mini | HumanEval | 87.2% HumanEval | 88.4% Leaderboard | −1.2 pts | |
| DeepSeek-V2.5 Sep 2024 | HumanEval | 89% HumanEval python | 90.2% Leaderboard | −1.2 pts | |
| Mixtral 8x7B | MBPP | 60.7% MBPP (pass@1) | 59.5% Leaderboard, EvalPlus subset, original tests | +1.2 pts | |
| Qwen3-VL-235B-A22B | MMMU-Pro | 69.3% MMMU_Pro | 68.1% Leaderboard | +1.2 pts | |
| Gemini 3 Pro | SWE-bench Verified | 76.2% SWE-Bench Verified (Single attempt) | 77.4% Leaderboard, live-SWE-agent | −1.2 pts | |
| Kimi K3 | Code Arena | 1,678 WebDev Arena (Elo), rank 1 of 99 (Table 5). Mapped to the current Arena WebDev board | 1,658 Leaderboard, max | +20 | Moonshot quotes Arena's July 23 rating, while the board reflects votes collected through November. |
| Grok 4.1 | LMArena (Elo) | 1,483 LMArena Text Leaderboard overall Elo (Grok 4.1 Thinking, 'quasarflux') | 1,465 Leaderboard, thinking | +18 | xAI quotes Grok 4.1 Thinking's launch rating, while the board reports its later Arena rating. |
| DeepSeek-V3.2 | MCPMark | 38% MCP-Mark (Pass@1) | 36.8% Leaderboard, thinking | +1.2 pts | |
| Grok 4 Fast | AIME 2025 | 92% AIME 2025 (no tools) pass@1 | 90.8% Leaderboard | +1.2 pts | |
| Qwen 3.6 35B-A3B | GPQA Diamond | 86% GPQA | 84.8% Epoch AI run, none | +1.2 pts | |
| Claude Opus 4.1 | SWE-bench Verified | 74.5% Agentic coding SWE-bench Verified | 73.3% Epoch AI run | +1.2 pts | |
| GPT-5.4 | Vals Finance Agent | 56% FinanceAgent v1.1 (GPT-5.4) | 57.1% Leaderboard, xhigh | −1.1 pts | |
| Gemini 3.8 Flash TTS | Voice Arena Vietnamese | 1,135 Voice Arena vietnamese, Elo, Gemini speech generation model page | 1,122 Leaderboard | +13 | |
| GPT-5.3 Codex | Terminal-Bench 2.0 | 77.3% Terminal-Bench 2.0 | 78.4% Leaderboard, SageAgent | −1.1 pts | |
| GPT-4.1 | MultiChallenge | 38.3% MultiChallenge | 39.4% Leaderboard | −1.1 pts | |
| GPT-5.4 Mini | GPQA Diamond | 88% GPQA Diamond | 86.9% Epoch AI run, xhigh | +1.1 pts | |
| EmbeddingGemma 2 | MAEB | 49.9 MAEB, Mean(Task), full precision, 768d | 49.3 Leaderboard | +0.56 | |
| Gemini 2.5 Pro Jun 2025 | GPQA Diamond | 86.4% GPQA diamond, single attempt (pass@1) | 85.3% Epoch AI run | +1.1 pts | |
| Claude Opus 4.8 | scBench (LatchBio SingleCellBench) | 58.2% LatchBio Bioinformatics, SingleCellBench, no extended thinking (8.16.3) | 57.1% Leaderboard, published v1, Pi | +1.1 pts | |
| GPT-5.6 Sol | Molecular Biology Capabilities Test | 60% SecureBio Molecular Biology Capabilities Test, strongest reported configuration (9.1.1.8) | 61.1% Leaderboard, max | −1.1 pts | |
| Gemini 2.5 Pro Mar 2025 | Aider Polyglot | 74% Aider Polyglot, whole (diff = 68.6%) | 72.9% Leaderboard, aider, diff-fenced edits | +1.1 pts | |
| GPT-5.6 Sol | GPQA Diamond | 94.6% GPQA Diamond | 93.5% Epoch AI run, max | +1.1 pts | |
| Grok 4 | HMMT 2025 | 93.9% HMMT 2025, with Python (no tools 90.0) | 95% Leaderboard | −1.1 pts | |
| Kimi-VL-A3B-Thinking-2506 | MM-Vet | 78.1% MMVet (Acc) | 77% Leaderboard | +1.1 pts | |
| Gemini 2.5 Flash Jun 2025 | FACTS Grounding | 85.3% FACTS Grounding | 86.4% Leaderboard | −1.1 pts | |
| Claude Sonnet 4.5 | GPQA Diamond | 83.4% Graduate-level reasoning GPQA Diamond | 82.3% Epoch AI run, 59k thinking | +1.1 pts | |
| Claude Fable 5.2 | FrontierCode 2.0 | 49.1% Agentic coding FrontierCode 2.0, Xhigh effort, best effort score (launch table and Table 8.1.A) | 50.2% Leaderboard, xhigh, Claude Code | −1.1 pts | |
| DeepSeek-V3.2 | AIME 2025 | 93.1% AIME 2025 (Pass@1) | 94.2% Leaderboard, thinking | −1.1 pts | |
| DeepSeek-V3.2-Speciale | HMMT Nov 2025 | 94.4% HMMT Nov 2025 (Pass@1), DeepSeek-V3.2-Speciale (Table 3) | 93.3% Leaderboard | +1.1 pts | |
| o1 | GPQA Diamond | 75.7% GPQA diamond | 76.8% Epoch AI run, high | −1.1 pts | |
| Llama 3-70B | GPQA Diamond | 39.5% GPQA (0-shot) [instruct] | 40.6% Epoch AI run | −1.1 pts | |
| Inkling | GPQA Diamond | 87.2% GPQA Diamond (Artificial Analysis) | 88.3% Epoch AI run, xhigh | −1.1 pts | |
| DeepSeek V4.1 Flash | GPQA Diamond | 90.9% GPQA Diamond (Pass@1) | 89.8% Epoch AI run, max | +1.1 pts | |
| GPT-5.6 Terra | FrontierMath Tiers 1-3 v2 | 84.9% FrontierMath Tier 1-3 (v2) | 86% Leaderboard, max; task version 2.0.0, Epoch | −1.1 pts | |
| Qwen3-32B | Berkeley Function Calling Leaderboard (BFCL) | 70.3% BFCL v3, thinking mode (Table 13). Non-thinking 63.0 (Table 14) | 69.3% Leaderboard, native function calling | +1.0 pts | |
| Qwen3-235B-A22B-Thinking Jul 2025 | GPQA Diamond | 81.1% GPQA | 80% Epoch AI run | +1.0 pts | |
| o4-mini | AIME 2025 | 92.7% AIME 2025 (no tools) | 91.7% Leaderboard, high | +1.0 pts | |
| Step 3.5 Flash | AIME 2025 | 97.3% AIME 2025 | 98.3% Leaderboard | −1.0 pts | |
| DeepSeek-V3.2 | GPQA Diamond | 82.4% GPQA Diamond (Pass@1) | 83.4% Epoch AI run, Thinking | −1.0 pts | |
| Kimi K3 | DeepSWE | 67.5% DeepSWE (v1.1) | 68.5% Leaderboard, max, mini-swe-agent | −1.0 pts | |
| Gemini 3 Flash | GPQA Diamond | 90.4% GPQA Diamond (No tools) | 89.4% Epoch AI run, high | +1.0 pts | |
| GLM-5V-Turbo | Claw-Eval | 75% ClawEval Pass^3 / Pass@3 57.7 / 75.0 | 74% Leaderboard | +1.0 pts | |
| Qwen3-Max | DeepPlanning | 28.7% Deep Planning | 29.7% Leaderboard, v1.1; thinking | −1.0 pts | |
| GPT-5.2 | GPQA Diamond | 92.4% GPQA Diamond (no tools) Science questions | 91.4% Epoch AI run, xhigh | +1.0 pts | |
| GPT-5.4 Mini | MCP Atlas | 57.7% MCP-Atlas | 56.7% Leaderboard, xhigh | +1.0 pts | |
| GLM-5.2 | MCP Atlas | 76.8% MCP-Atlas (Public Set) | 77.8% Leaderboard | −1.0 pts | |
| DeepSeek-R1 May 2025 | MMLU-Pro | 85% MMLU-Pro (EM) | 84% Leaderboard | +1.0 pts | |
| Muse Wonder Full | ProgramBench almost solved | 59% ProgramBench, rollouts passing at least 95% of tests, mini-swe-agent, Muse Wonder Full (max) (capabilities table image, page 3) | 60% Leaderboard, mini-SWE-agent | −1.0 pts | |
| DeepSeek-V4-Pro | Toolathlon | 51.8% Toolathlon (Pass@1) | 52.8% Leaderboard | −1.0 pts | |
| Gemini 3.8 Flash TTS | Voice Arena Arabic MSA | 1,204 Voice Arena arabic msa, Elo, Gemini speech generation model page | 1,192 Leaderboard | +12 | |
| Gemini 2.0 Flash Feb 2025 | FACTS Grounding | 84.6% FACTS Grounding | 85.6% Leaderboard | −1.0 pts | |
| Inkling-Small | GPQA Diamond | 89.5% GPQA Diamond | 88.5% Epoch AI run, xhigh | +1.0 pts | |
| Gemini 2.0 Pro | GPQA Diamond | 64.7% GPQA (diamond) | 65.7% Epoch AI run | −1.0 pts | |
| Claude Fable 5 | OSWorld-Verified | 85% Computer use OSWorld-Verified | 86% Leaderboard, 1M context, 100 steps | −1.0 pts | |
| Gemini 3.8 Flash-Lite TTS | Voice Arena Mexican Spanish | 1,146 Voice Arena mexican spanish, Elo, Gemini speech generation model page | 1,135 Leaderboard | +11 | |
| GLM-5 | Code Arena | 1,449 LMArena Code Arena (Agentic WebDev) score, rank 6 (Figure 3 screenshot) | 1,435 Leaderboard | +14 | The lab reproduces an early Code Arena snapshot, while the board uses a later rating from additional votes. |
| Claude Opus 4.5 | GPQA Diamond | 87% Graduate-level reasoning GPQA Diamond | 86% Epoch AI run, 32k thinking | +1.0 pts | |
| Claude Opus 5 | AutomationBench | 26% Business workflows AutomationBench | 26.9% Leaderboard, max | −0.9 pts | |
| Qwen2.5-7B | GPQA Diamond | 36.4% GPQA, variant not stated, Qwen2.5-7B-Instruct (Table 8) | 35.5% Epoch AI run | +0.9 pts | |
| Qwen3-30B-A3B | AIME 2025 | 70.9% AIME’25, thinking mode (Table 15). Non-thinking 21.6 (Table 16) | 70% Leaderboard | +0.9 pts | |
| o1 | MMMU | 77.3% MMMU (pass @1) | 78.2% Leaderboard | −0.9 pts | |
| Seed-Prover | Past IMO (Seed-Prover formal set) | 78.1% Past IMO (Heavy), 155 problems | 79% Leaderboard, Heavy, Seed Prover multi-agent inference | −0.9 pts | |
| GPT-4.1 nano | Aider Polyglot | 9.80% Aider's polyglot: whole 9.8 (diff 6.2) | 8.90% Leaderboard, aider, whole edits | +0.9 pts | |
| Kimi K2 Jul 2025 | Aider Polyglot | 60% Aider-Polyglot, Acc | 59.1% Leaderboard, aider, diff edits | +0.9 pts | |
| Gemini 2.5 Pro Jun 2025 | Aider Polyglot | 82.2% Aider Polyglot (diff-fenced) | 83.1% Leaderboard, aider, diff-fenced edits | −0.9 pts | |
| Claude 3 Haiku | HumanEval | 75.9% HumanEval, 0-shot (Table 1) | 76.8% Leaderboard | −0.9 pts | |
| EXAONE 4.0 32B | LiveCodeBench v5 | 72.6% LiveCodeBench v5 (reasoning) | 71.7% Leaderboard | +0.9 pts | |
| GPT-5.4 | MMMU-Pro | 81.2% MMMU Pro (no tools) | 82.1% Leaderboard, thinking, with tools | −0.9 pts | |
| Mistral Large 2 Jul 2024 | WildBench | 56.3 Wild Bench | 55.8 Leaderboard | +0.50 | |
| Kimi K2 Jul 2025 | SuperGPQA | 57.2% SuperGPQA, Acc | 58.1% Leaderboard | −0.9 pts | |
| Qwen 3.8 Max | DeepSWE | 56.6% DeepSWE 1.1 | 57.5% Leaderboard, xhigh, mini-swe-agent | −0.9 pts | |
| DeepSeek-V4-Flash | HMMT 2026 | 94.8% HMMT 2026 Feb (Pass@1), V4-Flash Max | 93.9% Leaderboard, max | +0.9 pts | |
| GPT-4.1 mini | GPQA Diamond | 65% GPQA Diamond (model-extracted answers) | 65.8% Epoch AI run | −0.8 pts | |
| DeepSeek-V4-Pro | GPQA Diamond | 90.1% GPQA Diamond (Pass@1) | 90.9% Epoch AI run, high | −0.8 pts | |
| Kimi K3.1 Pro | Business Operation (Moonshot) | 37.8% Business Operation (Internal) | 37% Leaderboard | +0.8 pts | |
| Kimi K2.5 | MATH-Vision (MathVision) | 84.2% MathVision | 85% Leaderboard, thinking, with python | −0.8 pts | |
| Nemotron Nano 12B v2 VL | OCRBench v2 | 62% OCRBenchv2 (English) | 61.2% Leaderboard | +0.8 pts | |
| Qwen2.5-VL-72B | SEED-Bench-2-Plus | 73% SEED-Bench-2-Plus (Table 5) | 73.8% Leaderboard | −0.8 pts | |
| Claude Haiku 5.5 | Terminal-Bench 4.0 | 39.2% Agentic coding Terminal-Bench 4.0 | 40% Leaderboard, max, Claude Code | −0.8 pts | |
| Claude Sonnet 4.5 | Vals Finance Agent | 55.3% Financial analysis Finance Agent | 54.5% Leaderboard, thinking | +0.8 pts | |
| Inkling 2 Small | DesignArena Frontend Web App | 1,296 DesignArena Web Apps | 1,286 Leaderboard | +10 | |
| Claude Opus 4.6 | GPQA Diamond | 91.3% Graduate-level reasoning GPQA Diamond | 90.5% Epoch AI run, 32k thinking | +0.8 pts | |
| Gemini 3.8 Flash-Lite TTS | Voice Arena Arabic MSA | 1,181 Voice Arena arabic msa, Elo, Gemini speech generation model page | 1,172 Leaderboard | +9 | |
| Gemma 3 1B | GPQA Diamond | 19.2% GPQA Diamond, IT, zero-shot (Table 6) | 19.9% Epoch AI run | −0.8 pts | |
| Qwen3.5-35B-A3B | GPQA Diamond | 84.2% GPQA Diamond | 83.5% Epoch AI run | +0.7 pts | |
| Nemotron 3.5 Super VL | OCRBench v2 | 68.1% OCRBench v2, EN 68.12 / ZH 59.15 | 67.4% Leaderboard | +0.7 pts | |
| Claude Fable 5.1 | FrontierSWE | 57% FrontierSWE v2, mean score 0.57 on a 0 to 1 scale, max effort, Proximal harness, 5 trials per task (8.5) | 56.3% Leaderboard, mean@5, proximus | +0.7 pts | |
| Gemini 3 Pro | GPQA Diamond | 91.9% GPQA Diamond (No tools) | 92.6% Epoch AI run | −0.7 pts | |
| GPT-5.6 Luna | GPQA Diamond | 92.3% GPQA Diamond | 91.6% Epoch AI run, max | +0.7 pts | |
| Qwen3-235B-A22B | LiveCodeBench v5 | 70.7% LiveCodeBench v5 | 70% Leaderboard | +0.7 pts | |
| Qwen2.5-VL-72B | MM-Vet | 76.2% MMVet turbo (Table 3) | 76.9% Leaderboard | −0.7 pts | |
| Beam 1.0 | Molecular Biology Capabilities Test | 48.5% MBCT exact-match accuracy | 49.2% Leaderboard, max | −0.7 pts | |
| Nemotron 3.5 Super VL | Terminal-Bench 4.0 | 1.00% Terminal Bench 4 [offline] | 0.30% Leaderboard, none, mini-swe-agent | +0.7 pts | |
| GPT-5.5 | FrontierMath | 52.4% FrontierMath Tier 1–3 (GPT-5.5 Pro) | 51.7% Epoch AI run, xhigh | +0.7 pts | |
| Qwen 3.8 Max | JobBench | 53.4% JobBench | 52.7% Leaderboard, OpenCode | +0.7 pts | |
| Claude Opus 5.5 | scBench (LatchBio SingleCellBench) | 61.2% LatchBio Bioinformatics, SingleCellBench, 195 problems, max effort (8.17.2) | 61.9% Leaderboard, published v1; LSVP, Pi | −0.7 pts | |
| Qwen3-235B-A22B | AIME 2025 | 81.5% AIME’25 | 80.8% Leaderboard | +0.7 pts | |
| GLM-5.2 | GPQA Diamond | 91.2% GPQA-Diamond | 91.9% Epoch AI run, max | −0.7 pts | |
| Grok 3 | LMArena (Elo) | 1,402 Chatbot Arena Score (early Grok 3 'chocolate') | 1,411 Leaderboard | −9 | The lab quotes the early chocolate model snapshot, while the board rates the later Grok 3 Preview release with style controls. |
| GPT-5.4 | ARC-AGI-2 | 73.3% ARC-AGI-2 (Verified) | 74% Leaderboard, xhigh | −0.7 pts | |
| Claude Opus 4.6 | Vals Finance Agent | 60.7% Agentic financial analysis Finance Agent | 60% Leaderboard, thinking | +0.7 pts | |
| Gemini 2.5 Pro Mar 2025 | Humanity's Last Exam | 18.8% Humanity's Last Exam (no tools) | 18.2% Leaderboard | +0.6 pts | |
| Gemini 3.8 Flash TTS | Voice Arena Brazilian Portuguese | 1,104 Voice Arena brazilian portuguese, Elo, Gemini speech generation model page | 1,097 Leaderboard | +7 | |
| Gemini 3.8 Flash-Lite TTS | Voice Arena Brazilian Portuguese | 1,134 Voice Arena brazilian portuguese, Elo, Gemini speech generation model page | 1,127 Leaderboard | +7 | |
| Llama 3-8B | HumanEval | 62.2% HumanEval (0-shot), instruction tuned (Instruction tuned models table) | 61.6% Leaderboard | +0.6 pts | |
| Tencent Hy3 | SkillsBench | 55.3% SkillsBench (79, text-only) | 55.9% Leaderboard, Claude Code | −0.6 pts | |
| o1-mini | SimpleQA | 7.00% SimpleQA, accuracy (Table 2) | 7.60% Leaderboard | −0.6 pts | |
| Gemma 3 27B | Global MMLU Lite | 75.7% Global-MMLU-Lite (PT); IT 0-shot = 75.1 | 76.3% Leaderboard | −0.6 pts | |
| Llama 4 Behemoth | MMLU-Pro | 82.2% MMLU Pro | 82.8% Leaderboard | −0.6 pts | |
| Claude Opus 5 | Terminal-Bench 3.0 | 43.3% Agentic terminal coding Frontier-Bench v0.1 | 42.7% Leaderboard, max, mini-SWE-agent | +0.6 pts | |
| Inkling 2 Small | DesignArena Website | 1,340 DesignArena Website | 1,332 Leaderboard | +8 | |
| Gemini 4 Argon | nocot-bench (NCRI) | 150.3 No Chain of Thought Reasoning Index (NCRI, Nanda 2026), 150.3 without filler tokens (152.1 with filler tokens); about 5.5 serial arithmetic steps at 50% (3.4.5.3, Figures 3.23 and 3.24) | 151.2 Leaderboard, NCRI 15.2; no filler; placed_after_release | −0.9 | |
| Kimi K2.6 | AIME 2026 | 96.4% AIME 2026 | 95.8% Leaderboard, high | +0.6 pts | |
| Cohere Command A | Berkeley Function Calling Leaderboard (BFCL) | 63.8% BFCL Overall from the official leaderboard (Table 5). Live AST 80.5, Multi-turn 25.5 | 64.4% Leaderboard, native function calling | −0.6 pts | |
| Gemini 3.8 Flash-Lite TTS | Voice Arena US English | 1,087 Voice Arena us english, Elo, Gemini speech generation model page | 1,081 Leaderboard | +6 | |
| GLM-5.1 | AIME 2026 | 95.3% AIME 2026 | 95.8% Leaderboard | −0.5 pts | |
| Qwen-Turbo | GPQA Diamond | 42.3% GPQA, variant not stated, Qwen2.5-Turbo (Table 7) | 41.8% Epoch AI run | +0.5 pts | |
| GPT-4.1 | Aider Polyglot | 52.9% Aider's polyglot: diff | 52.4% Leaderboard, aider, diff edits | +0.5 pts | |
| Gemma 3 27B | BBEH micro average | 19.3% BIG-Bench Extra Hard 0-shot (IT) | 18.8% Leaderboard | +0.5 pts | |
| GPT-5.4 Pro | FrontierMath Tier 4 | 38% FrontierMath Tier 4 | 37.5% Epoch AI run, web | +0.5 pts | |
| Grok 4.7 | FrontierSWE | 29% FrontierSWE V2, mean@5 partial-credit score, xhigh, run by Proximal Labs (2.4) | 29.5% Leaderboard, mean@5, proximus | −0.5 pts | |
| Grok 4 | GPQA Diamond | 87.5% GPQA (Science), no tools | 87% Epoch AI run | +0.5 pts | |
| GPT-5.4 | GPQA Diamond | 92.8% GPQA Diamond (GPT-5.4) | 93.3% Epoch AI run, xhigh | −0.5 pts | |
| Muse Wonder | ProgramBench almost solved | 50% ProgramBench, rollouts passing at least 95% of tests, mini-swe-agent, Muse Wonder (max) (capabilities table image, page 3) | 50.5% Leaderboard, xhigh, mini-SWE-agent | −0.5 pts | |
| GPT-5 | SWE-bench Verified | 74.9% SWE-bench Verified (n=477), GPT-5 with thinking | 74.4% Leaderboard, Prometheus-v1.2.1 | +0.5 pts | |
| Gemini 2.5 Pro Jun 2025 | ZeroBench | 4.50% ZeroBench, Gemini as judge, average of 4 runs (Table 3) | 5.00% Leaderboard | −0.5 pts | |
| Qwen2.5-72B | MMLU-Pro | 71.1% MMLU-Pro | 71.6% Leaderboard | −0.5 pts | |
| Grok 4.6 | Terminal-Bench 3.0 | 26% Terminal-Bench v3.0 | 26.5% Leaderboard, high, Grok Build | −0.5 pts | |
| Grok 4.6 | DeepSWE | 67% DeepSWE v1.1, Pass@1, xhigh, mini-swe-agent, run by Datacurve (2.4). High = 65.9% | 67.5% Leaderboard, medium, mini-swe-agent | −0.5 pts | |
| GPT-5.1 | GPQA Diamond | 88.1% GPQA Diamond (no tools) | 87.6% Epoch AI run, high | +0.5 pts | |
| Kimi K2.5 | OJBench | 57.4% OJBench (cpp) | 57% Leaderboard, thinking | +0.4 pts | |
| Qwen2-72B | CMMLU | 90.1% CMMLU | 89.7% Leaderboard, Five-shot | +0.4 pts | |
| GLM-4.1V-9B-Thinking | MotionBench | 59% MotionBench | 59.4% Leaderboard, frames: 2fps | −0.4 pts | |
| Claude Sonnet 5 | scBench (LatchBio SingleCellBench) | 56% LatchBio SingleCellBench, 195 problems, score 0.56 (8.14.2, Figure 8.14.6.A) | 55.6% Leaderboard, published v1, Pi | +0.4 pts | |
| Muse Spark Open | GPQA Diamond | 89% GPQA Diamond | 88.6% Epoch AI run, xhigh | +0.4 pts | |
| Nemotron 3.5 Bolt E4B | MultiChallenge | 55.6% MultiChallenge | 56% Leaderboard, thinking | −0.4 pts | |
| Grok 4.7 | Terminal-Bench 4.0 | 38% Terminal-Bench 4.0, task success rate, xhigh, Grok Build harness, run by Harbor (2.3) | 37.6% Leaderboard, xhigh, Grok Build | +0.4 pts | |
| Mistral Large 4 | Terminal-Bench 4.0 | 28.3% Coding - Terminal Bench 4.0: AA - Terminal-Bench 4 (chart 28; text 28.3%) | 27.9% Leaderboard, max, Claude Code | +0.4 pts | |
| DeepSeek-Prover-V2-671B | PutnamBench | 7.40% PutnamBench 49 out of 658 problems solved | 6.99% Leaderboard, pass@1024 | +0.4 pts | |
| GPT-5.6 Terra | GPQA Diamond | 92.9% GPQA Diamond | 93.3% Epoch AI run, max | −0.4 pts | |
| Inkling 2 Small | Code Arena | 1,653 Code Arena, 1653 Elo | 1,646 Leaderboard | +7 | |
| GPT-5.2 | FrontierMath | 40.3% FrontierMath (Tier 1–3) Advanced mathematics | 40.7% Leaderboard, xhigh; task version 1.1.2, Epoch | −0.4 pts | |
| GPT-5.5 | GPQA Diamond | 93.6% GPQA Diamond | 94% Epoch AI run, xhigh | −0.4 pts | |
| GLM-5 | HMMT 2025 | 97.9% HMMT Feb. 2025 (Table 7) | 97.5% Leaderboard | +0.4 pts | |
| Inkling 2 Small | MCP Atlas | 85% MCP Atlas (Public; 85.4 on Full) | 85.4% Leaderboard | −0.4 pts | |
| Kimi-VL-A3B-Thinking-2506 | MMStar | 70.4% MMStar (Acc) | 70% Leaderboard | +0.4 pts | |
| DeepSeek-V4-Flash | Toolathlon | 47.8% Toolathlon (Pass@1), V4-Flash Max | 48.2% Leaderboard, max | −0.4 pts | |
| DeepSeek V4 Flash 0731 | Toolathlon-Verified | 70.3% Toolathlon-Verified | 70.7% Leaderboard, max | −0.4 pts | |
| o1-preview | SimpleQA | 42% SimpleQA, accuracy (Table 2) | 42.4% Leaderboard | −0.4 pts | |
| o3 | SimpleQA | 49% SimpleQA, accuracy (Table 4) | 49.4% Leaderboard | −0.4 pts | |
| Inkling-Small | MCP Atlas | 79.6% MCP Atlas public 79.6 / all 79.2 | 79.2% Leaderboard | +0.4 pts | |
| Kimi K2 Jul 2025 | SWE-bench Verified | 65.8% SWE-bench Verified (Agentic Coding), Single Attempt (Acc) | 65.4% Leaderboard, OpenHands | +0.4 pts | |
| Qwen3-235B-A22B | GPQA Diamond | 71.1% GPQA-Diamond | 70.7% Epoch AI run | +0.4 pts | |
| o4-mini | Humanity's Last Exam | 17.7% Best of HLE no tools 14.28 / with python + browsing tools 17.7 | 18.1% Leaderboard, high | −0.4 pts | |
| Kimi K3 | GPQA Diamond | 93.5% GPQA Diamond | 93.1% Epoch AI run, max | +0.4 pts | |
| GLM-5 | LMArena (Elo) | 1,452 LMArena Text Arena score, rank 11 (Figure 3 screenshot); LMsys Chatbot Arena 1452 (Figure 11) | 1,457 Leaderboard | −5 | Z.ai quotes an earlier Arena rating, while the board reports a later rating from updated votes and scoring. |
| Claude Opus 4.6 | ARC-AGI-2 | 68.8% Novel problem-solving ARC AGI 2 | 69.2% Leaderboard, 120k, high | −0.4 pts | |
| Phi-3.5-mini | MMLU-Pro | 47.5% MMLU-Pro (0-shot, CoT) (Table 3) | 47.9% Leaderboard | −0.4 pts | |
| Gemini 2.0 Flash-Lite | FACTS Grounding | 83.6% FACTS Grounding | 83.2% Leaderboard | +0.4 pts | |
| Claude Fable 5 | AutomationBench | 17.4% Tool use AutomationBench | 17.1% Leaderboard, max | +0.3 pts | |
| Inkling 2 Small | DesignArena Game Dev | 1,428 DesignArena Game Dev | 1,433 Leaderboard | −5 | |
| Nemotron 3.5 Super VL | LMArena (Elo) | 1,420 Text Arena, Overall, With Style Control, 1420 +/- 12, 2,328 votes, preliminary NVFP4 (Table 11) | 1,415 Leaderboard, nvfp4 | +5 | NVIDIA reports a preliminary Arena rating from 2,328 votes, while the board reports a later rating. |
| Gemini 1.5 Pro May 2024 | GPQA Diamond | 46.2% GPQA, 0-shot | 45.9% Epoch AI run | +0.3 pts | |
| GPT-4.1 mini | SWE-bench Verified | 23.6% SWE-bench Verified (477 of 500 tasks) | 23.9% Leaderboard, mini-SWE-agent | −0.3 pts | |
| phi-3-medium 14B | MedQA | 69.9% MedQA (2-Shot) (Section 3 table) | 69.6% Leaderboard | +0.3 pts | |
| GPT-5 | FrontierMath | 32.1% FrontierMath, Tier 1-3, GPT-5 pro (python) | 32.4% Leaderboard, high; task version 1.1.0, Epoch | −0.3 pts | |
| DeepSeek V4 Pro 0813 | Toolathlon-Verified | 74.1% Toolathlon-Verified | 74.4% Leaderboard, max | −0.3 pts | |
| Muse Spark | GPQA Diamond | 89.5% GPQA Diamond (PhD Level Reasoning) | 89.8% Epoch AI run | −0.3 pts | |
| Beam 1.0 | Human Pathogen Capabilities Test | 61% HPCT accuracy | 60.7% Leaderboard, max | +0.3 pts | |
| Mistral Large | MBPP | 73.1% MBPP (pass@1) | 72.8% Leaderboard, EvalPlus subset, original tests | +0.3 pts | |
| Qwen2.5-VL-72B | MMBench | 88.6% MMBench-EN test 88.6, MMBench-CN test 87.9 (Table 3) | 88.3% Leaderboard | +0.3 pts | |
| Qwen2.5-VL-72B | MMStar | 70.8% MMStar | 70.5% Leaderboard | +0.3 pts | |
| GPT-6 Astra | VCT-v2 | 57.7% SecureBio VCT-v2, refusal-corrected accuracy, pre-release checkpoint (10.1.1.4) | 58% Leaderboard, max | −0.3 pts | |
| GLM-OCR | OmniDocBench v1.5 | 94.6 OmniDocBench v1.5 Overall (Tables 3 and 4). Text Edit 0.040, Formula CDM 93.90, Table TEDS 93.96, TEDS-S 96.39, Reading Order Edit 0.044 | 94.3 Leaderboard | +0.27 | |
| Kimi K2 Thinking | GPQA Diamond | 84.5% GPQA, no tools | 84.2% Epoch AI run | +0.3 pts | |
| Kimi K2.6 | GPQA Diamond | 90.5% GPQA-Diamond | 90.8% Epoch AI run | −0.3 pts | |
| GPT-6 Astra | Terminal-Bench 4.0 | 57.9% Terminal-Bench 4.0 | 58.2% Leaderboard, max, Codex | −0.3 pts | |
| o3 | AIME 2025 | 88.9% AIME 2025 Competition Math, o3 (no tools) | 89.2% Leaderboard, high | −0.3 pts | |
| Kimi K2.5 | AIME 2025 | 96.1% AIME 2025 | 95.8% Leaderboard, high | +0.3 pts | |
| Qwen3-14B | GPQA Diamond | 64% GPQA-Diamond, thinking mode (Table 15). Non-thinking 54.8 (Table 16) | 63.8% Epoch AI run | +0.2 pts | |
| Qwen 3.6 Plus | QwenClawBench | 57.2% QwenClawBench | 57.4% Leaderboard, v1.1 | −0.2 pts | |
| Mistral Large 3 | LMArena (Elo) | 1,418 LMArena ELO Score (+/- 11) | 1,415 Leaderboard | +3 | Mistral quotes its December 2025 Arena rating, while the board reflects a later rating snapshot. |
| GPT-6 Astra | GPQA Diamond | 96% GPQA Diamond | 95.8% Epoch AI run, max | +0.2 pts | |
| Qwen2.5-32B | MMLU-Pro | 69% MMLU-Pro, Qwen2.5-32B-Instruct (Table 7) | 69.2% Leaderboard | −0.2 pts | |
| DeepSeek-R1 | GPQA Diamond | 71.5% GPQA-Diamond (Pass@1) | 71.7% Epoch AI run | −0.2 pts | |
| DeepSeek-R1-Distill-Qwen-1.5B | GPQA Diamond | 33.8% GPQA Diamond pass@1, DeepSeek-R1-Distill-Qwen-1.5B (Table 15) | 33.6% Epoch AI run | +0.2 pts | |
| GPT-5 nano | AIME 2025 | 85.2% AIME '25 (no tools) | 85% Leaderboard, high | +0.2 pts | |
| Qwen 3.6 Plus | Claw-Eval | 74.8% Claw-Eval Avg | 75% Leaderboard | −0.2 pts | |
| DeepSeek-V3.2 | HMMT Nov 2025 | 90.2% HMMT Nov 2025 (Pass@1) | 90% Leaderboard, thinking | +0.2 pts | |
| DeepSeek-R1 May 2025 | LiveCodeBench v6 | 73.3% LiveCodeBench (2408-2505) (Pass@1) | 73.1% Leaderboard | +0.2 pts | |
| Claude 3 Haiku | MBPP | 80.4% MBPP, Pass@1 (Table 1) | 80.2% Leaderboard, EvalPlus subset, original tests | +0.2 pts | |
| GLM-4.6 | SWE-bench Verified | 68% SWE-bench Verified | 68.2% Leaderboard, Undisclosed | −0.2 pts | |
| o4-mini | SimpleQA | 20% SimpleQA, accuracy (Table 4) | 20.2% Leaderboard | −0.2 pts | |
| DeepSeek-R1 May 2025 | Aider Polyglot | 71.6% Aider-Polyglot (Acc.) | 71.4% Leaderboard, aider, diff edits | +0.2 pts | |
| GPT-5.4 Pro | GPQA Diamond | 94.4% GPQA Diamond | 94.6% Epoch AI run, xhigh | −0.2 pts | |
| Claude 3 Sonnet | GPQA Diamond | 40.4% GPQA (Diamond), 0-shot CoT, mean of 10 rollouts. 5-shot CoT 42.9, Maj@32 5-shot CoT 46.3 (Table 1, Table 8) | 40.6% Epoch AI run | −0.2 pts | |
| Gemini 3.7 Flash | DeepSWE | 65.3% DeepSWE v1.1 | 65.5% Leaderboard, medium, mini-swe-agent | −0.2 pts | |
| Gemini 3.8 Flash TTS | Voice Arena US English | 1,061 Voice Arena us english, Elo, Gemini speech generation model page | 1,063 Leaderboard | −2 | |
| Llama 3.1-405B | GPQA Diamond | 51.1% GPQA (0-shot, CoT) | 50.9% Epoch AI run | +0.2 pts | |
| GPT-5.1 | AIME 2025 | 94% AIME 2025 (no tools) | 94.2% Leaderboard, high | −0.2 pts | |
| DeepSeek-V3.2-Speciale | AIME 2025 | 96% AIME 2025 (Pass@1), 23k output tokens, DeepSeek-V3.2-Speciale (Table 3) | 95.8% Leaderboard | +0.2 pts | |
| Step 3.5 Flash | HMMT Nov 2025 | 94% HMMT 2025 (Nov.) | 94.2% Leaderboard | −0.2 pts | |
| Gemini 2.5 Pro Mar 2025 | GPQA Diamond | 84% GPQA diamond, single attempt (pass@1) | 83.8% Epoch AI run | +0.2 pts | |
| Qwen2.5-72B | GPQA Diamond | 49% GPQA | 49.1% Epoch AI run | Same | |
| Gemini 3.1 Pro | GPQA Diamond | 94.3% GPQA Diamond (No tools) | 94.4% Epoch AI run, high | Same | |
| Gemini 3.8 Flash | DeepSWE | 73.7% DeepSWE v1.1 | 73.8% Leaderboard, high, mini-swe-agent | Same | |
| seed-oss-36b-instruct | GPQA Diamond | 71.4% GPQA-D | 71.5% Epoch AI run | Same | |
| Muse Spark 1.1 | OSWorld-Verified | 80.8% OSWorld-Verified (Agentic computer use) | 80.7% Leaderboard, 100 steps | Same | |
| GPT-5 | tau2-bench | 80.1% Mean of Tau2-bench Function calling (airline) / Tau2-bench Function calling (retail) / Tau2-bench Function calling (telecom) | 80% Leaderboard | Same | |
| GPT-5.6 Sol | FrontierMath Tiers 1-3 v2 | 89% FrontierMath Tier 1-3 (v2) | 89.1% Leaderboard, max; task version 2.0.0, Epoch | Same | |
| Phi-4-multimodal | Open ASR Leaderboard | 6.14% OpenASR, average WER over 8 sets, lower is better (Tables 3 and 4) | 6.02% Leaderboard | Same | |
| o3 | MultiChallenge | 56.5% Scale MultiChallenge Multi-turn instruction following | 56.6% Leaderboard, high | Same | |
| Qwen3-Max | tau2-bench | 82.1% Tau² Bench | 82.2% Leaderboard | Same | |
| Qwen2.5-VL-72B | MMBench-EN v1.1 | 88.4% MMBench-V1.1-EN test (Table 3) | 88.3% Leaderboard | Same | |
| Nemotron 3 Nano Omni 30B-A3B | MMLongBench-Doc | 57.5% MMlongBench Doc | 57.6% Leaderboard, Omni; 3B activated (30B total) | Same | |
| Qwen3-235B-A22B | PolyMath | 54.7% PolyMath | 54.6% Leaderboard, thinking | Same | |
| Qwen3.5-Omni-Flash | WorldSense (omnimodal) | 57.9% WorldSense, Qwen3.5-Omni-Flash | 57.8% Leaderboard, modality A+V | Same | |
| Muse Spark 1.1 | FORTRESS | 12.3% FORTRESS private split, Average Risk Score (Table 2, Figure 26) | 12.4% Leaderboard | Same | |
| Qwen 3.6 Plus | Claw-Eval Pass^3 | 58.7% Claw-Eval Pass^3 | 58.8% Leaderboard | Same | |
| Claude Mythos Preview | CyberGym | 83% CyberGym targeted vulnerability reproduction, pass@1 over 1,507 tasks, score 0.83, no thinking with think tool (3.3.2) | 83.1% Leaderboard, Anthropic Agent | Same | |
| Kimi K2 Jul 2025 | MMLU-Pro | 81.1% MMLU-Pro, EM | 81% Leaderboard | Same | |
| Qwen3-235B-A22B-Thinking Jul 2025 | MMLU-Pro | 84.4% MMLU-Pro | 84.5% Leaderboard | Same | |
| GPT-5.4 | Online-Mind2Web | 92.8% Online-Mind2Web, screenshot-based observations only | 92.7% Leaderboard, ACT-2 | Same | |
| Leanstral 1.5 | PutnamBench | 87.4% PutnamBench 587/672 solved (pass@8, 4M tokens per attempt) | 87.5% Leaderboard, 4m tokens per problem | Same | |
| Grok 4 Fast | LMArena Search Arena | 1,163 LMArena Search Arena, grok-4-fast-search (menlo), #1 | 1,162 Leaderboard, search | +1 | The lab quotes the September 2025 Search Arena snapshot, while the board uses a later rating with style controls. |
| Qwen3.5-Omni-Plus | Daily-Omni | 84.6% DailyOmni | 84.7% Leaderboard, Omni-Modal Language Models (With Visual and Audio) | Same | |
| Qwen 3.8 Max | GPQA Diamond | 92.6% GPQA Diamond | 92.7% Epoch AI run, xhigh | Same | |
| Qwen3-VL-Embedding-8B | MMEB-V2 | 77.9% MMEB-V2 All, image 80.1, video 66.1, VisDoc 83.3 (8B card table, VisDoc OOD split re-evaluated) | 77.8% Leaderboard | Same | |
| Muse Spark | FORTRESS | 20.3% FORTRESS Average Risk Score (Table 2, Figure 30) | 20.2% Leaderboard | Same | |
| Grok 4 | ARC-AGI-2 | 15.9% ARC-AGI-2 | 16% Leaderboard, thinking | Same | |
| GLM-5.2 | HMMT 2026 | 92.5% HMMT Feb. 2026 | 92.4% Leaderboard, max | Same | |
| Kimi K3 | LMArena (Elo) | 1,486 Text Arena (Elo), rank 8 of 200 (Table 5) | 1,487 Leaderboard, max | −1 | Moonshot quotes Arena's July 23 rating, while the board reports a later rating as votes accumulate. |
| Gemini 3.1 Flash-Lite | LMArena (Elo) | 1,432 Elo 1432 on the Arena.ai leaderboard, quoted in the Gemini 3.1 Flash-Lite launch blog | 1,433 Leaderboard | −1 | |
| Step 3.5 Flash | HMMT 2025 | 98.4% HMMT 2025 (Feb.) | 98.3% Leaderboard | Same | |
| DeepSeek-V3.2 | tau2-bench | 80.3% τ2-Bench (Pass@1) | 80.4% Leaderboard | Same | |
| GPT-5.6 Sol | FrontierMath Tier 4 v2 | 83% FrontierMath Tier 4 (v2) | 82.9% Leaderboard, max; task version 2.0.0, Epoch | Same | |
| Gemini 3.8 Flash Cyber | CyberGym | 86.2% CyberGym Pass@1, vulnerability discovery in C/C++ | 86.3% Leaderboard, Google Antigravity | Same | |
| Gemma 4 31B IT | LMArena (Elo) | 1,451 Arena Text Elo, as of June 19, 2026 (Table 4) | 1,452 Leaderboard | −1 | Google quotes Arena's June 19 rating, while the board reflects a later snapshot with more votes. |
| Claude Fable 5.2 | AutomationBench | 51.4% Business workflows AutomationBench, max effort, default fallbacks (launch table and Table 8.1.A) | 51.5% Leaderboard, max, default fallbacks | Same | |
| Qwen3-Coder-480B-A35B | Multi-SWE-bench mini | 25.8% Multi-SWE-bench mini | 25.8% Leaderboard, self-reported, MopenHands | Same | |
| GPT-6 Astra | ARC-AGI-3 | 99.9% ARC-AGI-3 (responses API harness) | 99.95% Leaderboard, high, Provider Adapter | Same | |
| GPT-Realtime-2 | Audio MC | 48.5% Audio MultiChallenge Instruction Following, gpt-realtime-2 (xhigh) | 48.5% Leaderboard, xhigh, audio output | Same | |
| Claude Sonnet 5.5 | AutomationBench | 44.7% AutomationBench | 44.8% Leaderboard, max, default fallbacks | Same | |
| GPT-6 Astra | ExploitGym | 42.4% ExploitGym v1, intended-exploit success rate, printed chart label (Figure 49) | 42.4% Leaderboard | Same | |
| Qwen3-VL-Embedding-2B | MMEB-V2 | 73.2% MMEB-V2 All, image 75.0, video 61.9, VisDoc 79.2 (2B card table) | 73.3% Leaderboard | Same | |
| Nemotron 3 Nano 30B-A3B Base | MMLU-Pro | 65% MMLU-Pro, 5-shot CoT EM, base model Table 2 | 65.1% Leaderboard | Same | |
| Claude Fable 5.2 | Remote Labor Index | 41.3% Knowledge work Remote Labor Index (RLI), High effort (launch table and Table 8.1.A) | 41.3% Leaderboard | Same | |
| Gemini 4 Carbon | Vals Index v2.2 | 70.4% Vals Index v2.2 | 70.5% Leaderboard | Same | |
| Inkling 2 Small | Vibe Code Bench | 81.6% Vibe Code Bench v1.1 | 81.5% Leaderboard, OpenHands | Same | |
| GPT-5.2 Pro | ARC-AGI-2 | 54.2% ARC-AGI-2 (Verified), high | 54.2% Leaderboard, high | Same | |
| Qwen1.5-72B | CMMLU | 83.5% CMMLU | 83.5% Leaderboard, Five-shot | Same | |
| Inkling 2 Small | Vals Finance Agent v2.1 | 67.5% Finance Agent v2.1, 67.5% | 67.5% Leaderboard | Same | |
| Gemini 3.7 Flash | AutomationBench | 30.4% AutomationBench (Private set) | 30.4% Leaderboard, high | Same | |
| Gemini 3 Pro | MathArena (Apex, IMO, USAMO) | 23.4% MathArena Apex | 23.4% Leaderboard | Same | |
| Claude Opus 4.5 | ARC-AGI-2 | 37.6% Novel problem solving ARC-AGI-2 (Verified) | 37.6% Leaderboard, thinking, 64k | Same | |
| Inkling-Small | ARC-AGI-2 | 40.1% ARC-AGI-2 | 40.1% Leaderboard, xhigh | Same | |
| Claude Opus 5 | ARC-AGI-3 | 30.2% Novel problem-solving ARC-AGI-3 (high) | 30.2% Leaderboard, high, standard | Same | |
| TML-Interaction-Small | Audio MC | 43.4% Audio MultiChallenge APR, audio | 43.4% Leaderboard, audio output | Same | |
| Inkling | Audio MC | 56.6% Audio MC | 56.6% Leaderboard, thinking, text output | Same | |
| Grok 4.7 | BioSecBench-Surveillance | 48% BioSecBench Surveillance, endpoint pass rate, xhigh, Grok Build harness (7.1 table) | 48% Leaderboard, Pi | Same | |
| Gemini 4 Argon | FrontierSWE | 55% FrontierSWE v2 | 55% Leaderboard, mean@5; Cache hit rate is much lower due to a non-production setting., proximus | Same | |
| Phi-4 | GPQA Diamond | 56.1% GPQA (simple-evals) | 56.1% Epoch AI run | Same | |
| Claude Opus 4.8 | Harvey LAB (Legal Agent Benchmark) | 9.62% Legal Agent Benchmark (Harvey LAB), all-pass rate on 1,235 public problems, internal reimplementation, max effort, five trials, mean criterion pass rate 89.01% (8.13.3) | 9.58% Leaderboard | Same | |
| Gemini 2.5 Pro Jun 2025 | Humanity's Last Exam | 21.6% Humanity's Last Exam | 21.6% Leaderboard | Same | |
| GPT-5.5 | Vals Finance Agent | 60% FinanceAgent v1.1 | 60% Leaderboard | Same | |
| Gemini 3.5 Flash | Vals Finance Agent v2 | 57.9% Finance Agent v2 | 57.9% Leaderboard | Same | |
| Gemini 3.8 Flash | Vals Finance Agent v2 | 61.4% Vals Finance Agent v2 | 61.4% Leaderboard | Same | |
| Muse Wonder Full | Vals Finance Agent v2 | 59.1% Vals Finance Agent V2 | 59.1% Leaderboard | Same | |
| Muse Wonder | Vals Finance Agent v2 | 56.6% Vals Finance Agent V2 | 56.6% Leaderboard | Same | |
| Kimi K3 | CorpFin v2 | 71.6% CorpFin v2 | 71.6% Leaderboard | Same | |
| Claude Fable 5.2 | FrontierSWE | 69.9% Agentic coding FrontierSWE v2, max effort (launch table and Table 8.1.A) | 69.9% Leaderboard, mean@5, proximus | Same | |
| Mistral Small 3.1 | MMLU-Pro | 66.8% MMLU Pro (5-shot CoT) | 66.8% Leaderboard | Same | |
| Kimi K2.6 | OSWorld-Verified | 73.1% OSWorld-Verified | 73.1% Leaderboard, 100 steps | Same | |
| Inkling 2 Small | CyberBench v1.1 (Vals) | 72.7% CyberBench v1.1 | 72.7% Leaderboard | Same | |
| Gemma 4 26B A4B | LMArena (Elo) | 1,438 Arena Text Elo, as of June 19, 2026 (Table 4) | 1,437 Leaderboard | +1 | The lab quotes a rounded June 19 Arena rating, while the board uses the November 8 rating. |
| Qwen 3.8 Max | Agents' Last Exam | 27% Agents' Last Exam (Pass / Score) 27.0 / 52.4 | 27% Leaderboard, xhigh, claude_code | Same | |
| GPT-5.2 | ARC-AGI | 86.2% ARC-AGI-1 (Verified) Abstract reasoning | 86.2% Leaderboard, xhigh | Same | |
| GPT-5.4 | ARC-AGI | 93.7% ARC-AGI-1 (Verified) | 93.7% Leaderboard, xhigh | Same | |
| GPT-5.4 Pro | ARC-AGI-2 | 83.3% ARC-AGI-2 (Verified) | 83.3% Leaderboard, xhigh | Same | |
| Inkling-Small | Audio MC | 54.9% Audio MC | 54.9% Leaderboard, text output | Same | |
| Grok 4.7 | BioSecBench-Function | 43.3% BioSecBench Function, endpoint pass rate, xhigh, Grok Build harness (7.1 table) | 43.3% Leaderboard, Pi | Same | |
| GPT-5.6 Sol | DeepSWE | 72.7% DeepSWE v1.1 (Sol, max) | 72.7% Leaderboard, max, mini-swe-agent | Same | |
| Claude Opus 5.5 | FrontierSWE | 62.3% FrontierSWE v2, mean of five trials per task, Proximal harness at max effort (8.7) | 62.3% Leaderboard, mean@5, proximus | Same | |
| GLM-5.3 | FrontierSWE v1 | 78.1% FrontierSWE | 78.1% Leaderboard, mean, Claude Code | Same | |
| Inkling 2 Small | Legal Research Bench | 46.6% Legal Research Bench, 46.6% | 46.6% Leaderboard | Same | |
| Inkling 2 Small | SWE-Bench Pro V2 Hard | 86.3% SWEBench Pro v2 (Hard) | 86.3% Leaderboard | Same | |
| Claude Sonnet 4.5 | tau2-bench | 84.7% Mean of Agentic tool use τ2-bench Retail / Agentic tool use τ2-bench Airline / Agentic tool use τ2-bench Telecom | 84.7% Leaderboard | Same | |
| Gemini 3 Pro | tau2-bench | 85.4% τ2-bench | 85.4% Leaderboard | Same | |
| Claude Sonnet 4.6 | Vals Finance Agent | 63.3% Agentic financial analysis Finance Agent v1.1 | 63.3% Leaderboard | Same | |
| Claude Opus 4.7 | Vals Finance Agent | 64.4% Agentic financial analysis Finance Agent v1.1 | 64.4% Leaderboard | Same | |
| Inkling 2 Small | Vals Finance Index | 61.5% Vals Finance Index | 61.5% Leaderboard | Same | |
| Inkling 2 Small | SAGE v1.1 (Vals) | 88.6% SAGE v1.1, 88.6% | 88.6% Leaderboard | Same | |
| Grok 4.6 | Harvey LAB (Legal Agent Benchmark) | 15.8% Harvey LAB (Vals) | 15.8% Leaderboard | Same | |
| Inkling 2 Small | Harvey LAB v1.1 (HLAB-Vals-1.1) | 21.7% Harvey LAB v1.1, 21.7% | 21.7% Leaderboard | Same | |
| Claude Haiku 5.5 | FrontierSWE | 43.8% FrontierSWE v2, max effort, Proximal harness, five trials per task (8.6) | 43.8% Leaderboard, mean@5, proximus | Same | |
| GPT-5.6 Terra | DeepSWE | 69.6% DeepSWE v1.1 | 69.6% Leaderboard, max, mini-swe-agent | Same | |
| GPT-6 Astra | DeepSWE | 74.1% DeepSWE v1.1 | 74.1% Leaderboard, xhigh, mini-swe-agent | Same | |
| Qwen2-72B | MMLU-Pro | 64.4% MMLU-Pro | 64.4% Leaderboard | Same | |
| Kimi-Audio-7B-Instruct | VoiceBench | 76.9% VoiceBench Avg (AlpacaEval 4.46, CommonEval 3.97, SD-QA 63.12, MMSU 62.17, OpenBookQA 83.52, IFEval 61.10, AdvBench 100.00) | 76.9% Leaderboard | Same | |
| Tencent Hy4 | Agents' Last Exam v1.1 | 41% Agents' Last Exam v1.1* | 41% Leaderboard, high, Claude Code | Same | |
| Muse Spark 1.1 | DeepSWE | 53.3% DeepSWE 1.1 (Long-horizon agentic coding) | 53.3% Leaderboard, xhigh, mini-swe-agent | Same | |
| Claude Opus 5.5 | ExploitGym | 34.5% ExploitGym, 300 of 869 instances exploited with the intended vulnerability at the 6-hour budget (289 at 2 hours), mitigations disabled, counts converted to % (3.3.4, Figure 3.3.4.A) | 34.5% Leaderboard | Same | |
| Gemini 4 Argon | Harvey LAB (Legal Agent Benchmark) | 19.6% Harvey's Legal Agent Benchmark | 19.6% Leaderboard | Same | |
| Qwen3-Coder-480B-A35B | Spider 2.0 | 31.1% Spider2 | 31.1% Leaderboard, Spider-Agent | Same | |
| Claude Opus 4.8 | Vals Finance Agent v2 | 53.9% Agentic financial analysis Finance Agent v2 | 53.9% Leaderboard | Same | |
| Inkling 2 Small | Vals Index v2.2 | 56.1% Vals Index (v2.2) | 56.1% Leaderboard | Same | |
| Claude Opus 5 | ExploitGym | 22% ExploitGym, 191/869 instances exploited with the intended vulnerability at the 6-hour budget (171 at 2 hours), counts printed on chart converted to %, mitigations off (3.3.5, Figure 3.3.5.A) | 22% Leaderboard | Same | |
| Gemini 2.5 Flash Apr 2025 | Humanity's Last Exam | 12.1% Humanity's Last Exam (no tools) | 12.1% Leaderboard | Same | |
| Gemini 3 Deep Think | ARC-AGI-2 | 84.6% ARC-AGI-2 (verified by the ARC Prize Foundation) | 84.6% Leaderboard | Same | |
| Gemini 3.1 Pro | ARC-AGI-2 | 77.1% ARC-AGI-2 (ARC Prize Verified) | 77.1% Leaderboard | Same | |
| Gemini 3.5 Flash | ARC-AGI-2 | 72.1% ARC-AGI-2 | 72.1% Leaderboard, high | Same | |
| Claude Opus 5 | ARC-AGI-2 | 90.4% ARC-AGI-2 | 90.4% Leaderboard, max | Same | |
| Gemini 4 Carbon | AutomationBench | 53.9% AutomationBench (Zapier) | 53.9% Leaderboard, high | Same | |
| LongCat-2.0 | FORTE | 73.2% FORTE | 73.2% Leaderboard, OpenClaw | Same | |
| LongCat-Flash-Chat | MMLU-Pro | 82.7% MMLU-Pro(acc) | 82.7% Leaderboard | Same | |
| Grok Voice Think Fast 1.0 | τ-Voice | 67.3% τ-voice Leaderboard, Overall | 67.3% Leaderboard, enabled | Same | |
| Kimi-VL-A3B-Thinking-2506 | Video-MMMU | 65.2% VideoMMMU (Pass@1) | 65.2% Leaderboard | Same | |
| Qwen2.5-VL-72B | Video-MMMU | 60.2% Video-MMMU (Table 8) | 60.2% Leaderboard | Same | |
| GPT-5.6 Luna | DeepSWE | 67.2% DeepSWE v1.1 | 67.2% Leaderboard, max, mini-swe-agent | Same | |
| Kimi K3.1 Pro | GPQA Diamond | 94.2% GPQA-Diamond | 94.2% Epoch AI run, Together, max | Same | |
| Qwen2.5-14B | MMLU-Pro | 63.7% MMLU-Pro, Qwen2.5-14B-Instruct (Table 7) | 63.7% Leaderboard | Same | |
| MiniMax-M3 | OSWorld-Verified | 75.2% OSWorld-Verified | 75.2% Leaderboard, 100 steps | Same | |
| DeepSeek V4.1 Flash | SimpleQA Verified | 42.3% SimpleQA-Verified (EM) | 42.3% Leaderboard | Same | |
| Inkling 2 Small | Vals Legal Index | 73.9% Vals Legal Index | 73.9% Leaderboard | Same | |
| Nemotron 3 Nano Omni 30B-A3B | VoiceBench | 89.4% VoiceBench Avg, reasoning on (Table 8). Nine spoken subsets from 71.4 (SD-QA) to 100 (AdvBench) | 89.4% Leaderboard | Same | |
| Kimi K3 | Agents' Last Exam | 28.3% Agents' Last Exam | 28.3% Leaderboard, max, kimi_code | Same | |
| Gemini 3.8 Flash | Terminal-Bench 4.0 | 19.1% Terminal-bench 4.0 | 19.1% Leaderboard, high, mini-SWE-agent | Same | |
| Qwen 3.8 27B | Agents' Last Exam | 20.4% Frontier agentic tasks Agents' Last Exam Pass@1 20.4 Score 42.9 | 20.4% Leaderboard, max, claude_code | Same | |
| MiniMax-M3.1-Flash | Agents' Last Exam | 29.6% Agents’ Last Exam | 29.6% Leaderboard, high, claude_code | Same | |
| Gemini 3 Pro | ARC-AGI-2 | 31.1% ARC-AGI-2 (ARC Prize Verified) | 31.1% Leaderboard | Same | |
| GPT-5.2 | ARC-AGI-2 | 52.9% ARC-AGI-2 (Verified) Abstract reasoning | 52.9% Leaderboard, xhigh | Same | |
| Gemini 3 Flash | ARC-AGI-2 | 33.6% ARC-AGI-2 (ARC Prize Verified) | 33.6% Leaderboard, high | Same | |
| Gemini 4 Argon | AutomationBench | 51.3% AutomationBench (Score) | 51.3% Leaderboard, high | Same | |
| GLM-5.3-Flash | DeepSWE | 63.4% DeepSWE (v1.1) | 63.4% Leaderboard, max, mini-swe-agent | Same | |
| Claude Sonnet 5.5 | FrontierSWE | 61.9% FrontierSWE v2, mean of five trials, Proximal harness at max effort (8.7) | 61.9% Leaderboard, mean@5, proximus | Same | |
| GLM-4.5V | MotionBench | 62.4% MotionBench | 62.4% Leaderboard, frames: 2fps | Same | |
| GLM-5.2 | PostTrainBench | 34.3% PostTrainBench | 34.3% Leaderboard, max, Claude Code | Same | |
| UI-TARS-1.5 | ScreenSpot-Pro | 61.6% ScreenSpotPro | 61.6% Leaderboard | Same | |
| Seed1.5-VL | ScreenSpot-Pro | 60.9% ScreenSpot-Pro | 60.9% Leaderboard | Same | |
| Muse Spark 1.1 | Vals Finance Agent v2 | 57.2% Finance Agent v2 (Agentic financial anaysis) | 57.2% Leaderboard | Same | |
| Gemini 4 Argon | Vibe Code Bench | 91.9% Vibe Code Bench | 91.9% Leaderboard, OpenHands | Same | |
| Gemini 3 Flash | Vending-Bench 2 | $3,635 Vending-Bench 2 (Net worth (mean)) | $3,635 Leaderboard | Same | |
| Gemini 3.7 Flash | Code Arena | 1,588 Code Arena (Web development, Elo) | 1,588 Leaderboard, high | Same | Google quotes an August Arena rating as an integer, while the board supplies a later rating with decimal precision. |
| Claude Opus 4.7 | Vending-Bench 2 | $10,937 Vending-Bench 2 final balance at max effort. $7,971 at high effort (8.10.4) | $10,937 Leaderboard | Same | |
| Gemini 4 Carbon | Vending-Bench 2 | $16,484 Vending-Bench 2 (Bank balance $) | $16,484 Leaderboard | Same | |
| Seed2.1 Pro | Agent Startup Bench | 68.8% Agent Startup Bench | 68.8% Leaderboard | Same | |
| Qwen-AgentWorld-35B-A3B | AgentWorldBench | 56.4 AgentWorldBench Overall (five-dimension rubric mean, 0 to 100) | 56.4 Leaderboard | Same | |
| DeepSeek-V2.5 Sep 2024 | Aider-Edit | 72.2% Aider | 72.2% Leaderboard, aider, diff edits | Same | |
| o3 | Aider Polyglot | 81.3% Aider Polyglot Code Editing, o3-high (whole) | 81.3% Leaderboard, high, aider, diff edits | Same | |
| GPT-5 | Aider Polyglot | 88% Aider Polyglot Multi-language code editing | 88% Leaderboard, high, aider, diff edits | Same | |
| GPT-5.2 | AIME 2025 | 100% AIME 2025 (no tools) Competition math | 100% Leaderboard, high | Same | |
| Seed1.5-VL | AndroidWorld | 62.1% Android World | 62.1% Leaderboard | Same | |
| Gemini 2.5 Computer Use | AndroidWorld | 69.7% AndroidWorld, measured by Google DeepMind | 69.7% Leaderboard | Same | |
 sonar | Answer Factuality (Perplexity) | 85.1% Factuality | 85.1% Leaderboard | Same | |
| GPT-4.1 mini | Internal API instruction following (OpenAI) | 45.1% Internal API instruction following (hard) | 45.1% Leaderboard | Same | |
| GPT-4.1 nano | Internal API instruction following (OpenAI) | 31.6% Internal API instruction following (hard) | 31.6% Leaderboard | Same | |
| GPT-5.2 Pro | ARC-AGI | 90.5% ARC-AGI-1 (Verified) | 90.5% Leaderboard, xhigh | Same | |
| GPT-5.4 Pro | ARC-AGI | 94.5% ARC-AGI-1 (Verified) | 94.5% Leaderboard, xhigh | Same | |
| GPT-5.5 | ARC-AGI | 95% ARC-AGI-1 (Verified) | 95% Leaderboard, xhigh | Same | |
| Claude Opus 5 | ARC-AGI | 97.5% ARC-AGI-1 | 97.5% Leaderboard, high | Same | |
| Inkling-Small | ARC-AGI | 84% ARC-AGI-1 | 84% Leaderboard, xhigh | Same | |
| Claude Fable 5.1 | ARC-AGI | 97.5% ARC-AGI-1 | 97.5% Leaderboard, max | Same | |
| Claude Opus 4.5 | ARC-AGI | 80% ARC-AGI-1, semi-private set, 64k thinking, reported by ARC Prize Foundation (2.10, Figure 2.10.A) | 80% Leaderboard, thinking, 64k | Same | |
| Claude Opus 4.6 | ARC-AGI | 94% ARC-AGI-1, 120k thinking tokens, high effort, ARC Prize private set, reported by ARC Prize Foundation (2.9, Figure 2.9) | 94% Leaderboard, 120k, high | Same | |
| Claude Sonnet 4.6 | ARC-AGI | 86.5% ARC-AGI-1, 120k thinking tokens, high effort, ARC Prize private set (2.7, Figure 2.7.A) | 86.5% Leaderboard, high | Same | |
| Claude Opus 4.7 | ARC-AGI-2 | 75.8% ARC-AGI-2 | 75.8% Leaderboard, max | Same | |
| GPT-5.5 | ARC-AGI-2 | 85% ARC-AGI-2 (Verified) | 85% Leaderboard, xhigh | Same | |
| Claude Fable 5.1 | ARC-AGI-2 | 90% ARC-AGI-2 | 90% Leaderboard, max | Same | |
| GPT-5.6 Sol | ARC-AGI-3 | 7.78% ARC-AGI-3 | 7.78% Leaderboard, max, standard | Same | |
| GPT-5.6 Terra | ARC-AGI-3 | 0.80% ARC-AGI-3 | 0.80% Leaderboard, max, standard | Same | |
| GPT-5.6 Luna | ARC-AGI-3 | 0.18% ARC-AGI-3 | 0.18% Leaderboard, max, standard | Same | |
| GPT-6 Astra | AutomationBench | 41.4% AutomationBench | 41.4% Leaderboard, max | Same | |
| GPT-6 Sol | AutomationBench | 33.2% AutomationBench 1.0.6 (GPT-6 Sol xhigh) | 33.2% Leaderboard, xhigh | Same | |
| GPT-6 Luna | AutomationBench | 20.7% AutomationBench 1.0.6 (GPT-6 Luna max) | 20.7% Leaderboard, max | Same | |
| Seed2.0 Pro | BabyVision | 60.6% BabyVision | 60.6% Leaderboard, high | Same | |
| Qwen3.7-Plus | BabyVision | 70.4% BabyVision 70.4 / 64.7 (with CI / without CI) | 70.4% Leaderboard, tools | Same | |
| Seed2.1 Pro | BabyVision | 73.7% BabyVision | 73.7% Leaderboard | Same | |
| Muse Spark 1.1 | BabyVision | 76.3% BabyVision (Visual reasoning) | 76.3% Leaderboard, tools | Same | |
| Kimi K3 | BabyVision | 85.7% BabyVision w/ python | 85.7% Leaderboard, Python tools | Same | |
| Qwen 3.8 Max | BabyVision | 91.3% BabyVision (without CI / with CI) 82.0 / 91.3 | 91.3% Leaderboard, tools | Same | |
| Kimi K2.5 | BabyVision | 36.5% BabyVision (Table 4) | 36.5% Leaderboard | Same | |
| Gemma 3 12B | BBEH micro average | 16.3% BBEH, IT, 0-shot (Table 18) | 16.3% Leaderboard | Same | |
| Gemma 3 4B | BBEH micro average | 11% BBEH, IT, 0-shot (Table 18) | 11% Leaderboard | Same | |
| Gemini 3.5 Flash Cyber | Big Sleep Evaluation (Google) | 72% Success Rate on Big Sleep Evaluation (pass@1) | 72% Leaderboard | Same | |
| Inkling 2 Small | BioMysteryBench | 70% BioMysteryBench | 70% Leaderboard, Vals AI harness, v11 full set | Same | |
| Grok 4.7 | BioSecBench-Refusal | 62.4% BioSecBench Refusal, xhigh, Grok Build harness (7.1 table) | 62.4% Leaderboard, Pi | Same | |
| Gemini 3.5 Flash | Blueprint-Bench 2 | 33.6% Blueprint-Bench 2 (Normalized score) | 33.6% Leaderboard | Same | |
| Claude Fable 5 | Blueprint-Bench 2 | 38.6% Spatial reasoning Blueprint-Bench 2 | 38.6% Leaderboard | Same | |
| Gemini 4 Carbon | Blueprint-Bench 2 | 58.6% Blueprint-Bench 2 (Similarity score) | 58.6% Leaderboard | Same | |
| GLM-5 | CC-Bench-V2 Backend | 25.8% CC-Bench-V2 Backend Engineering, Pass@1 (Table 8) | 25.8% Leaderboard | Same | |
| GLM-5 | CC-Bench-V2 Multi-Step Chained Tasks | 52.3% CC-Bench-V2 Long-horizon Chained Tasks, Pass@1 (Table 8) | 52.3% Leaderboard | Same | |
| GLM-5 | CC-Bench-V2 Frontend | 74.8% CC-Bench-V2 Frontend, End-to-End Correctness (Figure 4). Build Success Rate 98.0; per-stack ISR/CSR in Table 8 | 74.8% Leaderboard | Same | |
| GLM-5 | CC-Bench-V2 Large Repo Exploration | 65.6% CC-Bench-V2 Long-horizon Repo Exploration, Pass@1 (Table 8) | 65.6% Leaderboard | Same | |
| Step 3.5 Flash | CF-Div2-Stepfun | 86.1% CF-Div2-Stepfun-cpp, avg@8 (Tables 5 and 15). PaCoRe 93.3. Python 81.5, Java 77.1, estimated Codeforces C++ pass@8 rating 2489 (Table 15) | 86.1% Leaderboard, C++; avg@8 | Same | |
| Gemini 4 Argon | Chartography | 71.6% Chartography | 71.6% Leaderboard, high | Same | |
| GPT-4.1 | CharXiv | 56.7% CharXiv-R | 56.7% Leaderboard | Same | |
| GPT-4.1 mini | CharXiv | 56.8% CharXiv-R 56.8 (CharXiv-D 88.4) | 56.8% Leaderboard | Same | |
| GPT-4.1 nano | CharXiv | 40.5% CharXiv-R 40.5 (CharXiv-D 73.9) | 40.5% Leaderboard | Same | |
| o3 | CharXiv | 78.6% CharXiv-Reasoning Scientific Figure Reasoning | 78.6% Leaderboard, high | Same | |
| o4-mini | CharXiv | 72% CharXiv-Reasoning | 72% Leaderboard, high | Same | |
| Qwen2.5-VL-72B | CharXiv | 49.7% CharXiv RQ (Table 5) | 49.7% Leaderboard | Same | |
| Qwen2.5-VL-72B | CharXiv (DQ) | 87.4% CharXiv DQ (Table 5) | 87.4% Leaderboard, validation; descriptive questions | Same | |
| DeepSeek LLM 67B | ChineseQA | 85.1% ChineseQA (in-house) | 85.1% Leaderboard, 5-shot | Same | |
| Gemini 3.5 Flash Cyber | Chrome Production Commit Scanning (Google) | 72% Success Rate on Chrome Production Commit Scanning Pipeline (pass@1) | 72% Leaderboard, pass@1 | Same | |
| Tencent Hy3 preview | CL-bench | 22.8% CL-bench | 22.8% Leaderboard | Same | |
| Tencent Hy3 preview | CL-bench Life | 15.7% CL-bench Life | 15.7% Leaderboard, high | Same | |
| Kimi K2.6 | Claw-Eval Pass^3 | 62.3% Claw Eval (pass^3) | 62.3% Leaderboard | Same | |
| MiMo-V2.5 | Claw-Eval Pass^3 | 62.3% Claw-Eval Text | 62.3% Leaderboard | Same | |
| MiMo-V2.5-Pro | Claw-Eval Pass^3 | 63.8% Claw-Eval (pass^3) | 63.8% Leaderboard | Same | |
| DeepSeek-V3 | CNMO 2024 | 43.2% CNMO 2024 (Pass@1) | 43.2% Leaderboard | Same | |
| Qwen-14B | Code Interpreter Benchmark Math | 58.4% Code Interpreter benchmark, Accuracy of Code Execution Results (Math) | 58.4% Leaderboard, version 20231206 | Same | |
| DeepSeek-Prover-V2-671B | CombiBench | 10% CombiBench with-solution setting, CoT, Pass@16, 10 of 100 solved (Table 5). Version 1 reported 12 | 10% Leaderboard, without solution, pass@16 | Same | |
| Hunyuan-A13B-Instruct | ComplexNLU (Tencent) | 61.2% ComplexNLU | 61.2% Leaderboard | Same | |
| Qwen 3.8 Max | CoWorkBench | 74.8% CoWorkBench | 74.8% Leaderboard | Same | |
| Seed2.1 Pro | CreativeWork | 42.5% CreativeWork | 42.5% Leaderboard | Same | |
| Grok 4.7 | CursorBench 4.0 | 46.3% CursorBench 4.0 (Software engineering) | 46.3% Leaderboard, xhigh, Cursor | Same | |
| Claude Opus 5.5 | CursorBench 4.0 | 57.8% Agentic coding CursorBench 4.0 | 57.8% Leaderboard, max, Cursor | Same | |
| Claude Sonnet 5.5 | CursorBench 4.0 | 55.5% Agentic coding CursorBench 4.0 | 55.5% Leaderboard, max, Cursor | Same | |
| Claude Fable 5.2 | CursorBench 4.0 | 60% CursorBench 4.0, max effort, independently run by Cursor. Additional prompt and harness improvements may prevent comparisons with earlier system cards (Section 8.8) | 60% Leaderboard, max, Cursor | Same | |
| Gemini 4 Argon | CWE-bench | 68% CWE-bench v1 (Cybersecurity row of headline table) | 68% Leaderboard, Antigravity | Same | |
| Gemini 4 Carbon | CWE-bench | 71% CWE-bench | 71% Leaderboard, Antigravity | Same | |
| Grok 4 | Cybench | 43% CyBench, unguided success rate 0.43, Grok 4 API, Inspect harness (Table 3) | 43% Leaderboard | Same | |
| Grok 4 Fast | Cybench | 30% CyBench, unguided success rate 30.0 (Table 3) | 30% Leaderboard | Same | |
| Grok 4.1 | Cybench | 39% CyBench, unguided success rate 0.39, Grok 4.1 Thinking (Table 4) | 39% Leaderboard | Same | |
| Muse Spark | Cybench | 65.4% CyBench pass@1, all 40 challenges (Table 1, Table 7). pass@10 79.0, pass@30 82.2 | 65.4% Leaderboard | Same | |
| Kimi K2.5 | CyberGym | 41.3% CyberGym | 41.3% Leaderboard, Kimi Agent | Same | |
| GLM-5 | CyberGym | 43.2% CyberGym | 43.2% Leaderboard, Claude Code | Same | |
| GPT-5.5 | CyberGym | 81.8% CyberGym | 81.8% Leaderboard, OpenAI Agent | Same | |
| Claude Sonnet 4.5 | CyberGym | 28.9% CyberGym vulnerability reproduction, 1 trial, $2 cost constraint per trial, probability of success 0.289. 30 trials 0.667. New vulnerability discovery 0.050 at 1 trial and 0.334 at 30 trials (Figures 5.2.1.A to 5.2.1.C) | 28.9% Leaderboard, Anthropic Agent | Same | |
| Claude Opus 4.5 | CyberGym | 50.6% CyberGym, pass@1 over 1,505 tasks, avg of 5 replicas, no thinking (2.14) | 50.6% Leaderboard, Anthropic Agent | Same | |
| Claude Sonnet 4.6 | CyberGym | 65.2% CyberGym targeted vulnerability reproduction, pass@1 over 1,507 tasks, no thinking with think tool (2.15) | 65.2% Leaderboard, Anthropic Agent | Same | |
| Muse Spark | CyberGym | 43.5% CyberGym pass@1 (Table 1, 2.2.2.2 text) | 43.5% Leaderboard, Meta Agent | Same | |
| Grok 4.6 | CyberGym | 79.7% CyberGym, mean reproduced, high, unrestricted, Grok Build harness (7.1) | 79.7% Leaderboard, Grok Build | Same | |
| Nemotron 3 Nano Omni 30B-A3B | Daily-Omni | 74.5% Daily Omni | 74.5% Leaderboard, Omni-Modal Language Models (With Visual and Audio) | Same | |
| Qwen3.8-Omni-Flash | Daily-Omni | 85.1% DailyOmni Audio-Visual Understanding | 85.1% Leaderboard, Omni-Modal Language Models (With Visual and Audio) | Same | |
| Inkling 2 Small | DAYJOB: Finance | 14.3% DAYJOB (Finance) | 14.3% Leaderboard, xhigh | Same | |
| Seed2.1 Pro | Doubao Multi-Turn Bench | 52.5% Doubao Multi-Turn Bench | 52.5% Leaderboard | Same | |
| DeepSeek-V2.5 Sep 2024 | DS-Arena-Code | 63.1% DS-Arena-Code (in-house) | 63.1% Leaderboard | Same | |
| DeepSeek-V2.5 Sep 2024 | DS-FIM-Eval | 78.3% DS-FIM-Eval (in-house) | 78.3% Leaderboard | Same | |
| Tencent Hy4 preview | E-Bench-Code (Tencent) | 79% E-Bench-Code (Internal) | 79% Leaderboard, highest available reasoning | Same | |
| Tencent Hy4 preview | E-Bench (Tencent) | 77.1% E-Bench (Internal) | 77.1% Leaderboard, highest available reasoning | Same | |
| Cohere Command A | Cohere enterprise human evaluation | 51.7% Head-to-head human evaluation win rate vs GPT-4o (Nov), average of six enterprise task groups (tie 15.3) | 51.7% Leaderboard | Same | |
| Inkling 2 Small | EnterpriseBench: CoreCraft | 71.8% EnterpriseBench-CoreCraft | 71.8% Leaderboard, xhigh | Same | |
| GPT-6.1 Sol | ExploitGym | 35.1% ExploitGym, intended-vulnerability success rate per attempt (9.1.2.2) | 35.1% Leaderboard | Same | |
| Gemini 2.5 Pro Jun 2025 | FACTS Grounding | 87.8% FACTS Grounding | 87.8% Leaderboard | Same | |
| Muse Wonder Full | FocusBench (Meta) | 54.2% FocusBench (chart label) | 54.2% Leaderboard, max | Same | |
| Muse Wonder | FocusBench (Meta) | 44.9% FocusBench (chart label) | 44.9% Leaderboard, max | Same | |
| DeepSeek-Prover-V2-671B | FormalMATH | 28.3% FormalMATH-All Pass@32, CoT (Table 6). FormalMATH-Lite Pass@32 56.00, Pass@3200 61.88 | 28.3% Leaderboard, sampling budget 32 | Same | |
| SWE-2 Flash | FrontierCode 2.0 | 24% FrontierCode 2.0 | 24% Leaderboard, max, Devin | Same | |
| GPT-5.4 | FrontierMath | 47.6% FrontierMath Tier 1-3 (GPT-5.4) | 47.6% Leaderboard, xhigh; task version 1.1.5, Epoch | Same | |
| GPT-5.4 Pro | FrontierMath | 50% FrontierMath Tier 1-3 | 50% Leaderboard, xhigh; task version 1.1.5, Epoch | Same | |
| GPT-5.5 Pro | FrontierMath | 52.4% FrontierMath Tier 1-3 | 52.4% Epoch AI run, high | Same | |
| GPT-5.4 | FrontierMath Tier 4 | 27.1% FrontierMath Tier 4 (GPT-5.4) | 27.1% Epoch AI run, xhigh | Same | |
| GPT-5.5 Pro | FrontierMath Tier 4 | 39.6% FrontierMath Tier 4 | 39.6% Epoch AI run, xhigh | Same | |
| Gemini 4 Carbon | FrontierSWE | 61.2% FrontierSWE 2 | 61.2% Leaderboard, mean@5, proximus | Same | |
| MiniMax-M2.5 | GDPval-MM | 59% GDPval-MM | 59% Leaderboard | Same | |
| Llama 3.1-405B | GMAT Quantitative | 96% GMAT Quant., accuracy (Table 17) | 96% Leaderboard | Same | |
| Llama 3.1-70B | GMAT Quantitative | 84% GMAT Quant., accuracy (Table 17) | 84% Leaderboard | Same | |
| Llama 3.1-8B | GMAT Quantitative | 56% GMAT Quant., accuracy (Table 17) | 56% Leaderboard | Same | |
| Kimi K2.5 | GPQA Diamond | 87.6% GPQA-Diamond | 87.6% Epoch AI run, Fireworks | Same | |
| Gemini 3.8 Flash | Harvey LAB (Legal Agent Benchmark) | 10% Harvey's Legal Agent Benchmark (All pass rate) | 10% Leaderboard | Same | |
| DeepSeek-V3.2 | HMMT 2025 | 92.5% HMMT Feb 2025 (Pass@1) | 92.5% Leaderboard, thinking | Same | |
| Gemini Robotics ER 2 | Human proximity (Google DeepMind robotics) | 93% Human proximity (1m) | 93% Leaderboard | Same | |
| Inkling 2 Small | Humanity's Sixth Sense | 33.3% HSS | 33.3% Leaderboard | Same | |
| Grok-1 | Hungarian National High-School Exam | 59% Hungarian national high school finals in mathematics (1-shot, human-graded) | 59% Leaderboard | Same | |
| Seed2.1 Pro | Image2FloorPlan | 48.0 Image2FloorPlan (Inhouse), Avg Score | 48.0 Leaderboard | Same | |
| Gemini Robotics ER 2 | Instrument reading (Google DeepMind) | 65.7% Generalized instrument reading | 65.7% Leaderboard | Same | |
| Muse Spark 1.1 | JobBench | 54.7% JobBench (Professional tool use) | 54.7% Leaderboard, OpenCode | Same | |
| Kimi K3 | JobBench | 54.3% JobBench | 54.3% Leaderboard, OpenCode | Same | |
| Kimi-Audio-7B-Instruct | Kimi-Audio speech conversation evaluation | 3.90 Speech conversation, human ratings on a 1 to 5 scale, Avg (Table 7). Speed Control 4.30, Accent Control 3.45, Emotion Control 4.27, Empathy 3.39, Style Control 4.09 | 3.90 Leaderboard | Same | |
| Kimi K2.7 Code | Kimi Claw 24/7 Bench | 46.9% Kimi Claw 24/7 Bench | 46.9% Leaderboard, average pass rate over 610 evaluation points; mean of 3 runs, OpenClaw | Same | |
| Kimi K3.1 Pro | Kimi Code Bench 3.0 Long-horizon | 61.2% Kimi Code Bench 3.0 Long-horizon (Internal) | 61.2% Leaderboard, max | Same | |
 Solar Pro 3 (March 2026 update) | Ko-Arena-Hard v2 (Upstage) | 78.2% Ko-Arena-hard-v2 | 78.2% Leaderboard | Same | |
| Solar Open 2 | Ko-GDPval | 86.8% Ko-GDPval (in-house) | 86.8% Leaderboard | Same | |
| Solar Pro 4 | Ko-GDPval | 87.3% Ko-GDPval* (in-house) | 87.3% Leaderboard | Same | |
| DeepSeek LLM 67B | LeetCode Weekly Contest | 17.5% LeetCode Weekly Contest 351-372 and Bi-Weekly 108-117 (Jul to Nov 2023), pass@1, held-out (Table 9) | 17.5% Leaderboard | Same | |
| MiniMax-M3 | LiveSQLBench | 40.2% LiveSQLBench | 40.2% Leaderboard, Claude Code | Same | |
| MiniMax-Text-01 | LongBench v2 | 56.5% LongBench v2 (overall, w/ CoT) | 56.5% Leaderboard, CoT | Same | |
| Seed1.5-VL | LVBench | 64.6% LVBench | 64.6% Leaderboard, thinking | Same | |
| GPT-5.6 Sol | Management Consulting Tasks (OpenAI) | 43.2% Management Consulting Tasks (Internal) | 43.2% Leaderboard | Same | |
| GPT-5.6 Terra | Management Consulting Tasks (OpenAI) | 37.2% Management Consulting Tasks (Internal) | 37.2% Leaderboard | Same | |
| GPT-5.6 Luna | Management Consulting Tasks (OpenAI) | 35.4% Management Consulting Tasks (Internal) | 35.4% Leaderboard | Same | |
| Kimi k1.5 | MATH-Vision (MathVision) | 38.6% MathVision-Full (Pass@1), long-CoT | 38.6% Leaderboard | Same | |
| Qwen2.5-VL-72B | MATH-Vision (MathVision) | 38.1% MathVision_FULL | 38.1% Leaderboard | Same | |
| Kimi-VL-A3B-Thinking | MATH-Vision (MathVision) | 36.8% MathVision (full) (Pass@1) | 36.8% Leaderboard | Same | |
| Seed1.5-VL | MATH-Vision (MathVision) | 68.7% MathVision | 68.7% Leaderboard | Same | |
| Kimi-VL-A3B-Thinking-2506 | MATH-Vision (MathVision) | 56.9% MATH-Vision (Pass@1) | 56.9% Leaderboard | Same | |
| Step 3 | MATH-Vision (MathVision) | 64.8% MATH-Vision | 64.8% Leaderboard | Same | |
| GLM-4.5V | MATH-Vision (MathVision) | 65.6% MathVision | 65.6% Leaderboard | Same | |
| InternVL3.5-241B-A28B | MATH-Vision (MathVision) | 63.9% MathVision | 63.9% Leaderboard | Same | |
| Qwen3-VL-235B-A22B | MATH-Vision (MathVision) | 74.6% MathVision | 74.6% Leaderboard, thinking | Same | |
| Seed1.8 | MATH-Vision (MathVision) | 81.3% MathVision | 81.3% Leaderboard | Same | |
| Seed2.0 Pro | MATH-Vision (MathVision) | 88.8% MathVision | 88.8% Leaderboard | Same | |
| Qwen3.5 397B-A17B | MATH-Vision (MathVision) | 88.6% MathVision | 88.6% Leaderboard | Same | |
| Qwen3.5-122B-A10B | MATH-Vision (MathVision) | 86.2% MathVision | 86.2% Leaderboard | Same | |
| Qwen3.5-27B | MATH-Vision (MathVision) | 86% MathVision | 86% Leaderboard | Same | |
| Qwen3.5-35B-A3B | MATH-Vision (MathVision) | 83.9% MathVision | 83.9% Leaderboard | Same | |
| Gemma 4 31B IT | MATH-Vision (MathVision) | 85.6% MATH-Vision | 85.6% Leaderboard | Same | |
| Gemma 4 26B A4B | MATH-Vision (MathVision) | 82.4% MATH-Vision | 82.4% Leaderboard | Same | |
| Gemma 4 E2B | MATH-Vision (MathVision) | 52.4% MATH-Vision | 52.4% Leaderboard | Same | |
| Gemma 4 E4B | MATH-Vision (MathVision) | 59.5% MATH-Vision | 59.5% Leaderboard | Same | |
| Seed2.0 Lite (0428) | MATH-Vision (MathVision) | 89.8% MathVision | 89.8% Leaderboard | Same | |
| GLM-4.1V-9B-Thinking | MATH-Vision (MathVision) | 54.4% MathVision, GLM-4.1V-9B-Thinking thinking (Table 2) | 54.4% Leaderboard | Same | |
| GLM-4.6V | MATH-Vision (MathVision) | 63.5% MathVision, GLM-4.6V thinking (Table 2) | 63.5% Leaderboard | Same | |
| Qwen3-VL-235B-A22B | Math-VR | 66.8% Math-VR (Table 2) | 66.8% Leaderboard, thinking | Same | |
| Gemini 1.0 Ultra | MathVista | 53% MathVista (testmini) | 53% Leaderboard | Same | |
| Gemini 1.5 Pro Feb 2024 | MathVista | 52.1% MathViSTA (testmini), 0-shot | 52.1% Leaderboard | Same | |
| Claude 3 Opus | MathVista | 50.5% MathVista (testmini) CoT | 50.5% Leaderboard | Same | |
| GPT-4o May 2024 | MathVista | 63.8% MathVista (%) (testmini) | 63.8% Leaderboard | Same | |
| Gemini 1.5 Pro May 2024 | MathVista | 63.9% MathViSTA (testmini), 0-shot | 63.9% Leaderboard | Same | |
| Claude 3.5 Sonnet | MathVista | 67.7% MathVista (testmini) | 67.7% Leaderboard | Same | |
| Grok-2 Aug 2024 | MathVista | 69% MathVista (0-shot CoT) | 69% Leaderboard | Same | |
| Kimi k1.5 | MathVista | 74.9% MathVista-Test (Pass@1), long-CoT | 74.9% Leaderboard | Same | |
| Phi-4-multimodal | MathVista | 62.4% MathVista (testmini) | 62.4% Leaderboard | Same | |
| Llama 4 Maverick | MathVista | 73.7% MathVista | 73.7% Leaderboard | Same | |
| Claude 3 Haiku | MathVista | 46.4% MathVista (testmini), 0-shot CoT (Table 3) | 46.4% Leaderboard | Same | |
| Claude 3 Sonnet | MathVista | 47.9% MathVista (testmini), 0-shot CoT (Table 3) | 47.9% Leaderboard | Same | |
| Phi-3.5-vision-instruct | MathVista | 43.9% MathVista (testmini) (Table 5) | 43.9% Leaderboard | Same | |
| GPT-5.5 | MCP Atlas | 75.3% MCP Atlas | 75.3% Leaderboard, xhigh | Same | |
| Gemini 3.5 Flash | MCP Atlas | 83.6% MCP Atlas | 83.6% Leaderboard, high | Same | |
| Claude Opus 4.8 | MCP Atlas | 82.2% MCP-Atlas | 82.2% Leaderboard, max | Same | |
| Muse Spark 1.1 | MCP Atlas | 88.1% MCP Atlas (Scaled tool use) | 88.1% Leaderboard | Same | |
| Inkling | MCP Atlas | 76% MCP Atlas | 76% Leaderboard, xhigh | Same | |
| Claude Fable 5 | MCP Atlas | 83.3% MCP-Atlas pass rate (8.17.5) | 83.3% Leaderboard | Same | |
| Claude Opus 5 | MCP Atlas | 85.8% MCP-Atlas pass rate (mean claim coverage 89.1%) (8.13.2) | 85.8% Leaderboard, xhigh | Same | |
| MiMo-V2.6 Pro | MiMo Code Bench | 63.2% MiMo Code Bench | 63.2% Leaderboard | Same | |
| MiMo-V2.5 | MiMo Coding Bench | 71.8% MiMo Coding Bench | 71.8% Leaderboard | Same | |
| MiMo-V2.5-Pro | MiMo Coding Bench | 73.7% MiMo Coding Bench | 73.7% Leaderboard | Same | |
| MiMo-V2.6 Pro | MiMo Visual Coding | 72.3% MiMo Visual Coding | 72.3% Leaderboard | Same | |
| Kimi K2.7 Code | MLS-Bench | 35.1% MLS Bench Lite | 35.1% Leaderboard, Kimi-Code | Same | |
| Kimi K3 | MLS-Bench | 48.3% MLS-Bench-Lite | 48.3% Leaderboard, max, Kimi-Code | Same | |
| Qwen 3.8 Max | MLS-Bench | 41% MLS-Bench-Lite | 41% Leaderboard, Claude Code | Same | |
| MiniMax-M2.7 | MM-ClawBench | 62.7% MM-ClawBench (MM Claw) | 62.7% Leaderboard | Same | |
| MiniMax-M2.5 | MM-ClawBench | 57.6% MM Claw (Table 4) | 57.6% Leaderboard | Same | |
| Kimi-VL-A3B-Thinking-2506 | MMLongBench-Doc | 42.1% MMLongBench-DOC (Acc) | 42.1% Leaderboard, VL; 2.8B activated (16B total) | Same | |
| GLM-4.1V-9B-Thinking | MMLongBench-Doc | 42.4% MMLongBench-Doc | 42.4% Leaderboard, VL; 9B | Same | |
| GLM-4.5V | MMLongBench-Doc | 44.7% MMLongBench-Doc | 44.7% Leaderboard, VL; 12B activated (106B total) | Same | |
| Qwen3-VL-235B-A22B | MMLongBench-Doc | 56.2% MMLongBench-Doc | 56.2% Leaderboard, VL; 22B activated (235B total) | Same | |
| GLM-4.6V | MMLongBench-Doc | 54.9% MMLongBench-Doc | 54.9% Leaderboard, VL; 12B activated (106B total) | Same | |
| Qwen3.5 397B-A17B | MMLongBench-Doc | 61.5% MMLongBench-Doc | 61.5% Leaderboard, VL; 17B activated (397B total) | Same | |
| Llama 3.1-405B | MMLU-Pro | 73.3% MMLU-Pro (5-shot, CoT) | 73.3% Leaderboard | Same | |
| Claude 3.5 Sonnet (October 2024) | MMLU-Pro | 78% MMLU Pro (0-shot CoT) | 78% Leaderboard | Same | |
| Phi-4 | MMLU-Pro | 70.4% MMLUPro | 70.4% Leaderboard | Same | |
| InternLM3-8B-Instruct | MMLU-Pro | 57.6% MMLU-Pro(0-shot) | 57.6% Leaderboard | Same | |
| MiniMax-Text-01 | MMLU-Pro | 75.7% MMLU-Pro* | 75.7% Leaderboard | Same | |
| Gemini 2.0 Pro | MMLU-Pro | 79.1% MMLU-Pro | 79.1% Leaderboard | Same | |
| Gemini 2.0 Flash Feb 2025 | MMLU-Pro | 77.6% MMLU-Pro | 77.6% Leaderboard | Same | |
| Gemini 2.0 Flash-Lite | MMLU-Pro | 71.6% MMLU-Pro | 71.6% Leaderboard | Same | |
| Grok 3 | MMLU-Pro | 79.9% MMLU-pro [Grok 3 Beta, non-reasoning table] | 79.9% Leaderboard | Same | |
| Phi-4 Mini | MMLU-Pro | 52.8% MMLU-Pro (0-shot, CoT) | 52.8% Leaderboard | Same | |
| Hunyuan-TurboS | MMLU-Pro | 79% MMLU-pro | 79% Leaderboard | Same | |
| Gemma 3 27B | MMLU-Pro | 67.5% MMLU (Pro) 0-shot (IT); PT MMLU (Pro COT) 5-shot = 52.2 | 67.5% Leaderboard | Same | |
| Hunyuan-T1 | MMLU-Pro | 87.2% MMLU PRO | 87.2% Leaderboard | Same | |
| Llama 4 Maverick | MMLU-Pro | 80.5% MMLU Pro, 0-shot, macro_avg/acc | 80.5% Leaderboard | Same | |
| Llama 4 Scout | MMLU-Pro | 74.3% MMLU Pro, 0-shot, macro_avg/acc | 74.3% Leaderboard | Same | |
| Seed-Thinking-v1.5 | MMLU-Pro | 87% MMLU-PRO | 87% Leaderboard | Same | |
| MiMo-7B-RL | MMLU-Pro | 58.6% MMLU-Pro (EM) | 58.6% Leaderboard | Same | |
| Phi-4-Reasoning-plus | MMLU-Pro | 76% MMLUPro | 76% Leaderboard | Same | |
| Phi-4-reasoning | MMLU-Pro | 74.3% MMLUPro | 74.3% Leaderboard | Same | |
| MiniMax-M1-80k | MMLU-Pro | 81.1% MMLU-Pro | 81.1% Leaderboard | Same | |
| ERNIE-4.5-300B-A47B | MMLU-Pro | 78.4% MMLU-Pro | 78.4% Leaderboard | Same | |
| Intern-S1 | MMLU-Pro | 83.5% MMLU-Pro | 83.5% Leaderboard | Same | |
| GLM-4.5 | MMLU-Pro | 84.6% MMLU Pro | 84.6% Leaderboard | Same | |
| seed-oss-36b-instruct | MMLU-Pro | 82.7% MMLU-Pro | 82.7% Leaderboard | Same | |
| DeepSeek-V3.1 | MMLU-Pro | 84.8% MMLU-Pro (EM) | 84.8% Leaderboard | Same | |
| MiniMax-M2 | MMLU-Pro | 82% MMLU-Pro (AA) | 82% Leaderboard | Same | |
| DeepSeek-V3.2 | MMLU-Pro | 85% MMLU-Pro (EM) | 85% Leaderboard | Same | |
| Nemotron 3 Nano 30B-A3B | MMLU-Pro | 78.3% MMLU-Pro | 78.3% Leaderboard, bf16 | Same | |
| MiniMax-M2.1 | MMLU-Pro | 88% MMLU-Pro | 88% Leaderboard | Same | |
| Qwen3-Max | MMLU-Pro | 85.7% MMLU-Pro | 85.7% Leaderboard | Same | |
| Seed2.0 Pro | MMLU-Pro | 87% MMLU-Pro | 87% Leaderboard | Same | |
| Qwen3.5 397B-A17B | MMLU-Pro | 87.8% MMLU-Pro | 87.8% Leaderboard | Same | |
| Qwen3.5-122B-A10B | MMLU-Pro | 86.7% MMLU-Pro | 86.7% Leaderboard | Same | |
| Qwen3.5-27B | MMLU-Pro | 86.1% MMLU-Pro | 86.1% Leaderboard | Same | |
| Qwen3.5-35B-A3B | MMLU-Pro | 85.3% MMLU-Pro | 85.3% Leaderboard | Same | |
| Qwen3.5-9B | MMLU-Pro | 82.5% MMLU-Pro | 82.5% Leaderboard | Same | |
| Qwen3.5-4B | MMLU-Pro | 79.1% MMLU-Pro | 79.1% Leaderboard | Same | |
| Gemma 3 12B | MMLU-Pro | 60.6% MMLU-Pro, IT, zero-shot (Table 6) | 60.6% Leaderboard | Same | |
| Gemma 3 1B | MMLU-Pro | 14.7% MMLU-Pro, IT, zero-shot (Table 6) | 14.7% Leaderboard | Same | |
| Gemma 3 4B | MMLU-Pro | 43.6% MMLU-Pro, IT, zero-shot (Table 6) | 43.6% Leaderboard | Same | |
| GLM-4.5-Air | MMLU-Pro | 81.4% MMLU Pro (Table 4) | 81.4% Leaderboard | Same | |
| Claude 3 Opus | MMMU | 59.4% MMMU (val) Overall | 59.4% Leaderboard | Same | |
| GPT-4o May 2024 | MMMU | 69.1% MMMU (%) (val) | 69.1% Leaderboard | Same | |
| Gemini 1.5 Pro May 2024 | MMMU | 62.2% MMMU (val), 0-shot | 62.2% Leaderboard | Same | |
| Claude 3.5 Sonnet | MMMU | 68.3% MMMU (validation) | 68.3% Leaderboard | Same | |
| GPT-4o mini | MMMU | 59.4% MMMU | 59.4% Leaderboard | Same | |
| Gemini 2.0 Pro | MMMU | 72.7% MMMU | 72.7% Leaderboard | Same | |
| Gemini 2.0 Flash Feb 2025 | MMMU | 71.7% MMMU | 71.7% Leaderboard | Same | |
| Gemini 2.0 Flash-Lite | MMMU | 68% MMMU | 68% Leaderboard | Same | |
| Grok 3 | MMMU | 78% MMMU (Grok 3 Think; pass@1 = 76) | 78% Leaderboard | Same | |
| Claude 3.7 Sonnet | MMMU | 75% Visual reasoning MMMU (validation) (64K extended thinking) | 75% Leaderboard | Same | |
| GPT-4.5 | MMMU | 74.4% MMMU (multimodal) | 74.4% Leaderboard | Same | |
| Gemma 3 27B | MMMU | 64.9% MMMU (val) (IT); PT MMMU = 56.1 | 64.9% Leaderboard | Same | |
| Llama 4 Behemoth | MMMU | 76.1% MMMU | 76.1% Leaderboard | Same | |
| Llama 4 Maverick | MMMU | 73.4% MMMU, 0-shot, accuracy | 73.4% Leaderboard | Same | |
| Llama 4 Scout | MMMU | 69.4% MMMU, 0-shot, accuracy | 69.4% Leaderboard | Same | |
| o3 | MMMU | 82.9% MMMU College-level visual problem-solving | 82.9% Leaderboard | Same | |
| o4-mini | MMMU | 81.6% MMMU | 81.6% Leaderboard | Same | |
| Amazon Nova Premier | MMMU | 68% MMMU | 68% Leaderboard | Same | |
| Seed1.5-VL | MMMU | 77.9% MMMU | 77.9% Leaderboard, thinking | Same | |
| Claude Opus 4 | MMMU | 76.5% Visual reasoning MMMU (validation) | 76.5% Leaderboard | Same | |
| Claude Sonnet 4 | MMMU | 74.4% Visual reasoning MMMU (validation) | 74.4% Leaderboard | Same | |
| Seed1.6-Thinking | MMMU | 74.8% MMMU | 74.8% Leaderboard | Same | |
| GLM-4.1V-9B-Thinking | MMMU | 68% MMMU | 68% Leaderboard, thinking | Same | |
| Intern-S1 | MMMU | 77.7% MMMU | 77.7% Leaderboard | Same | |
| Claude Opus 4.1 | MMMU | 77.1% Visual reasoning MMMU (validation) | 77.1% Leaderboard | Same | |
| GPT-5 | MMMU | 84.2% MMMU College-level visual problem-solving | 84.2% Leaderboard, thinking | Same | |
| GLM-4.5V | MMMU | 75.4% MMMU (val) | 75.4% Leaderboard, thinking | Same | |
| Claude Sonnet 4.5 | MMMU | 77.8% Visual reasoning MMMU (validation) | 77.8% Leaderboard | Same | |
| GPT-5.1 | MMMU | 85.4% MMMU | 85.4% Leaderboard | Same | |
| Claude Opus 4.5 | MMMU | 80.7% Visual reasoning MMMU (validation) | 80.7% Leaderboard | Same | |
| Claude 3 Haiku | MMMU | 50.2% MMMU (val), Overall, 0-shot. Per-discipline values also given (Table 3) | 50.2% Leaderboard | Same | |
| Claude 3 Sonnet | MMMU | 53.1% MMMU (val), Overall, 0-shot. Per-discipline values also given (Table 3) | 53.1% Leaderboard | Same | |
| Phi-3.5-vision-instruct | MMMU | 43% MMMU (val), 0-shot (Table 5) | 43% Leaderboard | Same | |
| Gemma 3 12B | MMMU | 59.6% MMMU (val), IT (Table 6 and Table 16) | 59.6% Leaderboard | Same | |
| Gemma 3 4B | MMMU | 48.8% MMMU (val), IT (Table 6 and Table 16) | 48.8% Leaderboard | Same | |
| Seed1.5-VL | MMMU-Pro | 67.6% MMMU-Pro | 67.6% Leaderboard, thinking | Same | |
| Seed1.6-Thinking | MMMU-Pro | 66.4% MMMU-pro | 66.4% Leaderboard | Same | |
| GLM-4.1V-9B-Thinking | MMMU-Pro | 57.1% MMMU-Pro | 57.1% Leaderboard, thinking | Same | |
| GPT-5 | MMMU-Pro | 78.4% MMMU Pro*** Graduate-level visual problem-solving | 78.4% Leaderboard, thinking | Same | |
| GLM-4.5V | MMMU-Pro | 65.2% MMMU Pro | 65.2% Leaderboard, thinking | Same | |
| Gemini 3 Pro | MMMU-Pro | 81% MMMU-Pro | 81% Leaderboard | Same | |
| Claude Opus 4.6 | MMMU-Pro | 77.3% Visual reasoning MMMU Pro (with tools) | 77.3% Leaderboard, with tools | Same | |
| Claude Sonnet 4.6 | MMMU-Pro | 75.6% Visual reasoning MMMU-Pro (with tools) | 75.6% Leaderboard, with tools | Same | |
| Gemini 3.1 Pro | MMMU-Pro | 80.5% MMMU-Pro (No tools) | 80.5% Leaderboard, thinking, high | Same | |
| Gemma 4 31B IT | MMMU-Pro | 76.9% MMMU Pro | 76.9% Leaderboard | Same | |
| Gemma 4 26B A4B | MMMU-Pro | 73.8% MMMU Pro | 73.8% Leaderboard | Same | |
| Gemma 4 E2B | MMMU-Pro | 44.2% MMMU Pro | 44.2% Leaderboard | Same | |
| Gemma 4 E4B | MMMU-Pro | 52.6% MMMU Pro | 52.6% Leaderboard | Same | |
| Muse Spark | MMMU-Pro | 80.4% MMMU Pro (Multimodal Understanding) | 80.4% Leaderboard, thinking | Same | |
| Gemini Robotics ER 2 | Moment finding (Google DeepMind) | 91.3% Moment-finding accuracy (0.96s mean absolute distance) | 91.3% Leaderboard | Same | |
| Qwen2-72B | Multilingual human evaluation | 3.93 Human multilingual evaluation (Average, 1-5) | 3.93 Leaderboard | Same | |
| MiniMax-M2.1 | OctoCodingbench | 26.1% OctoCodingbench | 26.1% Leaderboard | Same | |
| Qwen3.5-Omni-Plus | Omni-Cloze | 64.8% Omni-Cloze | 64.8% Leaderboard | Same | |
| Qwen3.5-Omni-Flash | Omni-Cloze | 63% Omni-Cloze, Qwen3.5-Omni-Flash | 63% Leaderboard | Same | |
| Qwen2.5-Omni-7B | OmniBench | 56.1% OmniBench Avg (Speech 55.25 / Sound Event 60.00 / Music 52.83) | 56.1% Leaderboard, image-audio | Same | |
| Qwen3.5-Omni-Plus | OmniGAIA | 57.2% OmniGAIA (judged by deepseek-v3.2-thinking) | 57.2% Leaderboard | Same | |
| Qwen3.5-Omni-Flash | OmniGAIA | 33.9% OmniGAIA without thinking prompt, Qwen3.5-Omni-Flash | 33.9% Leaderboard | Same | |
| Gemini 2.5 Computer Use | Online-Mind2Web | 69% Online-Mind2Web, official leaderboard (Browserbase 65.7) | 69% Leaderboard, Google Computer Use (09-2025) | Same | |
| Qwen3.7-Plus | OSWorld-Verified | 73.3% OSWorld-Verified (enable_thinking=False) | 73.3% Leaderboard, 100 steps | Same | |
| Kimi K2.5 | OSWorld-Verified | 63.3% OSWorld-Verified, GUI actions only (Table 4) | 63.3% Leaderboard, 100 steps | Same | |
| Kimi K3 | PerceptionBench (Moonshot) | 58.5% PerceptionBench | 58.5% Leaderboard | Same | |
| Qwen3-1.7B | PolyMath | 25.2% PolyMath, thinking mode (Table 19). Non-thinking 10.3 (Table 20) | 25.2% Leaderboard, thinking | Same | |
| Qwen3-14B | PolyMath | 45.8% PolyMath, thinking mode (Table 15). Non-thinking 22.0 (Table 16) | 45.8% Leaderboard, thinking | Same | |
| Qwen3-30B-A3B | PolyMath | 46.1% PolyMath, thinking mode (Table 15). Non-thinking 23.3 (Table 16) | 46.1% Leaderboard, thinking | Same | |
| Qwen3-32B | PolyMath | 47.4% PolyMath, thinking mode (Table 13). Non-thinking 22.5 (Table 14) | 47.4% Leaderboard, thinking | Same | |
| Qwen3-4B | PolyMath | 40% PolyMath, thinking mode (Table 17). Non-thinking 16.6 (Table 18) | 40% Leaderboard, thinking | Same | |
| Qwen3-8B | PolyMath | 42.7% PolyMath, thinking mode (Table 17). Non-thinking 18.8 (Table 18) | 42.7% Leaderboard, thinking | Same | |
| Gemini Robotics ER 2 | Progress classification (Google DeepMind) | 57.4% Progress classification (five bands) | 57.4% Leaderboard | Same | |
| Qwen 3.8 Max | QwenBlenderBench | 69.9% QwenBlenderBench | 69.9% Leaderboard | Same | |
| Qwen 3.8 Max | QwenQoderBench | 58.4% QwenQoderBench | 58.4% Leaderboard | Same | |
| Qwen 3.8 Max | QwenReactBench | 1,724 QwenReactBench | 1,724 Leaderboard | Same | |
| Qwen3.7-Max | QwenSVG | 1,608 QwenSVG | 1,608 Leaderboard | Same | |
| Qwen3.7-Plus | QwenSVG | 1,588 QwenSVG | 1,588 Leaderboard | Same | |
| Qwen 3.8 Max | QwenSVGBench | 1,713 QwenSVGBench | 1,713 Leaderboard | Same | |
| Qwen 3.8 Max | QwenSWEBench | 80.7% QwenSWEBench | 80.7% Leaderboard | Same | |
| Qwen3.7-Plus | QwenVision2Code | 1,772 QwenVision2Code | 1,772 Leaderboard | Same | |
| Qwen 3.8 Max | QwenVisualOffice | 44.6% QwenVisualOffice | 44.6% Leaderboard | Same | |
| Qwen3.7-Max | QwenWebDev | 1,568 QwenWebDev | 1,568 Leaderboard | Same | |
| Qwen3.7-Plus | QwenWebDev | 1,536 QwenWebDev | 1,536 Leaderboard | Same | |
| Qwen3.7-Plus | QwenWorldBench | 62.1% QwenWorldBench | 62.1% Leaderboard | Same | |
| Cosmos3-Nano | RBench | 58.4% Cosmos3-Nano image-to-video RBench score, Table 12 | 58.4% Leaderboard, GPT judge | Same | |
| Gemini 4 Carbon | Riemann-bench | 80% RiemannBench | 80% Leaderboard, high | Same | |
| Qwen3-VL-235B-A22B | RoboSpatial-Home | 73.9% RoboSpatialHome | 73.9% Leaderboard, thinking | Same | |
| Qwen2.5-14B-Instruct-1M | RULER | 95.7% RULER Avg. (4K to 128K) | 95.7% Leaderboard | Same | |
| Qwen3-14B | RULER | 94.6% RULER Avg. (4K to 128K, YaRN x4), non-thinking mode, 128K 85.1. Thinking mode Avg. 90.1 with 8192-token thinking budget (Table 23) | 94.6% Leaderboard | Same | |
| Qwen3-235B-A22B | RULER | 95% RULER Avg. (4K to 128K, YaRN x4), non-thinking mode, 128K 90.6. Thinking mode Avg. 92.2 with 8192-token thinking budget (Table 23) | 95% Leaderboard | Same | |
| Qwen3-30B-A3B | RULER | 91.6% RULER Avg. (4K to 128K, YaRN x4), non-thinking mode, 128K 79.2. Thinking mode Avg. 86.6 with 8192-token thinking budget (Table 23) | 91.6% Leaderboard | Same | |
| Qwen3-32B | RULER | 93.7% RULER Avg. (4K to 128K, YaRN x4), non-thinking mode, 128K 85.6. Thinking mode Avg. 91.0 with 8192-token thinking budget (Table 23) | 93.7% Leaderboard | Same | |
| Qwen3-4B | RULER | 85.2% RULER Avg. (4K to 128K, YaRN x4), non-thinking mode, 128K 66.0. Thinking mode Avg. 83.5 with 8192-token thinking budget (Table 23) | 85.2% Leaderboard | Same | |
| Qwen3-8B | RULER | 89.1% RULER Avg. (4K to 128K, YaRN x4), non-thinking mode, 128K 77.4. Thinking mode Avg. 84.4 with 8192-token thinking budget (Table 23) | 89.1% Leaderboard | Same | |
| LongCat-Flash-Thinking-2601 | RWSearch | 79.5% RW Search (Pass@1) | 79.5% Leaderboard | Same | |
| Seed2.1 Pro | SeedClawBench | 66.6% SeedClawBench (blog: ClawBench) | 66.6% Leaderboard | Same | |
| o3-mini | SimpleQA | 13.8% SimpleQA | 13.8% Leaderboard, high | Same | |
| GPT-4.5 | SimpleQA | 62.5% SimpleQA Accuracy (higher is better) | 62.5% Leaderboard | Same | |
| Gemini 3 Pro | SimpleQA Verified | 72.1% SimpleQA Verified | 72.1% Leaderboard | Same | |
| InternVL3.5-241B-A28B | SpaCE-10 | 55% SpaCE-10 | 55% Leaderboard | Same | |
| Step 5 Preview | StepCodeBench | 49% StepCodeBench (avg@4, internal) | 49% Leaderboard, avg@4; high | Same | |
| Inkling 2 Small | sudo L7 | 14.1% Sudo L7, 14.1% | 14.1% Leaderboard, xhigh | Same | |
| Muse Spark 1.1 | SWE-Bench Pro | 61.5% SWE-Bench Pro (Diverse software engineering) | 61.5% Leaderboard, mini-SWE-agent | Same | |
| Amazon Nova Premier | SWE-bench Verified | 42.4% SWE-Bench Verified (internal agentic scaffold) | 42.4% Leaderboard, Amazon Nova Premier 1.0 | Same | |
| Devstral Small 1.0 | SWE-bench Verified | 46.8% SWE-Bench Verified (OpenHands scaffold) | 46.8% Leaderboard, OpenHands | Same | |
| Qwen3-Coder-480B-A35B | SWE-bench Verified | 69.6% SWE-bench Verified w/ OpenHands, 500 turns | 69.6% Leaderboard, OpenHands | Same | |
| GLM-4.5 | SWE-bench Verified | 64.2% SWE-bench Verified | 64.2% Leaderboard, Undisclosed | Same | |
| Claude 3.5 Haiku | SWE-bench Verified | 40.6% SWE-bench Verified, % of problems which pass all tests, pass@1 (Table 2) | 40.6% Leaderboard, Tools | Same | |
| GLM-5.2 | SWE-Marathon | 13% SWE-Marathon | 13% Leaderboard, Claude Code | Same | |
| Grok 4.5 | SWE-Marathon | 29% SWE Marathon resolution rate (pass@1) | 29% Leaderboard, Grok Build | Same | |
| Inkling 2 Small | SWE-Marathon v1.1 | 38.8% SWE-Marathon v1.1, 38.8% | 38.8% Leaderboard, xhigh, Claude Code | Same | |
| MiniMax-M2.1 | SWE-Review | 8.90% SWE-Review | 8.90% Leaderboard | Same | |
| DeepSeek-V3.2 | Toolathlon | 35.2% Tool-Decathlon (Pass@1) | 35.2% Leaderboard | Same | |
| Gemini 3 Flash | Toolathlon | 49.4% Toolathlon | 49.4% Leaderboard | Same | |
| GLM-5 | Toolathlon | 39.2% Tool-Decathlon (Table 7) | 39.2% Leaderboard | Same | |
| Qwen3.5 397B-A17B | Toolathlon | 38.3% Tool Decathlon | 38.3% Leaderboard | Same | |
| GPT-5.4 | Toolathlon | 54.6% Toolathlon | 54.6% Leaderboard, xhigh | Same | |
| GPT-5.4 Mini | Toolathlon | 42.9% Toolathlon | 42.9% Leaderboard | Same | |
| GPT-5.4 Nano | Toolathlon | 35.5% Toolathlon | 35.5% Leaderboard, xhigh | Same | |
| MiniMax-M2.7 | Toolathlon | 46.3% Toolathlon (Toolathon in text) | 46.3% Leaderboard | Same | |
| Qwen 3.6 Plus | Toolathlon | 39.8% Tool Decathlon | 39.8% Leaderboard | Same | |
| GLM-5.1 | Toolathlon | 40.7% Tool-Decathlon | 40.7% Leaderboard | Same | |
| Qwen 3.6 35B-A3B | Toolathlon | 26.9% Tool Decathlon | 26.9% Leaderboard | Same | |
| Kimi K2.6 | Toolathlon | 50% Toolathlon | 50% Leaderboard | Same | |
| GPT-5.5 | Toolathlon | 55.6% Toolathlon | 55.6% Leaderboard, xhigh | Same | |
| Gemini 3.5 Flash | Toolathlon | 56.5% Toolathlon | 56.5% Leaderboard | Same | |
| MiniMax-M2.5 | Toolathlon | 38.3% Toolathlon (Table 4) | 38.3% Leaderboard | Same | |
| Muse Spark 1.1 | Toolathlon-Verified | 75.6% Toolathlon-Verified (Personal tool use) | 75.6% Leaderboard, xhigh | Same | |
| Inkling | Toolathlon-Verified | 45.5% Toolathlon Verified | 45.5% Leaderboard, xhigh | Same | |
| Kimi K3 | Toolathlon-Verified | 76.5% Toolathlon-Verified | 76.5% Leaderboard, max | Same | |
| Inkling-Small | Toolathlon-Verified | 54.4% Toolathlon Verified | 54.4% Leaderboard, xhigh | Same | |
| GLM-5.3-Flash | Toolathlon-Verified | 78.4% Toolathlon Verified | 78.4% Leaderboard, max | Same | |
| Qwen 3.6 Max (Preview) | ToolcallFormatIFBench | 86.1% ToolcallFormatIFBench Real-World Toolcall Following | 86.1% Leaderboard | Same | |
| Inkling 2 Small | Excel Modeling Benchmark v1.1 | 69.5% Excel Modeling Benchmark v1.1, 69.5% | 69.5% Leaderboard | Same | |
| Gemini 4 Argon | Vals Finance Agent v2 | 65.4% Vals Finance Agent v2 | 65.4% Leaderboard | Same | |
| Claude Fable 5 | Vals Finance Agent v2 | 56.3% Finance Agent Benchmark v2, run by Vals AI, adaptive thinking at max effort (8.17.2) | 56.3% Leaderboard | Same | |
| Gemini 4 Argon | Vals Index v2.1 | 68.9% Vals Index | 68.9% Leaderboard | Same | |
| Kimi K2 Jul 2025 | Vectara Hallucination Leaderboard (HHEM) | 1.10% HHEM v2.1 (1-Hallu.), hallucination rate 1.1% (Table 3) | 1.10% Leaderboard | Same | |
| Grok 4 | Vending-Bench | $4,694 Vending-Bench net worth | $4,694 Leaderboard | Same | |
| Gemini 3 Pro | Vending-Bench 2 | $5,478 Vending-Bench 2 (Net worth (mean)) | $5,478 Leaderboard | Same | |
| GLM-5 | Vending-Bench 2 | $4,432 Vending Bench 2 | $4,432 Leaderboard | Same | |
| GLM-5.1 | Vending-Bench 2 | $5,634 Vending Bench 2 | $5,634 Leaderboard | Same | |
| Claude Opus 4.5 | Vending-Bench 2 | $4,967 Vending-Bench 2 final balance, effort high, 8,192 reasoning tokens per turn (2.11) | $4,967 Leaderboard | Same | |
| Claude Opus 4.6 | Vending-Bench 2 | $8,018 Vending-Bench 2 final balance, effort high (2.15) | $8,018 Leaderboard | Same | |
| Claude Sonnet 4.6 | Vending-Bench 2 | $7,204 Vending-Bench 2 final balance, max effort; $6,625.10 at high effort (2.13) | $7,204 Leaderboard | Same | |
| Claude Fable 5 | Vending-Bench 2 | $5,680 Vending-Bench 2 final balance at high effort, Fable 5's best effort level (corrected from max effort in the June 11 changelog) (8.17.6) | $5,680 Leaderboard, high | Same | |
| MiniMax-M2.1 | VIBE (MiniMax) | 88.6% VIBE (Average) | 88.6% Leaderboard | Same | |
| Gemini 2.5 Pro Jun 2025 | Video-MMMU | 83.6% VideoMMMU | 83.6% Leaderboard | Same | |
| GPT-5 | Video-MMMU | 84.6% VideoMMMU Video-based multimodal reasoning (max frame 256) | 84.6% Leaderboard | Same | |
| GLM-5.3-Flash | Vision2Web | 77.8% Vision2Web | 77.8% Leaderboard, Claude Code | Same | |
| Seed1.5-VL | VisuLogic | 35% VisuLogic | 35% Leaderboard, thinking | Same | |
| Qwen3-VL-235B-A22B | VisuLogic | 34.4% VisuLogic | 34.4% Leaderboard, thinking | Same | |
| LongCat-Flash-Thinking-2601 | VITA-Bench | 29.3% VitaBench (Avg@4) | 29.3% Leaderboard, thinking | Same | |
| Fara1.5-27B | WebTailBench | 40.2% WebTailBench | 40.2% Leaderboard, v1.5 | Same | |
| Muse Glimmer | WildClawBench | 47.6% WildClawBench | 47.6% Leaderboard, OpenClaw | Same | |
| Qwen3.5-Omni-Plus | WorldSense (omnimodal) | 62.8% WorldSense | 62.8% Leaderboard, modality A+V | Same | |
| Nemotron 3 Nano Omni 30B-A3B | WorldSense (omnimodal) | 55.4% World Sense (Video + Audio Q/A) | 55.4% Leaderboard, modality A+V | Same | |
| Kimi K2.5 | WorldVQA | 46.3% WorldVQA | 46.3% Leaderboard | Same | |
| Grok 4.1 Fast | X Browse (xAI) | 56.3% X Browse (internal, Agent Tools API) | 56.3% Leaderboard, Agent Tools API | Same | |
| Seed2.1 Pro | xDailyBench | 61% xDailyBench | 61% Leaderboard | Same | |
| Kimi K3.1 Pro | xdev-bench-hard | 81% xdev-bench-hard (Internal, pass@3) | 81% Leaderboard, kimi-code | Same | |
| GLM-5.3-Flash | Z.ai Code Bench | 29% Z.ai Code Bench v1.0, 29.0 | 29% Leaderboard, max, Claude Code 2.1.207 | Same | |
| Muse Spark | ZeroBench | 33% ZeroBench (Multi-Step Visual Reasoning (pass@5) - With Python) | 33% Leaderboard, w/ tools; externally reported: Muse Spark methodology; Sandboxed Python tools; 5 samplings, graded by an LLM judge. | Same | |
| Qwen 3.8 Max | ZeroBench | 49% Best of ZeroBench (Pass@5) (without CI / with CI) 24.0 / 49.0 / ZeroBench-Sub | 49% Leaderboard, w/ tools; externally reported: Qwen3.8 release; Code-interpreter tools; 5 samplings. | Same | |
| DeepSeek-V4-Flash-Vision-Exp | ZeroBench | 35% ZeroBench (Pass@5) | 35% Leaderboard, externally reported: DeepSeek-V4-Flash-Vision-Exp release note; Tool use unclear; 5 samplings; values from chart image. | Same | |
| DeepSeek V4.1 Flash | ZeroBench | 49% ZeroBench-main w/ tools (Pass@5) | 49% Leaderboard, w/ tools; externally reported: DeepSeek-V4.1-Flash model card; Claude Code harness tools; 5 samplings. | Same |