ABC-Bench
Coding agents take a real backend repository, edit the code, set up the environment and deploy the service in a container. The 224 tasks come from 127 open-source repositories in 8 languages and 19 frameworks. A task passes only when the running service passes external end-to-end API tests.
Not related to SecureBio's ABC Bench records, which share the name. 92 of the 224 tasks require the agent to configure the environment on its own. The paper had 67 Hugging Face upvotes and the repository about 40 GitHub stars on November 5th, 2026.
- Made by
- OpenMOSS (Fudan University)
- Released
- January 2026
- Kind
- Fixing real repositories
- Level
- Expert
- Scored
- Checked automatically
- Answers
- Agent task
- Tasks
- All public
- Strongest model tested
- GPT-5 #70 on the capability index
- Last model added
- December 2025
- Scores refreshed
- November 12th, 2026
In the authors’ words
The evolution of Large Language Models (LLMs) into autonomous agents has expanded the scope of AI coding from localized code generation to complex, repository-level, and execution-driven problem solving. However, current benchmarks predominantly evaluate code logic in static contexts, neglecting the dynamic, full-process requirements of real-world engineering, particularly in backend development which demands rigorous environment configuration and service deployment. To address this gap, we introduce ABC-Bench, a benchmark explicitly designed to evaluate agentic backend coding within a realistic, executable workflow. Using a scalable automated pipeline, we curated 224 practical tasks spanning 8 languages and 19 frameworks from open-source repositories. Distinct from previous evaluations, ABC-Bench require the agents to manage the entire development lifecycle from repository exploration to instantiating containerized services and pass the external end-to-end API tests. Our extensive evaluation reveals that even state-of-the-art models struggle to deliver reliable performance on these holistic tasks, highlighting a substantial disparity between current model capabilities and the demands of practical backend engineering. Our code is available at https://github.com/OpenMOSS/ABC-Bench.
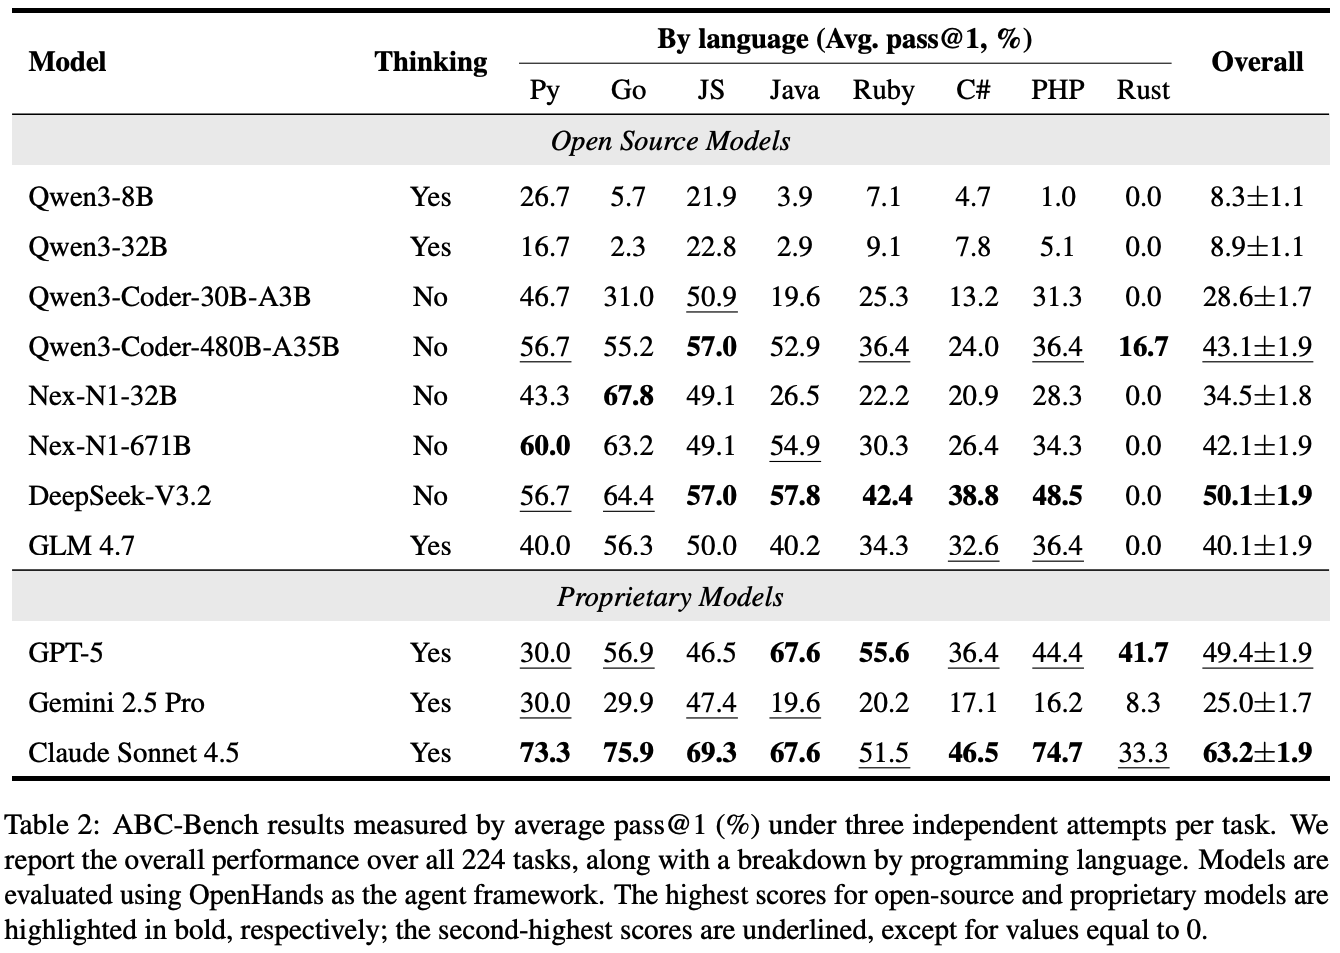
Claude Sonnet 4.5 leads with 63.2% among models released by December 2025
Best score per entry from the benchmark's own leaderboard, read on November 12th, 2026. Where a model ran with several settings or harnesses, we keep its best. Names in gray aren't in our model list: fine-tunes, agent systems, products and older models. They don't count toward leaders.
The newest model with a score here came out in December 2025, and nobody has tested a newer one. Among the 20 highest-ranked models on the capability index, these have no score yet:
- Claude Fable 5.2
-
 Gemini 4 Carbon
- GPT-6 Astra
- Claude Opus 5.5
- and 16 more
- 1 Claude Sonnet 4.5 thinking on 63.2%
- 2
 DeepSeek-V3.2 thinking off 50.1%
- 3 GPT-5 thinking on 49.4%
- 4
 Qwen3-Coder-480B-A35B thinking off 43.1%
- 5 Nex-N1-671B thinking off 42.1%
- 6 GLM-4.7 thinking on 40.1%
- 7 Nex-N1-32B thinking off 34.5%
- 8 Qwen3-Coder-30B-A3B thinking off 28.6%
- 9 Gemini 2.5 Pro (snapshot unspecified) thinking on 25%
- 10 Qwen3-32B thinking on 8.90%
- 11 Qwen3-8B thinking on 8.30%
Source: Official ABC-Bench leaderboard
| # | Entry | Score | Setting | Date | Source |
|---|---|---|---|---|---|
| 1 | Claude Sonnet 4.5 | 63.2% | thinking on, OpenHands | Sep 2025 | Official leaderboard |
| 2 | DeepSeek-V3.2 | 50.1% | thinking off, OpenHands | Dec 2025 | Official leaderboard |
| 3 | GPT-5 | 49.4% | thinking on, OpenHands | Aug 2025 | Official leaderboard |
| 4 | Qwen3-Coder-480B-A35B | 43.1% | thinking off, OpenHands | Jul 2025 | Official leaderboard |
| 5 | Nex-N1-671B | 42.1% | thinking off, OpenHands | Official leaderboard | |
| 6 | GLM-4.7 | 40.1% | thinking on, OpenHands | Dec 2025 | Official leaderboard |
| 7 | Nex-N1-32B | 34.5% | thinking off, OpenHands | Official leaderboard | |
| 8 | Qwen3-Coder-30B-A3B | 28.6% | thinking off, OpenHands | Official leaderboard | |
| 9 | Gemini 2.5 Pro (snapshot unspecified) | 25% | thinking on, OpenHands | Official leaderboard | |
| 10 | Qwen3-32B | 8.90% | thinking on, OpenHands | Apr 2025 | Official leaderboard |
| 11 | Qwen3-8B | 8.30% | thinking on, OpenHands | Apr 2025 | Official leaderboard |
Number one over time
Lab claims count from the day the card came out, independent runs from the model’s release.
Source: Official ABC-Bench leaderboard
Scores over time
All the scores we have, one dot each, so a model tested at several settings appears more than once.
Source: Official ABC-Bench leaderboard
No lab model card reports it yet
We read the headline results of 522 launch posts from 52 labs, and none of them list this benchmark.
More in Coding
- SWE-bench Verified In use 500 human-validated GitHub issues from 12 Python repos. Agent writes a patch that must pass hidden tests. Claude Opus 4.7 83.5%
- LiveCodeBench v6 In use Competitive programming problems collected after model cutoffs from LeetCode, AtCoder, Codeforces. Scored pass@1 on hidden tests. DeepSeek-V4-Pro 93.5%
- SWE-bench Multilingual In use 300 GitHub-issue tasks across nine programming languages in SWE-bench format. Patch graded by repository tests. Claude Fable 5.2 96.6%
- DeepSWE In use 113 original long-horizon engineering tasks across 91 repos and five languages, written from scratch. Hand-written verifiers accept alternative solutions. GPT-6 Astra 74.1%
- SciCode In use Scientist-curated research coding problems split into subproblems across natural sciences. Code checked against test cases.
 Seed2.1 Pro 59.8%
- Codeforces rating In use Model solves recent Codeforces contest problems. An Elo-style rating is computed from simulated contest performance. DeepSeek V4.1 Flash 3,471